@f
包豪斯风格现代主义海报:五艘帆船在蓝色海湾竞速,仅由圆形、三角形和矩形构成——红黄黑三原色帆、条纹钴蓝海面、巨大的红橙色太阳、白色码头,以及带丝网印刷颗粒感的米白纸张。
Five sailboats with bold triangular sails race across a calm blue bay toward a small harbor pier, drawn as a Bauhaus-style geometric poster built only from circles, triangles, rectangles, and straight lines. The sails are flat primary red, yellow, and black triangles, the hulls are slim black and white trapezoids, and a large red-orange sun circle sits low on the right above the horizon. The sea is layered horizontal bands of cobalt, navy, and pale blue, with small white semicircles for waves, and a few thin diagonal lines suggest wind. A simple white pier of stacked rectangles extends from the left edge, with a round black buoy in the foreground. Off-white textured paper background, crisp hard edges, flat colors with no gradients, subtle screen-print grain and slight ink misregistration, strong asymmetric balance and generous negative space in the sky. Modernist 1920s design spirit, clean and joyful. Wide landscape 16:9. No people, no text, no letters, no numbers, no logos.
十六世纪波斯细密画风格夜花园:一座绿松石穹顶亭阁立于长形倒影池畔,三位乐师在花纹地毯上演奏,杏树与石榴树、孔雀、青金石色夜空中的新月与金星、宝石颜料、金箔高光,以及描金藤蔓边框。
A small open garden pavilion with a turquoise-tiled dome stands beside a long rectangular reflecting pool where three musicians play a lute, a frame drum, and a reed flute on a patterned carpet, painted as a sixteenth-century Persian miniature. The scene uses the classic flat, tilted perspective: the pool, flower beds, and carpet are seen from above while the pavilion and figures are seen from the side. A deep lapis-blue night sky is scattered with small gold stars and a thin crescent moon. Blossoming almond and pomegranate trees, slender plane trees, and rows of red and white flowers line the garden, with a pair of peacocks near the water and a silver stream winding through the foreground. Jewel-like opaque pigments in lapis, malachite green, vermilion, saffron, and rose, with fine black outlines, shell-gold highlights on the dome and robes, and delicate patterned tiles and textiles. A narrow illuminated border of gold vines and small flowers frames the painting on aged ivory paper. Wide landscape 16:9. No text, no calligraphy, no letters, no logos.
为一张缆车穿越雪山山谷的主视觉镜头构建可直接用于图像和动态视频的简报:车厢与缆线、山谷与村庄、光线与氛围、固定细节、运动图谱,以及两个提示词种子:一个 16:9 静态图像和一个图生视频动画。
扮演一位电影级环境设计师,擅长撰写可直接用于图像和动态视频的场景简报。帮我设计一个单节缆车车厢穿越雪山山谷的主视觉镜头,这个镜头会先生成为静态图像,然后以该图像作为首帧动画化为一段短视频。你的简报必须让静态图像富含能够自然运动的元素(沿缆线滑行的车厢、飘动的云、飘落或飞扬的雪、烟囱炊烟、闪烁的光、飞鸟),同时保持构图平静、易于动画化。

我的初始选择:
- 山区与地貌:带有小村庄和松林的高山谷地
- 季节与时段:冬季日出
- 车厢类型与颜色:带大窗户的小型复古红色空中缆车车厢
- 视觉风格:写实旅行摄影
- 氛围词:清冽、静谧、金色、通透

首先用一条简短消息问我缺失的信息:我偏好的相机视角(从山脊横看山谷、从下方仰视车厢,或从附近山坡与车厢平视)、是否应可见山谷站或山顶站,以及需要避免的元素(人物、滑雪者、标志、标牌、滑雪缆车、现代建筑)。

然后按以下部分产出简报:

1. **场景概述**:用两三句话描述地点、季节、光线和这一刻的故事。

2. **缆车与缆线**:车厢形状、颜色、窗户布局、车顶吊架与行走机构、钢缆的数量与粗细、钢格构塔架(在画面中的位置、高度、颜色),以及车厢行驶方向。说明车厢悬挂在缆线下方并沿缆线移动,绝不脱离缆线。

3. **山谷与景观**:山峰及其形态、积雪与岩石、松林密度、下方村庄(房屋数量、屋顶颜色、教堂或木屋细节)、道路或冰封溪流,以及从前景到背景的景深层级。

4. **光线与氛围**:太阳方向与颜色、山峰上的日照金山、低云或山谷雾、空中细雪、烟囱炊烟,以及光线如何映照车厢窗户和缆线。

5. **固定视觉细节**:一个编号列表,列出 8 到 10 个在静态图像和视频中必须保持一致的细节(车厢颜色和位置、缆线角度、塔架侧别、山峰形态、村庄位置、太阳侧别、云层高度、相机位置、取景)。

6. **运动图谱**:一张表格,列出视频中所有可运动的元素,列为:元素、运动类型、方向、速度(极慢、慢、中),以及运动强度。包含相机运动。保持整体运动微妙且物理上合理。

7. **提示词种子 A - 主视觉静态图像**:一段可直接粘贴的图像提示词,少于 170 个单词,用于宽幅风景 16:9 画面,第一句包含车厢、缆线、塔架和雪山山谷,结尾为:无人物、无文字、无标牌、无标志。

8. **提示词种子 B - 图生视频动画**:一段可直接粘贴的视频提示词,少于 120 个单词,以主视觉静态图像为首帧,描述一个缓慢的相机运动和运动图谱中的自然运动,时长约 6 秒,并要求保持车厢、缆线、塔架、山脉和取景与图像完全一致,不新增物体。

规则:不以人物为主体,无文字、标牌或标志,无快速相机运动或剪辑,无破坏物理的运动(车厢以恒定慢速沿缆线平滑移动并仅轻微摆动,云层沿同一风向飘动,烟雾沿同一风向弯曲)。使用短段落和列表。
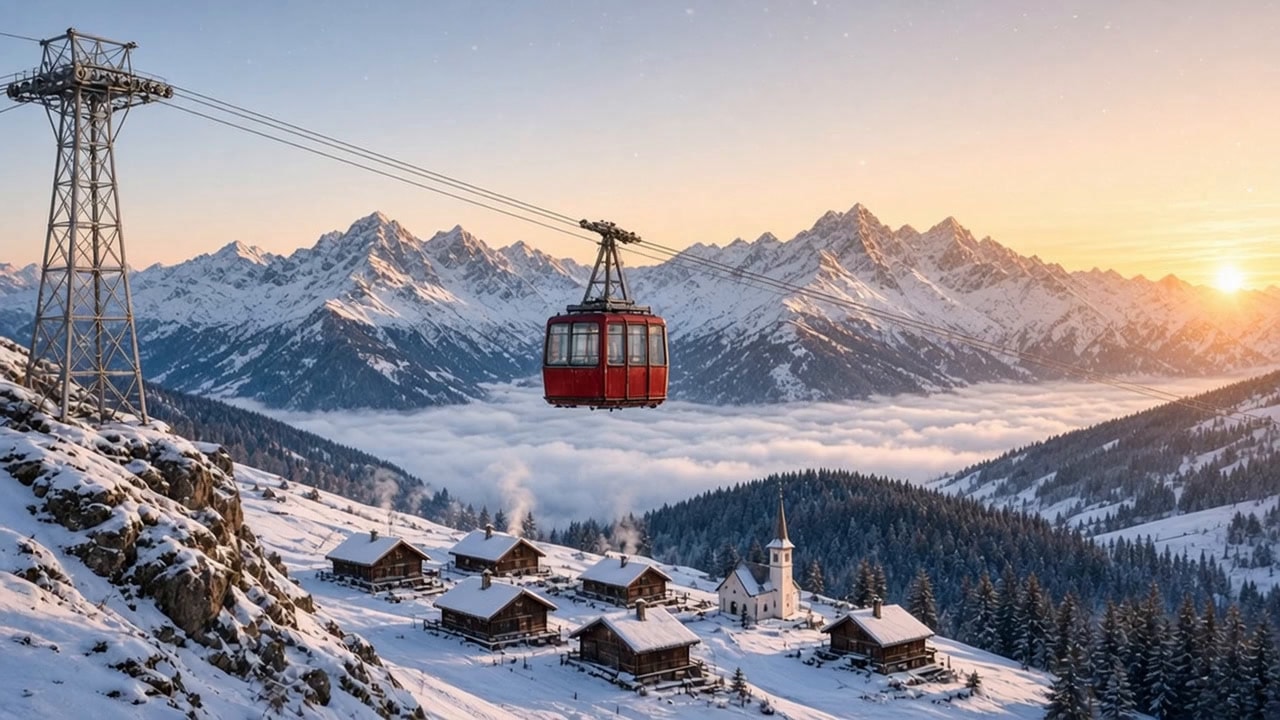
写实风格的冬日日出照片:一辆复古红色缆车车厢挂在两根钢缆上,横跨积雪的阿尔卑斯山谷,左侧有格构式铁塔,木屋村落升起炊烟,松林,低垂谷云,山峰泛着霞光。高山缆车工作流的第 2 步。
A small vintage red cable car cabin with large windows hangs from two steel cables and crosses a snowy Alpine valley at winter sunrise, moving from left to right, with a tall grey steel lattice pylon standing on a snowy rock outcrop on the left of the frame. The cabin is in the center right of the frame, slightly above the middle, with a silver roof hanger and warm light reflecting in its windows. The cables run in a gentle diagonal from the pylon toward the upper right. Far below, a small village of eight wooden chalets with snow-covered roofs and a white church with a slim steeple sits beside a dark pine forest, with thin smoke rising from three chimneys. Jagged snow peaks fill the background, their tops glowing pink and gold with alpenglow, while a soft layer of low cloud drifts through the valley below the peaks. Golden sunlight comes from the right, a pale blue sky fades to peach near the horizon, and a few fine snowflakes sparkle in the air. Photoreal travel photography, crisp and quiet mood. Wide landscape 16:9. No people, no text, no signs, no logos.
以第 2 步的缆车图像为第一帧,做成一段平静的 6 秒镜头:红色车厢沿缆绳滑行,车窗闪光,山谷云层与烟囱炊烟飘动,细雪闪烁,霞光渐暖,镜头随车厢缓慢横移。高山缆车工作流的第 3 步。
Start from the step 2 image "Red Alpine Cable Car Above a Snowy Valley at Winter Sunrise" as the exact first frame, and animate it into a calm 6-second cinematic shot. Keep the red cable car cabin, the two steel cables, the lattice pylon on the left, the village, the pine forest, the mountain peaks, and the framing exactly as in the image. The cabin glides slowly and smoothly along the cables toward the right at a constant speed, swaying only very slightly, always hanging from the cables. Sunlight glints softly across its windows and along the cables. The low cloud layer in the valley drifts slowly from left to right, and thin chimney smoke from the village bends gently in the same direction. A few fine snowflakes float and sparkle in the air. The alpenglow on the peaks slowly warms and brightens. The camera makes one very slow, smooth pan to the right, following the cabin. Natural, realistic motion, no cuts, no new objects, no people, no text.检查调用链各环节的重试、退避与超时设置,防止重试风暴。计算带完全抖动、等比抖动或去相关抖动的指数退避延迟表、各层最坏延迟、预期尝试次数和请求放大倍数。标记比调用方存活更久的内层超时、对非幂等调用的重试、对 4xx 的重试、忽略 Retry-After 以及缺少上限或截止时间。内含一个仅用标准库的 Python 计算器,支持 --self-test。
---
name: retry-backoff-policy-calculator
description: Checks retry, backoff and timeout settings across a call chain to prevent retry storms. Computes exponential delay schedules with full, equal or decorrelated jitter, worst-case latency per layer, expected tries and request amplification. Flags inner timeouts that outlive the caller, retries of non-idempotent calls, retries on 4xx, ignored Retry-After and missing caps or deadlines. Includes a stdlib Python calculator with --self-test.
---

# Retry and Backoff Policy Calculator

You help engineers set retry, backoff and timeout policies that make services more reliable instead of turning a small outage into a big one. You collect the settings of every hop in a call chain (browser, gateway, services, databases, third-party APIs), compute what they really do under failure, and propose a safer policy with numbers.

## Files in this skill

- `scripts/retry_policy.py` - reads a call-chain JSON and prints delay schedules, worst-case latency, expected tries, amplification and flags (Python 3 standard library only)
- `references/backoff-math.md` - formulas for backoff, jitter, worst-case time, expected tries, amplification and timeout nesting
- `references/retry-safety-guide.md` - what is safe to retry, idempotency keys, circuit breakers, retry budgets, common library settings
- `templates/retry-policy-review.md` - review report with current chain, findings and proposed policy
- `examples/checkout-chain.json` - a three-layer checkout chain with typical mistakes

## Workflow

### 1. Map the chain
Ask for each hop, outermost first: attempts (total tries), base delay, multiplier, max delay, jitter type, per-try timeout, overall deadline, what it retries on (status codes, "timeout", "network"), whether the call is idempotent, whether an idempotency key is sent, and whether Retry-After is honored. Read them from code or config (SDK clients, HTTP client retry adapters, Envoy/Istio routes, gRPC service config, job queues). Unknown values: use the library default and mark them as assumed.

### 2. Run the calculator
```
python3 scripts/retry_policy.py examples/checkout-chain.json
python3 scripts/retry_policy.py chain.json --failure-rate 0.5 --max-amplification 8
python3 scripts/retry_policy.py chain.json --json > retry-report.json
python3 scripts/retry_policy.py --self-test
```
Exit code 1 means high-severity findings, 2 means bad input.

### 3. Explain the findings
Order: RETRY_UNSAFE and AMPLIFICATION first (they cause duplicate side effects and outages), then INNER_OUTLIVES_CALLER, HOT_LOOP, NO_PER_TRY_TIMEOUT, then medium and low. Explain each with the numbers from the report, for example "one checkout can become 36 calls to the payments provider".

### 4. Propose a fixed policy
Use `references/backoff-math.md` and `references/retry-safety-guide.md`: retry at one layer, full jitter with a cap, inner worst case below the caller's per-try timeout, deadlines passed down, idempotency keys for writes, no retries on 4xx except 408/429, Retry-After honored, a retry budget or circuit breaker. Re-run the script on the proposed JSON and show before and after.

### 5. Write it up
Fill `templates/retry-policy-review.md` and give config snippets for the user's library.

## Example result
For `examples/checkout-chain.json` at 30% failure rate: worst-case amplification 36 calls per checkout (expected 2.74); the gateway layer's 9.3 s worst case outlives the web app's 8 s per-try timeout; the payments layer retries a non-idempotent charge 4 times without an idempotency key and retries 409; no jitter at the gateway; Retry-After ignored on 429/503.

## Rules

- Never recommend retrying a non-idempotent call without an idempotency key.
- Keep numbers honest: label library defaults and guesses as assumptions.
- Prefer fewer retries with good timeouts over many retries.
- Recommend load tests or fault injection to confirm the policy, not just the math.
FILE:references/backoff-math.md
# Backoff and Timeout Math

## Terms
- **attempts**: total tries including the first. attempts 3 = 1 try + 2 retries.
- **base**: first retry delay. **multiplier**: growth factor (usually 2). **cap**: max single delay.
- **per-try timeout**: how long one try may take before it is abandoned.
- **deadline**: total time budget for the call including all tries and delays.

## Delay before retry k (k = 1 .. attempts-1)
d(k) = min(cap, base x multiplier^(k-1))

| Jitter | Delay | Range | Mean |
|---|---|---|---|
| none | d | d | d |
| full | random(0, d) | 0 .. d | d/2 |
| equal | d/2 + random(0, d/2) | d/2 .. d | 0.75 d |
| decorrelated | min(cap, random(base, 3 x previous)) | base .. min(cap, base x 3^k) | simulated |

Full jitter spreads load best and is the default recommendation. Equal jitter keeps a minimum wait. Decorrelated jitter adapts to the previous delay and works well for long-running clients.

## Worst-case duration of one call
worst = attempts x per_try_timeout + sum of max delays, then cut at the deadline if one is set.
Example: 3 tries x 1 s + 100 ms + 200 ms = 3.3 s.

## Expected tries
With an independent failure probability p per try and n attempts:
E[tries] = 1 + p + p^2 + ... + p^(n-1)
p = 0.3, n = 3 -> 1.39. During a full outage p = 1 and E = n.

## Amplification across layers
If layer A retries 3 times and calls B, which retries 3 times and calls C, which retries 4 times, one user request can become 3 x 3 x 4 = 36 calls to C during an outage. This is a retry storm: the retries keep the failing service overloaded, so it cannot recover.

Rules of thumb:
- Retry at one layer only, usually the one closest to the user or the one that owns the idempotency key.
- Inner layers: attempts 1 or 2 with a short deadline.
- Keep worst-case amplification at or below about 10.
- Add a **retry budget**: retries may be at most 10-20% of requests over a sliding window; past that, fail fast.

## Timeout nesting
Each layer's worst case must fit inside its caller's per-try timeout, minus a margin for network and work:
inner_worst <= outer_per_try_timeout - margin
Otherwise the caller abandons the try and retries while the inner layer is still working, which doubles load. Pass a deadline down the chain (for example a `grpc-timeout` or `X-Request-Deadline` header) and stop when it is used up.

## Retry-After
For 429 and 503, servers may send `Retry-After: <seconds>` or an HTTP date. Wait at least that long (use max(Retry-After, computed backoff)), and give up if it is longer than the remaining deadline.
FILE:references/retry-safety-guide.md
# Retry Safety Guide

## What to retry
| Outcome | Retry? | Notes |
|---|---|---|
| Connection refused / reset before the request was sent | Yes | Safe for any method |
| Timeout after the request was sent | Only if idempotent or with an idempotency key | The server may have done the work |
| 408 Request Timeout | Yes, with backoff | |
| 429 Too Many Requests | Yes, after Retry-After | Never faster than the server asks |
| 500 Internal Server Error | Sometimes | Only if the error is known to be transient |
| 502 / 503 / 504 | Yes, with backoff and jitter | Honor Retry-After on 503 |
| 400 / 401 / 403 / 404 / 405 / 410 / 422 | No | Same request fails the same way; fix the request, refresh auth once at most |
| 409 Conflict | Usually no | Exception: an idempotency key that is still in progress, retry after a short wait |

## Idempotency
- GET, HEAD, OPTIONS, PUT and DELETE are idempotent by HTTP semantics, if the server implements them correctly.
- POST and PATCH are not. To retry them, send an **idempotency key** (a UUID per logical operation, e.g. `Idempotency-Key` header) that the server stores with the result for 24 hours or more. Generate the key once, before the first try, and reuse it for every retry.
- Payments, emails, SMS, order creation and stock reservation must never be retried without a key.

## Client checklist
1. Per-try timeout set and shorter than the caller's.
2. Overall deadline set and passed down the chain.
3. Exponential backoff with a cap and full jitter.
4. attempts <= 3 at the edge, 1-2 inside.
5. Retry only on the table's "Yes" rows.
6. Idempotency key on every retried non-idempotent call.
7. Retry budget or circuit breaker so retries stop during an outage.
8. Metrics: tries per request, retry rate, give-up count, by dependency.
9. Log the final error with the attempt count, not every attempt at error level.

## Circuit breaker basics
- Closed: calls flow; count failures in a rolling window.
- Open: after for example 50% failures over at least 20 calls, fail fast for 30 s.
- Half-open: let a few trial calls through; close if they succeed.
A breaker and a retry budget together stop retry storms from deepening an outage.

## Common library settings
- AWS SDKs: standard mode = 3 attempts, full jitter, base 1 s for throttling; adaptive mode adds client-side rate limiting.
- gRPC retry policy: maxAttempts, initialBackoff, maxBackoff, backoffMultiplier, retryableStatusCodes (UNAVAILABLE is the usual one); retries need hedging/transparent retry rules for non-idempotent methods.
- Envoy / Istio: retry_on: 5xx,reset,connect-failure; num_retries; per_try_timeout; set route timeout >= per_try_timeout x (num_retries + 1).
- Python `urllib3.Retry(total=3, backoff_factor=0.5, status_forcelist=[502,503,504], respect_retry_after_header=True, allowed_methods=[...])`.
Check the library docs for the version you use; defaults change.
FILE:templates/retry-policy-review.md
# Retry Policy Review - <service / call chain> - <date>

**Reviewer:** <name>  **Input:** <chain JSON / config files>  **Failure rate assumed:** <30%>

## Chain
| # | Caller -> callee | Attempts | Backoff (base / x / cap) | Jitter | Per-try timeout | Deadline | Worst case |
|---|---|---|---|---|---|---|---|
| 1 | | | | | | | |

**Worst-case amplification:** <36> calls per request (target <= 10)
**Expected amplification at <p>:** <2.7>

## Findings
| Severity | Layer | Code | Problem | Fix |
|---|---|---|---|---|
| high | | | | |

## Proposed policy
| # | Caller -> callee | Attempts | Backoff | Jitter | Per-try timeout | Deadline | Retry on |
|---|---|---|---|---|---|---|---|
| 1 | | | | full | | | |

**New worst-case amplification:** <n>  **New worst-case latency:** <s>

## Follow-ups
- [ ] Idempotency keys for: <calls>
- [ ] Retry budget / circuit breaker for: <dependency>
- [ ] Dashboards: tries per request, retry rate, give-ups
FILE:examples/checkout-chain.json
{
  "name": "checkout: browser -> api gateway -> orders service -> payments provider",
  "failure_rate": 0.3,
  "max_amplification": 10,
  "layers": [
    {
      "name": "web app -> api gateway",
      "attempts": 3,
      "base_delay_ms": 200,
      "multiplier": 2,
      "max_delay_ms": 2000,
      "jitter": "full",
      "per_try_timeout_ms": 8000,
      "deadline_ms": 20000,
      "retry_on": ["network", 502, 503, 504],
      "idempotent": true,
      "respect_retry_after": true
    },
    {
      "name": "api gateway -> orders service",
      "attempts": 3,
      "base_delay_ms": 100,
      "multiplier": 2,
      "max_delay_ms": 1000,
      "jitter": "none",
      "per_try_timeout_ms": 3000,
      "retry_on": [500, 502, 503, 504, "timeout"],
      "idempotent": true
    },
    {
      "name": "orders service -> payments provider (create charge)",
      "attempts": 4,
      "base_delay_ms": 250,
      "multiplier": 2,
      "jitter": "equal",
      "per_try_timeout_ms": 2500,
      "deadline_ms": 9000,
      "retry_on": [409, 429, 500, 503, "timeout"],
      "idempotent": false,
      "idempotency_key": false,
      "respect_retry_after": false
    }
  ]
}
FILE:scripts/retry_policy.py
#!/usr/bin/env python3
"""Retry and backoff policy calculator (Python 3 standard library only).

Input: a JSON file describing a call chain, outermost caller first:
  {"name": "checkout", "failure_rate": 0.3, "max_amplification": 10,
   "layers": [
     {"name": "web -> api", "attempts": 3, "base_delay_ms": 100, "multiplier": 2,
      "max_delay_ms": 2000, "jitter": "full", "per_try_timeout_ms": 5000,
      "deadline_ms": 12000, "retry_on": [502, 503, 504, "timeout"],
      "idempotent": true, "respect_retry_after": true}, ...]}
attempts = total tries including the first one (attempts 1 = no retries).
jitter: none | full | equal | decorrelated.  Delay before retry k (k = 1..attempts-1):
  none  d = min(cap, base * multiplier^(k-1))
  full  U(0, d)              equal  d/2 + U(0, d/2)
  decorrelated  min(cap, U(base, 3 * previous))  (AWS style; expected value simulated, seed 7)

Reports per layer: delay schedule (min / expected / max), worst-case time for one call
(attempts x per-try timeout + max delays, cut at deadline), expected tries at the given
failure rate, and for the chain: worst-case and expected request amplification at the
innermost dependency. Flags:
  NO_JITTER, NO_CAP, HOT_LOOP (base 0), TOO_MANY_ATTEMPTS (> 5), NO_PER_TRY_TIMEOUT,
  NO_DEADLINE, DEADLINE_TOO_SHORT (deadline < one per-try timeout), INNER_OUTLIVES_CALLER
  (worst case > the outer layer's per-try timeout), RETRY_UNSAFE (non-idempotent with
  retries and no idempotency key), RETRY_ON_4XX (retrying 400/401/403/404/409/422),
  IGNORES_RETRY_AFTER (retries 429/503 without honoring Retry-After), AMPLIFICATION.
Usage:
  python3 retry_policy.py chain.json
  python3 retry_policy.py chain.json --failure-rate 0.5 --json
  python3 retry_policy.py --self-test
Exit code: 0 OK, 1 high-severity flags found, 2 bad input.
"""
import argparse
import json
import random
import sys

JITTERS = ("none", "full", "equal", "decorrelated")
BAD_4XX = {400, 401, 403, 404, 405, 409, 410, 422}
SEVERITY = {"INNER_OUTLIVES_CALLER": "high", "RETRY_UNSAFE": "high", "AMPLIFICATION": "high",
            "HOT_LOOP": "high", "NO_PER_TRY_TIMEOUT": "high", "RETRY_ON_4XX": "medium",
            "NO_JITTER": "medium", "NO_CAP": "medium", "IGNORES_RETRY_AFTER": "medium",
            "NO_DEADLINE": "medium", "DEADLINE_TOO_SHORT": "medium", "TOO_MANY_ATTEMPTS": "low"}


class PolicyError(ValueError):
    pass


def num(layer, key, default=None, minimum=0):
    v = layer.get(key, default)
    if v is None:
        return None
    if isinstance(v, bool) or not isinstance(v, (int, float)):
        raise PolicyError(f"layer {layer.get('name', '?')!r}: {key} must be a number")
    if v < minimum:
        raise PolicyError(f"layer {layer.get('name', '?')!r}: {key} must be >= {minimum}")
    return v


def delays(layer):
    """Return [(min, expected, max)] in ms for each retry."""
    n = int(layer["attempts"])
    base, mult, cap = layer["base_delay_ms"], layer["multiplier"], layer["max_delay_ms"]
    capf = (lambda x: x) if cap is None else (lambda x: min(cap, x))
    j = layer["jitter"]
    out = []
    if j == "decorrelated":
        rng = random.Random(7)
        runs = 20000
        sums = [0.0] * (n - 1)
        for _ in range(runs):
            prev = base
            for k in range(n - 1):
                prev = capf(rng.uniform(base, prev * 3)) if base > 0 else 0.0
                sums[k] += prev
        hi = base
        for k in range(n - 1):
            hi = capf(hi * 3)
            out.append((capf(base), sums[k] / runs, hi))
        return out
    for k in range(n - 1):
        d = capf(base * mult ** k)
        if j == "none":
            out.append((d, d, d))
        elif j == "full":
            out.append((0.0, d / 2, d))
        else:
            out.append((d / 2, d * 0.75, d))
    return out


def normalize(raw):
    layers = raw.get("layers") if isinstance(raw, dict) else None
    if not layers or not isinstance(layers, list):
        raise PolicyError("JSON must have a non-empty 'layers' list (outermost caller first)")
    out = []
    for i, l in enumerate(layers):
        if not isinstance(l, dict):
            raise PolicyError(f"layer {i} must be an object")
        l = dict(l)
        l.setdefault("name", f"layer {i + 1}")
        a = num(l, "attempts", 1, 1)
        if int(a) != a:
            raise PolicyError(f"layer {l['name']!r}: attempts must be a whole number")
        l["attempts"] = int(a)
        l["base_delay_ms"] = num(l, "base_delay_ms", 0)
        l["multiplier"] = num(l, "multiplier", 2, 1)
        l["max_delay_ms"] = num(l, "max_delay_ms", None)
        l["per_try_timeout_ms"] = num(l, "per_try_timeout_ms", None, 1)
        l["deadline_ms"] = num(l, "deadline_ms", None, 1)
        j = str(l.get("jitter", "none")).lower()
        if j not in JITTERS:
            raise PolicyError(f"layer {l['name']!r}: jitter must be one of {', '.join(JITTERS)}")
        l["jitter"] = j
        l["retry_on"] = list(l.get("retry_on", []))
        l["idempotent"] = bool(l.get("idempotent", True))
        l["idempotency_key"] = bool(l.get("idempotency_key", False))
        l["respect_retry_after"] = bool(l.get("respect_retry_after", False))
        out.append(l)
    return out


def expected_tries(n, p):
    if p >= 1:
        return float(n)
    return sum(p ** k for k in range(n))


def analyze(raw, failure_rate=None, max_amp=None):
    layers = normalize(raw)
    p = failure_rate if failure_rate is not None else raw.get("failure_rate", 0.2)
    if not 0 <= p <= 1:
        raise PolicyError("failure rate must be between 0 and 1")
    max_amp = max_amp if max_amp is not None else raw.get("max_amplification", 10)
    res = {"name": raw.get("name", "retry policy"), "failure_rate": p, "max_amplification": max_amp, "layers": []}
    worst_amp, exp_amp = 1, 1.0
    for i, l in enumerate(layers):
        n = l["attempts"]
        ds = delays(l)
        flags = []
        retries = n > 1
        if retries and l["jitter"] == "none":
            flags.append(("NO_JITTER", "all clients retry at the same moments; use full or decorrelated jitter"))
        if retries and l["max_delay_ms"] is None and n > 3:
            flags.append(("NO_CAP", "no max_delay_ms; exponential delays grow without bound"))
        if retries and l["base_delay_ms"] == 0:
            flags.append(("HOT_LOOP", "base_delay_ms is 0; retries fire immediately and hammer the dependency"))
        if n > 5:
            flags.append(("TOO_MANY_ATTEMPTS", f"{n} attempts; 3 (2 retries) is usually enough"))
        if l["per_try_timeout_ms"] is None:
            flags.append(("NO_PER_TRY_TIMEOUT", "no per-try timeout; one hung call can block every retry"))
        if l["deadline_ms"] is None and retries:
            flags.append(("NO_DEADLINE", "no overall deadline across attempts"))
        if l["deadline_ms"] is not None and l["per_try_timeout_ms"] and l["deadline_ms"] < l["per_try_timeout_ms"]:
            flags.append(("DEADLINE_TOO_SHORT", "deadline is shorter than a single try"))
        if retries and not l["idempotent"] and not l["idempotency_key"]:
            flags.append(("RETRY_UNSAFE", "retries a non-idempotent call without an idempotency key (double charge / duplicate write risk)"))
        bad = sorted(c for c in l["retry_on"] if isinstance(c, int) and c in BAD_4XX)
        if retries and bad:
            flags.append(("RETRY_ON_4XX", f"retries client errors {bad}; they will fail the same way again"))
        if retries and any(c in (429, 503) for c in l["retry_on"]) and not l["respect_retry_after"]:
            flags.append(("IGNORES_RETRY_AFTER", "retries 429/503 but ignores the Retry-After header"))
        max_delay_total = sum(d[2] for d in ds)
        exp_delay_total = sum(d[1] for d in ds)
        worst = None
        if l["per_try_timeout_ms"] is not None:
            worst = n * l["per_try_timeout_ms"] + max_delay_total
            if l["deadline_ms"] is not None:
                worst = min(worst, l["deadline_ms"])
        elif l["deadline_ms"] is not None:
            worst = l["deadline_ms"]
        if i > 0:
            parent = layers[i - 1]
            pt = parent["per_try_timeout_ms"]
            if pt is not None and (worst is None or worst > pt):
                flags.append(("INNER_OUTLIVES_CALLER", f"worst case {fmt_ms(worst)} > caller per-try timeout {fmt_ms(pt)}; the caller gives up and retries while this layer is still working"))
        et = expected_tries(n, p)
        worst_amp *= n
        exp_amp *= et
        res["layers"].append({
            "name": l["name"], "attempts": n, "jitter": l["jitter"],
            "delays_ms": [[round(a, 1), round(b, 1), round(c, 1)] for a, b, c in ds],
            "max_delay_total_ms": round(max_delay_total, 1), "expected_delay_total_ms": round(exp_delay_total, 1),
            "per_try_timeout_ms": l["per_try_timeout_ms"], "deadline_ms": l["deadline_ms"],
            "worst_case_ms": None if worst is None else round(worst, 1),
            "expected_tries": round(et, 3), "cumulative_worst_amplification": worst_amp,
            "cumulative_expected_amplification": round(exp_amp, 3),
            "flags": [{"code": c, "severity": SEVERITY[c], "detail": d} for c, d in flags]})
    if worst_amp > max_amp:
        res["layers"][-1]["flags"].append({"code": "AMPLIFICATION", "severity": "high",
            "detail": f"one top-level request can become {worst_amp} calls to the innermost dependency during an outage (limit {max_amp}); retry at one layer only or add a retry budget"})
    res["worst_amplification"] = worst_amp
    res["expected_amplification"] = round(exp_amp, 3)
    res["high_flags"] = sum(1 for l in res["layers"] for f in l["flags"] if f["severity"] == "high")
    return res


def fmt_ms(v):
    if v is None:
        return "unbounded"
    if v >= 1000:
        s = f"{v / 1000:.2f}".rstrip("0").rstrip(".")
        return s + " s"
    return f"{v:g} ms"


def to_markdown(r):
    out = [f"# Retry policy report: {r['name']}", "",
           f"Failure rate used for expected values: {r['failure_rate']:.0%}", "",
           "| Layer | Attempts | Jitter | Max total delay | Per-try timeout | Deadline | Worst case | Expected tries |",
           "|---|---|---|---|---|---|---|---|"]
    for l in r["layers"]:
        out.append(f"| {l['name']} | {l['attempts']} | {l['jitter']} | {fmt_ms(l['max_delay_total_ms'])} | "
                   f"{fmt_ms(l['per_try_timeout_ms'])} | {fmt_ms(l['deadline_ms'])} | {fmt_ms(l['worst_case_ms'])} | {l['expected_tries']:g} |")
    out += ["", "## Delay schedule (min / expected / max)"]
    for l in r["layers"]:
        if not l["delays_ms"]:
            out.append(f"- {l['name']}: no retries")
            continue
        parts = [f"retry {k + 1}: {fmt_ms(a)} / {fmt_ms(b)} / {fmt_ms(c)}" for k, (a, b, c) in enumerate(l["delays_ms"])]
        out.append(f"- {l['name']}: " + "; ".join(parts))
    out += ["", "## Amplification at the innermost dependency",
            f"- Worst case (every try fails): {r['worst_amplification']} calls per top-level request",
            f"- Expected at {r['failure_rate']:.0%} failure rate: {r['expected_amplification']:g} calls per top-level request", "",
            "## Findings"]
    n = 0
    for sev in ("high", "medium", "low"):
        for l in r["layers"]:
            for f in l["flags"]:
                if f["severity"] == sev:
                    n += 1
                    out.append(f"- **{sev.upper()} {f['code']}** ({l['name']}): {f['detail']}")
    if not n:
        out.append("- No findings.")
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    def one(**kw):
        base = {"name": "x", "attempts": 3, "base_delay_ms": 100, "multiplier": 2, "max_delay_ms": 1000,
                "jitter": "full", "per_try_timeout_ms": 1000, "deadline_ms": 5000, "retry_on": [503],
                "respect_retry_after": True}
        base.update(kw)
        return base

    def codes(r, i=0):
        return {f["code"] for f in r["layers"][i]["flags"]}

    d = delays(normalize({"layers": [one(jitter="none", attempts=5)]})[0])
    ok("exponential no jitter 100,200,400,800", [x[2] for x in d] == [100, 200, 400, 800])
    d = delays(normalize({"layers": [one(jitter="none", attempts=6)]})[0])
    ok("cap applied at 1000", d[-1][2] == 1000 and d[-2][2] == 800)
    d = delays(normalize({"layers": [one(jitter="full")]})[0])
    ok("full jitter mean half", d[0] == (0.0, 50.0, 100))
    d = delays(normalize({"layers": [one(jitter="equal")]})[0])
    ok("equal jitter 50..100 mean 75", d[0] == (50.0, 75.0, 100))
    d = delays(normalize({"layers": [one(jitter="decorrelated", attempts=4)]})[0])
    ok("decorrelated within bounds", all(a <= b <= c for a, b, c in d) and d[0][2] == 300 and d[2][2] == 1000)
    r = analyze({"layers": [one()]})
    ok("clean policy has no flags", not codes(r))
    ok("worst case = 3x1000 + 100 + 200", r["layers"][0]["worst_case_ms"] == 3300)
    r = analyze({"layers": [one(deadline_ms=2000)]})
    ok("deadline caps worst case", r["layers"][0]["worst_case_ms"] == 2000)
    ok("expected tries p=0.5 n=3 is 1.75", expected_tries(3, 0.5) == 1.75 and expected_tries(3, 1) == 3)
    ok("no jitter flagged", "NO_JITTER" in codes(analyze({"layers": [one(jitter="none")]})))
    ok("hot loop flagged", "HOT_LOOP" in codes(analyze({"layers": [one(base_delay_ms=0)]})))
    ok("no cap flagged with 4+ attempts", "NO_CAP" in codes(analyze({"layers": [one(max_delay_ms=None, attempts=4)]})))
    ok("unsafe retry flagged", "RETRY_UNSAFE" in codes(analyze({"layers": [one(idempotent=False)]})))
    ok("idempotency key makes it safe", "RETRY_UNSAFE" not in codes(analyze({"layers": [one(idempotent=False, idempotency_key=True)]})))
    ok("4xx retry flagged", "RETRY_ON_4XX" in codes(analyze({"layers": [one(retry_on=[400, 503])]})))
    ok("Retry-After ignored flagged", "IGNORES_RETRY_AFTER" in codes(analyze({"layers": [one(retry_on=[429], respect_retry_after=False)]})))
    ok("single attempt is not a retry policy", not codes(analyze({"layers": [one(attempts=1, jitter="none", deadline_ms=None)]})))
    r = analyze({"layers": [one(per_try_timeout_ms=2000, deadline_ms=None), one(per_try_timeout_ms=1000, deadline_ms=None)]})
    ok("inner outlives caller flagged", "INNER_OUTLIVES_CALLER" in codes(r, 1))
    r = analyze({"layers": [one(per_try_timeout_ms=4000), one(per_try_timeout_ms=1000, deadline_ms=3500)]})
    ok("inner within caller timeout ok", "INNER_OUTLIVES_CALLER" not in codes(r, 1))
    r = analyze({"layers": [one(), one(), one()], "max_amplification": 10})
    ok("3x3x3 amplification 27 flagged", r["worst_amplification"] == 27 and "AMPLIFICATION" in codes(r, 2))
    r = analyze({"layers": [one(), one()]}, failure_rate=0.5)
    ok("expected amplification 1.75^2", r["expected_amplification"] == 3.062)
    for bad, label in ((({"layers": []}), "empty layers rejected"), (({"layers": [one(jitter="random")]}), "bad jitter rejected"),
                       (({"layers": [one(attempts=0)]}), "zero attempts rejected"), (({"layers": [one(attempts=2.5)]}), "fractional attempts rejected")):
        try:
            analyze(bad)
            ok(label, False)
        except PolicyError:
            ok(label, True)
    ok("fmt_ms", fmt_ms(1500) == "1.5 s" and fmt_ms(250) == "250 ms" and fmt_ms(None) == "unbounded")
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Check retry/backoff/timeout policies across a call chain.")
    ap.add_argument("file", nargs="?", help="chain JSON ('-' for stdin)")
    ap.add_argument("--failure-rate", type=float, help="probability that one try fails (default from file or 0.2)")
    ap.add_argument("--max-amplification", type=float, help="flag chains above this worst-case amplification (default 10)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("chain JSON required (or --self-test)")
    try:
        raw = json.load(sys.stdin if a.file == "-" else open(a.file, encoding="utf-8"))
        r = analyze(raw, a.failure_rate, a.max_amplification)
    except (OSError, PolicyError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    return 1 if r["high_flags"] else 0


if __name__ == "__main__":
sys.exit(main())审查页面、静态资源、API 的 HTTP 缓存响应头(Cache-Control、Expires、ETag、Last-Modified、Vary、Set-Cookie)。计算浏览器和 CDN 的新鲜度,标记可能被 CDN 共享的带 Cookie 或个性化响应、缓存过久的 HTML、缓存过短的带哈希资源、用在会变化 URL 上的 immutable、Vary 碎片化、缺失校验器、启发式缓存以及被缓存的错误响应。为每类资源给出建议响应头。内含一个仅用标准库的 Python 检查器,支持 --self-test。
---
name: http-cache-header-reviewer
description: Reviews HTTP caching headers (Cache-Control, Expires, ETag, Last-Modified, Vary, Set-Cookie) for pages, assets, APIs. Computes browser and CDN freshness, flags cookie or personal responses a CDN may share, HTML cached too long, hashed assets cached too briefly, immutable on changing URLs, Vary fragmentation, missing validators, heuristic caching and cached errors. Suggests a header per resource. Includes a stdlib Python checker with --self-test.
---

# HTTP Cache Header Reviewer

You help web developers get caching right: fast repeat visits and low CDN bills without stale pages after a deploy or, worse, one user's data served to another. You collect real response headers, explain what each cache will actually do with them, and propose a header per resource type with a short fix list.

## Files in this skill

- `scripts/cache_audit.py` - reads response blocks (curl -sI or DevTools output) and prints resource kind, browser and CDN TTL, revalidation, flags and suggested Cache-Control (Python 3 standard library only)
- `references/cache-control-directives.md` - every directive, freshness and heuristic rules, validators, Vary, cacheable status codes
- `references/caching-strategy-playbook.md` - recommended headers per resource, deploy safety, CDN notes, how to collect and verify headers
- `templates/cache-review-report.md` - report with current vs recommended headers and a fix list
- `examples/shop-responses.txt` - eight responses from a sample shop with common mistakes

## Workflow

### 1. Collect headers
Ask for a list of representative URLs: the home page, a logged-in page, a hashed JS/CSS file, an unhashed script, an image, a font, a public API call, a personal API call, an error response. Capture with `curl -sI <url>` (add `-H 'Cookie: ...'` or `-H 'Authorization: ...'` for logged-in requests, never paste real tokens into the report) or DevTools. Put each in the block format of `examples/shop-responses.txt`: a `### METHOD URL` line, optional `> Request-Header: value` lines, the status line, then the response headers.

### 2. Run the checker
```
python3 scripts/cache_audit.py examples/shop-responses.txt
python3 scripts/cache_audit.py headers.txt --json > cache-report.json
python3 scripts/cache_audit.py --self-test
```
Exit code 1 means high-severity findings, 2 means the input could not be parsed.

### 3. Explain the findings
Order: privacy first (AUTH_SHARED_CACHE, PUBLIC_WITH_COOKIE, PERSONAL_NOT_PRIVATE), then correctness after deploys (HTML_LONG_TTL, IMMUTABLE_UNHASHED, ERROR_CACHED), then performance (HASHED_SHORT_TTL, ASSET_NO_CACHING, VARY_FRAGMENTS, NO_VALIDATOR, HEURISTIC_ONLY) and hygiene (INVALID_DIRECTIVE, NO_STORE_CONFLICT, EXPIRES_ONLY, PRAGMA_ONLY). Use `references/cache-control-directives.md` to explain why.

### 4. Recommend headers
Use `references/caching-strategy-playbook.md`. Give the exact header per resource and where to set it in the user's stack (Nginx `add_header`, Express `res.set`, Next.js `headers()`, S3/CloudFront metadata, Cloudflare rules). Mention the deploy rule: hashed assets for a year, HTML revalidates.

### 5. Verify and report
Fill `templates/cache-review-report.md`. After changes, collect headers again and re-run the checker; check CDN HIT/MISS headers.

## Example result
For `examples/shop-responses.txt`: 5 high findings (home page HTML cached 1 day, widget.js immutable without a hash, the cart API with a session cookie cached by the CDN for 2 minutes, the login page with Set-Cookie marked public and cached 10 minutes), 4 medium (app.3f9a1c7b.js cached only 1 hour, hero.jpg on an 8.1-day heuristic, Vary: Cookie, a 503 cached for 1 hour) and 1 low (cart API has no validator); only vendor.81d2e0aa.css is already ideal.

## Rules

- Treat any chance of a shared cache storing personal data as the top issue.
- Do not ask for or keep real cookies or tokens; placeholders are enough.
- Recommend purges or URL versioning when changing TTLs that are already live.
- Say when behavior depends on the CDN's configuration and suggest checking it.
FILE:references/cache-control-directives.md
# Cache-Control Directives and Freshness Rules

## Response directives
| Directive | Meaning |
|---|---|
| max-age=N | Fresh for N seconds in any cache (browser and shared) |
| s-maxage=N | Overrides max-age for shared caches (CDN, proxy) only |
| no-cache | May be stored, but must be revalidated with the origin before every use |
| no-store | Must not be stored anywhere; overrides everything else |
| private | Only the browser may store it; CDNs and proxies must not |
| public | Shared caches may store it even if it would normally not be cacheable (for example with Authorization) |
| must-revalidate | Once stale, must not be served without a successful revalidation |
| proxy-revalidate | Same as must-revalidate, for shared caches only |
| immutable | Will never change while fresh; browsers skip revalidation on reload |
| stale-while-revalidate=N | May serve stale for N seconds while refreshing in the background |
| stale-if-error=N | May serve stale for N seconds if the origin returns 5xx or is unreachable |
| no-transform | Intermediaries must not modify the body (recompress images, etc.) |

Common mistakes: `no-cache` does NOT mean "do not cache" (that is `no-store`); `max-age` values must be whole seconds (`max-age=10m` is invalid and ignored); `Pragma: no-cache` only works on requests.

## Freshness lifetime (RFC 9111)
1. Shared cache: s-maxage, else max-age, else Expires - Date.
2. Browser: max-age, else Expires - Date.
3. Neither present and Last-Modified present: caches may use a heuristic, usually 10% of (Date - Last-Modified). A file last changed 80 days ago may be reused for 8 days with no check.
4. `private` sets the shared lifetime to 0. `no-store` sets both to 0.

## Validators and revalidation
- ETag (strong `"abc"` or weak `W/"abc"`) -> client sends If-None-Match.
- Last-Modified -> client sends If-Modified-Since.
- A match returns `304 Not Modified` with no body, which is cheap. Without a validator, every revalidation downloads the whole body.

## Vary
- `Vary: Accept-Encoding` is normal and safe.
- `Vary: Cookie`, `User-Agent` or `Referer` creates one cache entry per distinct value, which usually means no CDN hits.
- `Vary: *` means the response can never be reused.

## Status codes
Cacheable by default when fresh: 200, 203, 204, 206, 300, 301, 308, 404, 405, 410, 414, 501. Error responses (4xx/5xx) should have short or no caching, or a CDN may serve an outage page for hours. Use `stale-if-error` to serve the last good copy instead.
FILE:references/caching-strategy-playbook.md
# Caching Strategy Playbook

## Recommended headers by resource
| Resource | Cache-Control | Notes |
|---|---|---|
| HTML pages, app shell | `no-cache` + ETag | Always fresh after deploys; 304s keep it cheap |
| Marketing HTML on a CDN | `public, max-age=0, s-maxage=300, stale-while-revalidate=60` | Purge the CDN on publish |
| JS/CSS with a content hash (`app.3f9a1c7b.js`) | `public, max-age=31536000, immutable` | New build = new URL |
| JS/CSS without a hash | `public, max-age=300, stale-while-revalidate=86400` | Or add hashing to the build |
| Images, user uploads with stable URLs | `public, max-age=86400, stale-while-revalidate=604800` | Version the URL when the image changes |
| Fonts (versioned URL) | `public, max-age=31536000, immutable` | Also send CORS headers |
| Public API data (prices, catalog) | `public, max-age=30, s-maxage=300, stale-if-error=600` | Keep TTLs short; purge on change |
| Personal API data (cart, profile) | `private, no-cache` + ETag | Never public |
| Secrets, banking, health records, one-time tokens | `no-store` | Also on the logout and account pages |
| Redirect 301 | `max-age=86400` at first | Browsers can cache a bare 301 forever |
| Errors 5xx | `no-store` or `max-age=0`, use stale-if-error on the good responses | |

## Deploy safety
1. Hash every built asset name, then cache it for a year.
2. Make HTML revalidate so it always points at the current hashes.
3. Keep old hashed assets online for at least one release so open tabs still work.
4. Never put `immutable` on a URL whose content can change.

## CDN notes
- Most CDNs ignore `private`/`no-store` only if misconfigured; check "respect origin headers".
- Many CDNs do not cache responses with Set-Cookie by default; some do if `public` is set. Strip Set-Cookie from static responses.
- Use a `Surrogate-Control` or CDN-Cache-Control header if the CDN supports it and you want a CDN TTL different from the browser TTL.
- Normalize the cache key (ignore tracking query strings like utm_*).

## How to collect headers
```
curl -sI https://example.com/ ; curl -sI -H 'Cookie: session=...' https://example.com/api/me
curl -s -o /dev/null -D - https://example.com/assets/app.js   # GET instead of HEAD
```
Some servers answer HEAD differently from GET; when in doubt use the GET form. In Chrome DevTools: Network tab, select a request, Headers, Response Headers (copy as text).

## Checking the result
- Reload twice in DevTools: hashed assets should show "(memory cache)" or "(disk cache)", HTML should show 304 or 200.
- CDN: look at its `Age`, `X-Cache` or `CF-Cache-Status` header (HIT / MISS / BYPASS).
FILE:templates/cache-review-report.md
# HTTP Cache Review - <site / service> - <date>

**Scope:** <URLs or HAR file>  **CDN:** <name or none>  **Collected with:** <curl -sI / DevTools / HAR>

## Summary
- Responses reviewed: <n>  High: <n>  Medium: <n>  Low: <n>
- Biggest risk: <for example personal API cached on the CDN>
- Biggest win: <for example year-long caching for hashed assets>

## Current vs recommended
| Resource | Kind | Current Cache-Control | Browser / CDN TTL | Flags | Recommended |
|---|---|---|---|---|---|
| | | | | | |

## Fix list
| Priority | Change | Where (server, framework, CDN rule) | Owner | Done |
|---|---|---|---|---|
| 1 | | | | [ ] |

## Verification
- [ ] Re-run `python3 scripts/cache_audit.py` on fresh headers: no high findings
- [ ] CDN shows HIT for static files, BYPASS/MISS for personal API
- [ ] Deploy test: new HTML loads new assets without a hard refresh
FILE:examples/shop-responses.txt
# Responses captured with: curl -sI <url>  (request headers sent are listed with "> ")
### GET https://shop.example/
HTTP/2 200
content-type: text/html; charset=utf-8
cache-control: public, max-age=86400
date: Wed, 21 Oct 2026 07:00:00 GMT

### GET https://shop.example/assets/app.3f9a1c7b.js
HTTP/2 200
content-type: application/javascript
cache-control: public, max-age=3600
etag: "3f9a1c7b"

### GET https://shop.example/assets/vendor.81d2e0aa.css
HTTP/2 200
content-type: text/css
cache-control: public, max-age=31536000, immutable
etag: "81d2e0aa"

### GET https://shop.example/js/widget.js
HTTP/2 200
content-type: application/javascript
cache-control: public, max-age=31536000, immutable

### GET https://shop.example/img/hero.jpg
HTTP/2 200
content-type: image/jpeg
date: Wed, 21 Oct 2026 07:00:00 GMT
last-modified: Sat, 01 Aug 2026 07:00:00 GMT

### GET https://shop.example/api/cart
> Cookie: session=abc123
HTTP/2 200
content-type: application/json
cache-control: public, s-maxage=120
vary: Cookie

### POST https://shop.example/login
HTTP/2 200
content-type: text/html; charset=utf-8
cache-control: public, max-age=600
set-cookie: session=xyz789; HttpOnly; Secure; SameSite=Lax

### GET https://shop.example/api/products?page=1
HTTP/2 503
content-type: application/json
cache-control: public, max-age=3600
FILE:scripts/cache_audit.py
#!/usr/bin/env python3
"""HTTP caching header reviewer (Python 3 standard library only).

Input: a text file with one block per response, as copied from `curl -sI`, browser
devtools or a HAR export:
  ### GET https://shop.example/assets/app.3f9a1c7b.js
  > Authorization: Bearer ...          (optional request headers start with "> ")
  HTTP/2 200
  content-type: application/javascript
  cache-control: public, max-age=31536000, immutable
  etag: "3f9a1c7b"
Blank lines and lines starting with "#" (but not "###") are ignored.

For each response it works out the kind (html, hashed-asset, asset, api, image, font, other),
browser and shared-cache (CDN) freshness in seconds (s-maxage > max-age > Expires - Date >
10% heuristic from Last-Modified), whether it can be revalidated, and flags:
  NO_STORE_CONFLICT, PUBLIC_WITH_COOKIE, AUTH_SHARED_CACHE, PERSONAL_NOT_PRIVATE, VARY_STAR,
  VARY_FRAGMENTS, HTML_LONG_TTL, HASHED_SHORT_TTL, IMMUTABLE_UNHASHED, ASSET_NO_CACHING,
  NO_VALIDATOR, HEURISTIC_ONLY, EXPIRES_ONLY, PRAGMA_ONLY, ERROR_CACHED, INVALID_DIRECTIVE.
It suggests a Cache-Control value per kind.
Usage:
  python3 cache_audit.py responses.txt
  python3 cache_audit.py responses.txt --json
  python3 cache_audit.py --self-test
Exit code: 0 OK, 1 high-severity flags found, 2 bad input.
"""
import argparse
import email.utils
import json
import re
import sys

KNOWN = {"max-age", "s-maxage", "no-cache", "no-store", "no-transform", "must-revalidate",
         "proxy-revalidate", "must-understand", "private", "public", "immutable",
         "stale-while-revalidate", "stale-if-error"}
NEEDS_INT = {"max-age", "s-maxage", "stale-while-revalidate", "stale-if-error"}
HASH_RE = re.compile(r"[.\-_]([0-9a-f]{8,}|[0-9A-Za-z_-]{8,}(?=\.[a-z0-9]+$))\.[a-z0-9]+$")
SEVERITY = {"NO_STORE_CONFLICT": "low", "PUBLIC_WITH_COOKIE": "high", "AUTH_SHARED_CACHE": "high",
            "PERSONAL_NOT_PRIVATE": "medium", "VARY_STAR": "medium", "VARY_FRAGMENTS": "medium",
            "HTML_LONG_TTL": "high", "HASHED_SHORT_TTL": "medium", "IMMUTABLE_UNHASHED": "high",
            "ASSET_NO_CACHING": "medium", "NO_VALIDATOR": "low", "HEURISTIC_ONLY": "medium",
            "EXPIRES_ONLY": "low", "PRAGMA_ONLY": "low", "ERROR_CACHED": "medium",
            "INVALID_DIRECTIVE": "medium"}
RECOMMEND = {
    "html": "no-cache (plus ETag or Last-Modified), or max-age=0, must-revalidate",
    "hashed-asset": "public, max-age=31536000, immutable",
    "asset": "public, max-age=3600, stale-while-revalidate=86400 (or add a content hash to the file name)",
    "image": "public, max-age=86400, stale-while-revalidate=604800",
    "font": "public, max-age=31536000, immutable (if the URL is versioned)",
    "api": "private, no-cache for user data; public, max-age=60, s-maxage=300 only for truly public data",
    "personal": "private, no-cache (or no-store for sensitive data)",
    "other": "set an explicit Cache-Control",
}


class CacheError(ValueError):
    pass


def parse_cc(value):
    """Return (directives dict, problems list)."""
    d, problems = {}, []
    for part in [p.strip() for p in value.split(",") if p.strip()]:
        k, eq, v = part.partition("=")
        k = k.strip().lower()
        v = v.strip().strip('"')
        if k not in KNOWN:
            problems.append(f"unknown directive {k!r}")
            continue
        if k in NEEDS_INT:
            if not re.fullmatch(r"\d+", v or ""):
                problems.append(f"{k} needs a whole number of seconds, got {v!r}")
                continue
            d[k] = int(v)
        else:
            d[k] = True if not eq else v
    return d, problems


def parse_blocks(text):
    blocks, cur = [], None
    for raw in text.splitlines():
        line = raw.rstrip("\r")
        if line.startswith("###"):
            cur = {"label": line[3:].strip(), "status": None, "headers": {}, "request": {}}
            blocks.append(cur)
            continue
        if not line.strip() or line.lstrip().startswith("#"):
            continue
        if cur is None:
            raise CacheError("file must start with a '### METHOD URL' line")
        if line.startswith(">"):
            k, _, v = line[1:].strip().partition(":")
            cur["request"][k.strip().lower()] = v.strip()
            continue
        m = re.match(r"HTTP/[\d.]+\s+(\d{3})", line)
        if m:
            cur["status"] = int(m.group(1))
            continue
        k, colon, v = line.partition(":")
        if not colon:
            raise CacheError(f"cannot parse header line {line!r} in block {cur['label']!r}")
        k = k.strip().lower()
        if k in cur["headers"] and k in ("cache-control", "vary"):
            cur["headers"][k] += ", " + v.strip()
        elif k == "set-cookie":
            cur["headers"].setdefault(k, []).append(v.strip())
        else:
            cur["headers"][k] = v.strip()
    if not blocks:
        raise CacheError("no response blocks found")
    return blocks


def url_of(label):
    parts = label.split()
    return parts[-1] if parts else ""


def kind_of(url, ctype):
    path = re.sub(r"[?#].*$", "", url)
    name = path.rsplit("/", 1)[-1].lower()
    ctype = ctype.lower()
    hashed = bool(HASH_RE.search(name)) and bool(re.search(r"\d", name))
    if "text/html" in ctype or name.endswith(".html") or (not ctype and "." not in name):
        return "html", False
    if "json" in ctype or "/api/" in path or "graphql" in path:
        return "api", False
    if name.endswith((".woff2", ".woff", ".ttf", ".otf")) or "font" in ctype:
        return "font", hashed
    if ctype.startswith("image/") or name.endswith((".png", ".jpg", ".jpeg", ".gif", ".webp", ".avif", ".svg", ".ico")):
        return ("hashed-asset" if hashed else "image"), hashed
    if name.endswith((".js", ".mjs", ".css", ".map", ".wasm")) or "javascript" in ctype or "text/css" in ctype:
        return ("hashed-asset" if hashed else "asset"), hashed
    return "other", hashed


def http_date(v):
    try:
        return email.utils.parsedate_to_datetime(v)
    except (TypeError, ValueError, IndexError):
        return None


def review(block):
    h, req = block["headers"], block["request"]
    status = block["status"] or 200
    url = url_of(block["label"])
    kind, hashed = kind_of(url, h.get("content-type", ""))
    cc, problems = parse_cc(h.get("cache-control", ""))
    flags = []

    def flag(code, detail):
        flags.append({"code": code, "severity": SEVERITY[code], "detail": detail})

    for p in problems:
        flag("INVALID_DIRECTIVE", p)
    cookies = h.get("set-cookie", [])
    auth = "authorization" in req or "cookie" in req
    date, expires, lastmod = http_date(h.get("date")), h.get("expires"), http_date(h.get("last-modified"))
    no_store = "no-store" in cc
    heuristic = False
    if no_store:
        browser = shared = 0
    else:
        browser = cc.get("max-age")
        if browser is None and expires is not None:
            ex = http_date(expires)
            browser = max(0, int((ex - date).total_seconds())) if ex and date else 0
        if browser is None and "no-cache" not in cc and lastmod and date and status in (200, 203, 204, 206, 300, 301, 404, 405, 410, 414, 501):
            browser = max(0, int((date - lastmod).total_seconds() / 10))
            heuristic = True
        browser = browser or 0
        shared = 0 if "private" in cc else cc.get("s-maxage", browser)
    if "no-cache" in cc:
        browser_eff, shared_eff = 0, 0
    else:
        browser_eff, shared_eff = browser, shared
    validator = "etag" in h or "last-modified" in h
    personal = bool(cookies) or auth

    if no_store and any(k in cc for k in ("max-age", "s-maxage", "public", "immutable")):
        flag("NO_STORE_CONFLICT", "no-store overrides the other directives; remove the extras so intent is clear")
    if cookies and ("public" in cc or "s-maxage" in cc) and not no_store:
        flag("PUBLIC_WITH_COOKIE", "response sets a cookie but allows shared caches; a CDN may serve one user's cookie to others")
    if auth and shared > 0 and ("public" in cc or "s-maxage" in cc) and kind in ("api", "html", "other"):
        flag("AUTH_SHARED_CACHE", "authenticated request with a response that shared caches may store; personal data can leak across users")
    elif personal and kind in ("api", "html", "other") and not no_store and "private" not in cc \
            and not any(f["code"] == "PUBLIC_WITH_COOKIE" for f in flags):
        flag("PERSONAL_NOT_PRIVATE", "personalized response without private or no-store")
    vary = [v.strip().lower() for v in h.get("vary", "").split(",") if v.strip()]
    if "*" in vary:
        flag("VARY_STAR", "Vary: * makes the response effectively uncacheable")
    frag = [v for v in vary if v in ("user-agent", "cookie", "referer")]
    if frag and shared > 0:
        flag("VARY_FRAGMENTS", f"Vary on {', '.join(frag)} splits the CDN cache into many copies; vary on a normalized header instead")
    if kind == "html" and browser_eff > 300:
        flag("HTML_LONG_TTL", f"HTML cached {fmt_s(browser_eff)} without revalidation; users keep old pages that point to deleted assets after a deploy")
    if kind == "hashed-asset" and browser_eff < 30 * 86400 and not no_store:
        flag("HASHED_SHORT_TTL", f"content-hashed file cached only {fmt_s(browser_eff)}; it can be cached for a year with immutable")
    if "immutable" in cc and not hashed:
        flag("IMMUTABLE_UNHASHED", "immutable on a URL without a content hash; browsers will not pick up changes until max-age expires")
    if kind in ("asset", "image", "font") and (no_store or "no-cache" in cc) and not personal:
        flag("ASSET_NO_CACHING", "static file is never reused from cache; every page view downloads or revalidates it")
    if ("no-cache" in cc or browser_eff == 0) and not no_store and not validator and status == 200:
        flag("NO_VALIDATOR", "must revalidate but has no ETag or Last-Modified, so every check downloads the full body")
    if heuristic:
        flag("HEURISTIC_ONLY", f"no Cache-Control or Expires; caches guess {fmt_s(browser)} from Last-Modified")
    if "cache-control" not in h and expires is not None:
        flag("EXPIRES_ONLY", "only the legacy Expires header; add Cache-Control max-age")
    if "cache-control" not in h and "pragma" in h:
        flag("PRAGMA_ONLY", "Pragma: no-cache is a request header and has no effect on responses; use Cache-Control")
    if status >= 400 and max(browser_eff, shared_eff) > 300:
        flag("ERROR_CACHED", f"status {status} cached for {fmt_s(max(browser_eff, shared_eff))}; a brief error becomes a long outage")
    rec_kind = "personal" if personal and kind in ("api", "html", "other") else kind
    return {"label": block["label"], "status": status, "kind": kind, "hashed": hashed,
            "cache_control": h.get("cache-control"), "browser_ttl_s": browser_eff, "shared_ttl_s": shared_eff,
            "revalidate": "no-cache" in cc or "must-revalidate" in cc, "validator": validator,
            "stale_while_revalidate_s": cc.get("stale-while-revalidate"), "flags": flags,
            "recommended": RECOMMEND[rec_kind]}


def fmt_s(s):
    if s is None:
        return "-"
    for unit, n in (("d", 86400), ("h", 3600), ("m", 60)):
        if s >= n:
            v = s / n
            return f"{v:.0f}{unit}" if v == int(v) else f"{v:.1f}{unit}"
    return f"{s}s"


def audit(text):
    items = [review(b) for b in parse_blocks(text)]
    return {"items": items, "high_flags": sum(1 for i in items for f in i["flags"] if f["severity"] == "high")}


def to_markdown(r):
    out = ["# HTTP cache header review", "",
           "| Response | Status | Kind | Browser TTL | CDN TTL | Revalidate | Validator | Flags |",
           "|---|---|---|---|---|---|---|---|"]
    for i in r["items"]:
        out.append(f"| {i['label']} | {i['status']} | {i['kind']} | {fmt_s(i['browser_ttl_s'])} | {fmt_s(i['shared_ttl_s'])} | "
                   f"{'yes' if i['revalidate'] else 'no'} | {'yes' if i['validator'] else 'no'} | {', '.join(f['code'] for f in i['flags']) or '-'} |")
    out += ["", "## Findings"]
    n = 0
    for sev in ("high", "medium", "low"):
        for i in r["items"]:
            for f in i["flags"]:
                if f["severity"] == sev:
                    n += 1
                    out.append(f"- **{sev.upper()} {f['code']}** {i['label']}: {f['detail']}")
    if not n:
        out.append("- No findings.")
    out += ["", "## Suggested Cache-Control"]
    for i in r["items"]:
        if i["flags"]:
            out.append(f"- {i['label']}: `{i['recommended']}` (now: `{i['cache_control'] or 'none'}`)")
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    def one(url, *lines):
        return review(parse_blocks("### GET " + url + "\nHTTP/1.1 200 OK\n" + "\n".join(lines))[0])

    def codes(item):
        return {f["code"] for f in item["flags"]}

    ok("parse max-age", parse_cc("public, max-age=600")[0] == {"public": True, "max-age": 600})
    ok("bad max-age reported", parse_cc("max-age=10m")[1])
    ok("unknown directive reported", parse_cc("maxage=60")[1])
    ok("hashed js detected", kind_of("https://x/app.3f9a1c7b.js", "") == ("hashed-asset", True))
    ok("unhashed css", kind_of("https://x/styles.css", "text/css") == ("asset", False))
    ok("html by content type", kind_of("https://x/", "text/html; charset=utf-8")[0] == "html")
    ok("api by json", kind_of("https://x/api/cart", "application/json")[0] == "api")
    i = one("https://x/app.3f9a1c7b.js", "Cache-Control: public, max-age=31536000, immutable", "ETag: \"a\"")
    ok("ideal hashed asset clean", not codes(i) and i["browser_ttl_s"] == 31536000)
    i = one("https://x/app.3f9a1c7b.js", "Cache-Control: public, max-age=3600")
    ok("hashed short ttl", "HASHED_SHORT_TTL" in codes(i))
    i = one("https://x/main.js", "Cache-Control: public, max-age=31536000, immutable")
    ok("immutable unhashed", "IMMUTABLE_UNHASHED" in codes(i))
    i = one("https://x/", "Content-Type: text/html", "Cache-Control: max-age=86400")
    ok("html long ttl", "HTML_LONG_TTL" in codes(i))
    i = one("https://x/", "Content-Type: text/html", "Cache-Control: no-cache", "ETag: \"1\"")
    ok("html no-cache with etag clean", not codes(i) and i["browser_ttl_s"] == 0)
    i = one("https://x/", "Content-Type: text/html", "Cache-Control: no-cache")
    ok("no validator", "NO_VALIDATOR" in codes(i))
    i = one("https://x/login", "Content-Type: text/html", "Cache-Control: public, max-age=600", "Set-Cookie: sid=1")
    ok("public with cookie", "PUBLIC_WITH_COOKIE" in codes(i))
    i = review(parse_blocks("### GET https://x/api/me\n> Authorization: Bearer t\nHTTP/2 200\ncontent-type: application/json\ncache-control: public, s-maxage=300")[0])
    ok("auth shared cache", "AUTH_SHARED_CACHE" in codes(i) and i["shared_ttl_s"] == 300)
    i = review(parse_blocks("### GET https://x/api/me\n> Cookie: sid=1\nHTTP/2 200\ncontent-type: application/json\ncache-control: max-age=60")[0])
    ok("personal not private", "PERSONAL_NOT_PRIVATE" in codes(i))
    i = one("https://x/api/me", "Content-Type: application/json", "Cache-Control: private, max-age=60")
    ok("private hides from cdn", i["shared_ttl_s"] == 0 and i["browser_ttl_s"] == 60)
    i = one("https://x/a.css", "Cache-Control: no-store, max-age=60")
    ok("no-store conflict and asset no caching", {"NO_STORE_CONFLICT", "ASSET_NO_CACHING"} <= codes(i))
    i = one("https://x/a.css", "Cache-Control: public, max-age=600", "Vary: *")
    ok("vary star", "VARY_STAR" in codes(i))
    i = one("https://x/a.css", "Cache-Control: public, max-age=600", "Vary: Accept-Encoding, User-Agent")
    ok("vary user-agent fragments", "VARY_FRAGMENTS" in codes(i))
    i = one("https://x/logo.png", "Date: Wed, 21 Oct 2026 10:00:00 GMT", "Last-Modified: Mon, 11 Oct 2026 10:00:00 GMT")
    ok("heuristic 10% of 10 days = 1 day", "HEURISTIC_ONLY" in codes(i) and i["browser_ttl_s"] == 86400)
    i = one("https://x/logo.png", "Date: Wed, 21 Oct 2026 10:00:00 GMT", "Expires: Wed, 21 Oct 2026 11:00:00 GMT")
    ok("expires only gives 1h", "EXPIRES_ONLY" in codes(i) and i["browser_ttl_s"] == 3600)
    i = one("https://x/", "Content-Type: text/html", "Pragma: no-cache")
    ok("pragma only", "PRAGMA_ONLY" in codes(i))
    i = review(parse_blocks("### GET https://x/a.css\nHTTP/1.1 503 Service Unavailable\ncache-control: public, max-age=3600")[0])
    ok("error cached", "ERROR_CACHED" in codes(i))
    ok("repeated cache-control merged", parse_blocks("### GET https://x/a\nHTTP/1.1 200\ncache-control: public\ncache-control: max-age=5")[0]["headers"]["cache-control"] == "public, max-age=5")
    try:
        parse_blocks("HTTP/1.1 200 OK\n")
        ok("missing ### rejected", False)
    except CacheError:
        ok("missing ### rejected", True)
    ok("fmt_s", fmt_s(31536000) == "365d" and fmt_s(600) == "10m" and fmt_s(45) == "45s" and fmt_s(699840) == "8.1d")
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Review HTTP caching headers.")
    ap.add_argument("file", nargs="?", help="responses text file ('-' for stdin)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("responses file required (or --self-test)")
    try:
        text = sys.stdin.read() if a.file == "-" else open(a.file, encoding="utf-8").read()
        r = audit(text)
    except (OSError, CacheError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    return 1 if r["high_flags"] else 0


if __name__ == "__main__":
sys.exit(main())根据航班时间和你平时的睡眠时间,生成逐日的时差调整计划。计算考虑夏令时的时间差,选择提前或延后(包括向东长途旅行时绕远路的方案),估算调整所需天数,并列出出发前的就寝时间调整、机上睡眠安排、每日睡眠窗口、应接触和应避开的的光照、咖啡因截止时间和小睡上限。会标记短途旅行。内含一个仅用标准库的 Python 规划器,支持 --self-test。
---
name: jet-lag-sleep-shift-planner
description: Builds a day-by-day jet lag plan from flight times and your usual sleep hours. Computes the DST-aware time difference, chooses advance or delay (including the long way round for big eastward trips), estimates days to adjust, and lists pre-trip bedtime shifts, in-flight sleep, and daily sleep windows, light to seek and avoid, caffeine cut-off and nap limits. Flags short trips. Includes a stdlib Python planner with --self-test.
---

# Jet Lag Sleep Shift Planner

You help travelers arrive rested. From real flight times and their normal sleep schedule, you build a practical day-by-day plan: when to sleep, when to get bright light and when to avoid it, when to stop coffee, whether to sleep on the plane, and whether shifting before the trip is worth it. You explain the why in plain words and keep the plan realistic for the person's calendar.

## Files in this skill

- `scripts/jetlag_plan.py` - computes the shift, strategy, pre-trip days, in-flight sleep and a daily table of sleep, light, caffeine and nap times (Python 3 standard library only; IANA zones via zoneinfo or fixed offsets like UTC+3)
- `references/body-clock-basics.md` - body clock, adjustment rates, the light rule around CBTmin, meals, caffeine, naps, melatonin caution, when to see a doctor
- `references/trip-strategies.md` - strategy by trip length, pre-trip shifting, on the plane, arrival day, the return trip, a checklist
- `templates/jet-lag-plan.md` - a one-page plan to fill in or print
- `examples/istanbul-to-los-angeles.json` - an 11-hour westward conference trip in November, with a return trip

## Workflow

### 1. Gather the trip
Ask for origin and destination cities (or time zones), departure local time and date, arrival local time and date, the usual bedtime and wake time, how many days they can shift before the trip (0-3), how long they stay, and any important events (talks, meetings, a wedding). Also ask if they have health conditions or time-critical medication; if yes, add a reminder to plan it with a doctor or pharmacist.

### 2. Run the planner
```
python3 scripts/jetlag_plan.py examples/istanbul-to-los-angeles.json
python3 scripts/jetlag_plan.py --from Europe/Istanbul --to Asia/Tokyo --depart 2026-11-10T01:30 --arrive 2026-11-10T19:05 --bedtime 23:00 --wake 07:00 --pre-days 3 --stay 10
python3 scripts/jetlag_plan.py trip.json --json
python3 scripts/jetlag_plan.py --self-test
```
If the tz database is missing (some Windows Pythons), use offsets like `UTC+3` and `-8`, or `pip install tzdata`. Exit code 2 means bad input.

### 3. Shape the plan
Use `references/trip-strategies.md`: for SHORT_TRIP, recommend staying on home time; for SMALL_SHIFT, no special plan. Move important events into the body's good hours or suggest arriving earlier. Explain the light windows with `references/body-clock-basics.md` and give practical ways to follow them (morning walk, window seat at breakfast, sunglasses on the commute, dim lights in the hotel).

### 4. Deliver
Fill `templates/jet-lag-plan.md` with the table and the 3-5 most important actions. Offer to add the sleep and light windows as calendar reminders.

## Example result
For `examples/istanbul-to-los-angeles.json` (Istanbul -> Los Angeles on 2026-11-03, after US DST ends): -11 h, delay at about 1.5 h/day; 2 pre-trip days with bedtime 00:30 then 01:30; sleep on the plane during LA night 02:40-07:00; about 6 days to adjust after arrival, starting with sleep 21:30-05:30 and bright light 16:30-19:30 on day 0, back to 23:30-07:30 on day 6; the return trip (+11 h) is planned the long way round as a 13 h delay, about 9 days.

## Rules

- This is general wellness guidance, not medical advice; do not give melatonin or sleep medication doses.
- Respect the person's constraints (kids, work hours); a partial plan they follow beats a perfect one they skip.
- Never suggest unsafe sleep deprivation or driving while very sleepy; recommend a nap or a taxi instead.
- Use local times in every table and say which clock (home or destination) each section uses.
FILE:references/body-clock-basics.md
# Body Clock Basics for Travelers

## Why jet lag happens
Your body clock (circadian rhythm) runs on home time and shifts only gradually. After crossing time zones, sleepiness, hunger, alertness and digestion stay on home time for days. Typical symptoms: trouble falling asleep or waking at 3 a.m., daytime sleepiness, poor focus, upset stomach.

## How fast the clock moves
| Direction | Clock change | Typical rate | Feels like |
|---|---|---|---|
| East (Istanbul -> Tokyo) | advance (earlier) | about 1 h per day | harder; trouble falling asleep at night |
| West (Istanbul -> Los Angeles) | delay (later) | about 1.5 h per day | easier; sleepy early evening, awake at 4 a.m. |
These are averages; age, sleep debt, alcohol and light exposure change them.

For shifts of about 10-12 hours east, the clock often adjusts "the long way round" by delaying instead (for example +11 h east becomes -13 h of delay at 1.5 h/day = 9 days instead of 11). The planner picks whichever takes fewer days.

## The light rule
The strongest signal for the body clock is bright light. Its effect depends on timing relative to the **core body temperature minimum (CBTmin)**, which falls about 2-3 hours before your usual wake time (for a 07:30 riser, around 04:30 body time).
- Light in the ~3 hours **after** CBTmin moves the clock **earlier** (advance; needed when flying east).
- Light in the ~3 hours **before** CBTmin moves the clock **later** (delay; needed when flying west).
- Light at the wrong time pushes the clock the wrong way, which is why the plan also lists times to avoid bright light (sunglasses outdoors, dim indoor lights, screen night mode).
Because CBTmin moves each day, the windows move too. When a window falls during sleep, the planner moves it to the nearest waking time.

## Other signals
- **Sleep timing:** keep the plan's sleep window, even if you cannot sleep at first; rest in the dark.
- **Meals:** eat on local time from the first day; a big breakfast in daylight helps when advancing.
- **Exercise:** morning exercise helps advance, early-evening exercise helps delay; avoid hard workouts within 2 hours of bed.
- **Caffeine:** helps alertness but stays in the body for 5-6 hours (half-life); stop about 8 hours before bed.
- **Naps:** up to 20 minutes, before the plan's "naps end by" time. Long naps anchor you to home time.
- **Alcohol:** makes sleep worse and dehydration worse; skip it on the flight.
- **Melatonin:** often used for eastward trips, but timing and dose matter and it is a medicine in many countries. Ask a doctor or pharmacist; the planner gives no dosing.

## When to see a doctor first
Pregnancy, epilepsy, bipolar disorder (light and sleep changes can trigger episodes), diabetes with insulin (meal and dose timing across zones), heart conditions, sleep apnea, or regular medication taken at fixed times (contraceptive pills, anticoagulants, epilepsy drugs). Plan the medication schedule with a professional.
FILE:references/trip-strategies.md
# Trip Strategies

## Pick the strategy by trip length and shift
| Trip | Shift | Strategy |
|---|---|---|
| 1-2 days | any | Stay on home time. Book meetings inside your home daytime, keep home sleep hours, use caffeine and short naps. |
| 3-5 days | up to 3 h | Switch to local time on arrival; no pre-trip shift needed. |
| 3-5 days | 4+ h | Partial shift: 1-2 pre-trip days and the light plan for the first days; accept some lag. |
| 6+ days | 4+ h | Full plan: 2-3 pre-trip days, light plan until adjusted. |
| Important event on day 1-2 | 6+ h | Arrive earlier if possible (one day per 1-1.5 h of shift is ideal), or schedule the event in the body's best hours. |

## Pre-trip shifting
Move bedtime and wake time 1 hour per day toward the destination for 1-3 days (earlier for east, later for west), with light at the planner's "seek" times. Even 2 hours of pre-shift removes 1-2 days of jet lag. Stop if it hurts work or family routines; partial is fine.

## On the plane
- Set your watch and phone to destination time when you board.
- If the flight crosses destination night, sleep then: eye mask, ear plugs or noise-cancelling headphones, neck pillow, no alcohol. Otherwise stay awake with light and short naps only.
- Drink water regularly; walk and stretch every 1-2 hours.
- Eat at destination meal times when practical.

## Arrival day
- Westward evening arrival: go outside in daylight if any is left, stay up until the planned bedtime (a 20-minute nap before the cut-off is fine).
- Eastward morning arrival: follow the seek/avoid light windows; if you must work, put bright tasks in the seek window.

## Coming home
The return trip is a new shift in the opposite direction. Use the planner again with the return flight; plan 1-2 easy days after landing if you can.

## Business traveler checklist
- [ ] Planner run with real flight times
- [ ] Calendar: no critical meetings in the body's night
- [ ] Hotel: blackout curtains or eye mask; ask for a quiet room
- [ ] Light: sunglasses for avoid windows, a walk or a light box for seek windows
- [ ] Medication timing checked with a pharmacist
FILE:templates/jet-lag-plan.md
# Jet Lag Plan - <traveler> - <origin> to <destination>

**Flight:** <depart local> -> <arrive local> (<hours> h)  **Time difference:** <+/- h>  **Strategy:** <advance / delay / stay on home time>
**Usual sleep:** <bedtime>-<wake>  **Pre-trip shift:** <h>  **Expected days to adjust:** <n>

## Before the trip
| Date | Sleep | Bright light | Avoid light | Notes |
|---|---|---|---|---|
| | | | | |

## Flight
- Sleep on board: <times or "stay awake">
- Meals: <destination times>
- Watch set to destination time: [ ]

## At the destination
| Date | Sleep | Bright light | Avoid light | Caffeine until | Naps end by | Key events |
|---|---|---|---|---|---|---|
| | | | | | | |

## Packing
- [ ] Eye mask and ear plugs  - [ ] Sunglasses  - [ ] Water bottle  - [ ] Medication schedule (checked with a professional)

## Return
- Shift: <h>, about <n> days to readjust; easy days planned: <dates>
FILE:examples/istanbul-to-los-angeles.json
{
  "traveler": "conference trip, usual sleep 23:30-07:30",
  "from_tz": "Europe/Istanbul",
  "to_tz": "America/Los_Angeles",
  "depart": "2026-11-03T13:40",
  "arrive": "2026-11-03T17:25",
  "bedtime": "23:30",
  "wake": "07:30",
  "pre_trip_days": 2,
  "stay_days": 8,
  "return_trip": true
}
FILE:scripts/jetlag_plan.py
#!/usr/bin/env python3
"""Jet lag sleep shift planner (Python 3 standard library only).

Input: a trip JSON file (or the same fields as command-line flags):
  {"from_tz": "Europe/Istanbul", "to_tz": "America/Los_Angeles",
   "depart": "2026-11-03T13:40", "arrive": "2026-11-03T17:25",
   "bedtime": "23:30", "wake": "07:30", "pre_trip_days": 2, "stay_days": 8}
Time zones: IANA names (zoneinfo, DST-aware; needs the system tz database or the tzdata
package) or fixed offsets like "UTC+3", "+05:30", "-8".  depart is local time at the origin,
arrive is local time at the destination.

Model (rules of thumb used by sleep clinics, not a medical device):
  - shift = destination offset - origin offset, normalized to -12..+12 h (+ = east).
  - the body clock moves about 1 h/day when advancing (eastward) and 1.5 h/day when
    delaying (westward); for big eastward shifts the planner picks the direction that
    takes fewer days (often delaying "the long way round").
  - optional pre-trip shift: 1 h/day for pre_trip_days, toward the destination.
  - core body temperature minimum (CBTmin) ~3 h before usual wake time. Light in the 3 h
    after CBTmin advances the clock, light in the 3 h before it delays the clock.
  - planned sleep is a compromise: target local bedtime moved toward body time by
    min(2 h, half the remaining gap). Caffeine stops 8 h and naps (max 20 min) end 7 h
    before planned bedtime.
Usage:
  python3 jetlag_plan.py trip.json
  python3 jetlag_plan.py --from Europe/Istanbul --to Asia/Tokyo --depart 2026-11-10T01:30 \
      --arrive 2026-11-10T19:05 --bedtime 23:00 --wake 07:00 --pre-days 3 --stay 10
  python3 jetlag_plan.py trip.json --json
  python3 jetlag_plan.py --self-test
Exit code: 0 OK, 2 bad input.
"""
import argparse
import datetime as dt
import json
import math
import re
import sys

ADVANCE_RATE = 1.0
DELAY_RATE = 1.5


class TripError(ValueError):
    pass


def parse_tz(name):
    s = str(name).strip()
    m = re.fullmatch(r"(?:UTC|GMT)?\s*([+-])(\d{1,2})(?::?(\d{2}))?", s, re.I)
    if m:
        sign = 1 if m.group(1) == "+" else -1
        mins = int(m.group(2)) * 60 + int(m.group(3) or 0)
        if mins > 14 * 60:
            raise TripError(f"offset out of range: {s!r}")
        return dt.timezone(dt.timedelta(minutes=sign * mins), s)
    if s.upper() in ("UTC", "GMT", "Z"):
        return dt.timezone.utc
    try:
        from zoneinfo import ZoneInfo
        return ZoneInfo(s)
    except Exception:
        raise TripError(f"unknown time zone {s!r}; use an IANA name like Europe/Istanbul or an offset like UTC+3")


def parse_hm(s, field):
    m = re.fullmatch(r"(\d{1,2}):(\d{2})", str(s).strip())
    if not m or int(m.group(1)) > 23 or int(m.group(2)) > 59:
        raise TripError(f"{field} must be HH:MM, got {s!r}")
    return int(m.group(1)) * 60 + int(m.group(2))


def parse_local(s, tz, field):
    try:
        t = dt.datetime.fromisoformat(str(s).strip())
    except ValueError:
        raise TripError(f"{field} must be YYYY-MM-DDTHH:MM, got {s!r}")
    if t.tzinfo is not None:
        t = t.replace(tzinfo=None)
    return t.replace(tzinfo=tz)


def hm(mins):
    mins = round(mins) % 1440
    return f"{mins // 60:02d}:{mins % 60:02d}"


def offset_h(t):
    return t.utcoffset().total_seconds() / 3600


def choose_direction(shift):
    """shift in -12..12 (east positive). Return (signed hours to move the body, rate, label)."""
    if shift == 0:
        return 0.0, ADVANCE_RATE, "none"
    if shift > 0:
        adv_days = math.ceil(shift / ADVANCE_RATE)
        alt = shift - 24
        del_days = math.ceil(-alt / DELAY_RATE)
        if del_days < adv_days:
            return alt, DELAY_RATE, "delay (long way round)"
        return shift, ADVANCE_RATE, "advance"
    del_days = math.ceil(-shift / DELAY_RATE)
    alt = shift + 24
    adv_days = math.ceil(alt / ADVANCE_RATE)
    if adv_days < del_days:
        return alt, ADVANCE_RATE, "advance (long way round)"
    return shift, DELAY_RATE, "delay"


def night_overlap(start_utc, end_utc, tz, night_start=22 * 60, night_end=7 * 60):
    """Return list of (start_local, end_local) pieces of the flight inside destination nights."""
    pieces = []
    t = start_utc
    step = dt.timedelta(minutes=5)
    cur = None
    while t < end_utc:
        loc = t.astimezone(tz)
        m = loc.hour * 60 + loc.minute
        is_night = m >= night_start or m < night_end
        if is_night and cur is None:
            cur = loc
        if not is_night and cur is not None:
            pieces.append((cur, loc))
            cur = None
        t += step
    if cur is not None:
        pieces.append((cur, end_utc.astimezone(tz)))
    return pieces


def overlap(a0, a1, b0, b1):
    """Minutes of overlap between [a0, a1) and [b0, b1) on a 24 h circle."""
    best = 0
    for k in (-1440, 0, 1440):
        best += max(0, min(a1, b1 + k) - max(a0, b0 + k))
    return best


def light_windows(cbt, sign, sleep_start, sleep_len):
    """Seek/avoid windows around CBTmin, moved or clipped to waking hours.
    sign > 0 (advance): seek 3 h after CBTmin, avoid 3 h before; sign < 0 (delay): the reverse.
    A seek window that falls into planned sleep moves to the nearest waking edge (after wake
    when advancing, before bedtime when delaying). Avoid windows are clipped to waking time."""
    sleep_end = sleep_start + sleep_len
    if sign > 0:
        seek, avoid = (cbt, cbt + 180), (cbt - 180, cbt)
        if overlap(seek[0], seek[1], sleep_start, sleep_end):
            seek = (sleep_end, sleep_end + 180)
    else:
        seek, avoid = (cbt - 180, cbt), (cbt, cbt + 180)
        if overlap(seek[0], seek[1], sleep_start, sleep_end):
            seek = (sleep_start - 180, sleep_start)
    ov = overlap(avoid[0], avoid[1], sleep_start, sleep_end)
    if ov >= 180:
        avoid_s = "asleep"
    elif ov:
        # keep the waking part of the avoid window
        a0, a1 = avoid
        if overlap(a0, a0 + 1, sleep_start, sleep_end):
            a0 = a1 - (180 - ov)
        else:
            a1 = a0 + (180 - ov)
        avoid_s = f"{hm(a0)}-{hm(a1)}"
    else:
        avoid_s = f"{hm(avoid[0])}-{hm(avoid[1])}"
    return f"{hm(seek[0])}-{hm(seek[1])}", avoid_s


def plan(trip):
    for k in ("from_tz", "to_tz", "depart", "arrive"):
        if not trip.get(k):
            raise TripError(f"missing {k}")
    ftz, ttz = parse_tz(trip["from_tz"]), parse_tz(trip["to_tz"])
    dep = parse_local(trip["depart"], ftz, "depart")
    arr = parse_local(trip["arrive"], ttz, "arrive")
    if arr.astimezone(dt.timezone.utc) <= dep.astimezone(dt.timezone.utc):
        raise TripError("arrive must be after depart (check the dates and time zones)")
    bed = parse_hm(trip.get("bedtime", "23:00"), "bedtime")
    wake = parse_hm(trip.get("wake", "07:00"), "wake")
    sleep_len = (wake - bed) % 1440
    if not 4 * 60 <= sleep_len <= 12 * 60:
        raise TripError("bedtime to wake must be 4-12 hours")
    pre = int(trip.get("pre_trip_days", 0))
    stay = int(trip.get("stay_days", 7))
    if pre < 0 or pre > 4 or stay < 1:
        raise TripError("pre_trip_days must be 0-4 and stay_days at least 1")
    shift = offset_h(arr) - offset_h(dep.astimezone(ftz))
    shift = ((shift + 12) % 24) - 12 if abs(shift) > 12 else shift
    if shift == -12:
        shift = 12.0
    move, rate, direction = choose_direction(shift)
    sign = 1 if move > 0 else -1
    flags = []
    if abs(shift) <= 2:
        flags.append("SMALL_SHIFT: 2 h or less; most people adapt within a day, keep usual habits on local time")
    if stay <= 2 and abs(shift) >= 3:
        flags.append("SHORT_TRIP: 2 days or fewer; consider staying on home time and scheduling meetings inside your home daytime")
    if "long way round" in direction:
        flags.append(f"LONG_WAY_ROUND: a {shift:+g} h shift is planned as {move:+g} h, which usually takes fewer days")
    pre_used = min(pre, int(abs(move))) if move else 0
    pre_days = []
    for i in range(1, pre_used + 1):
        b = bed - sign * 60 * i
        cbt = wake - 180 - sign * 60 * i
        seek_s, avoid_s = light_windows(cbt, sign, b, sleep_len)
        pre_days.append({"day": f"pre {i - pre_used - 1}", "date": str((dep.date() - dt.timedelta(days=pre_used - i + 1))),
                         "sleep": f"{hm(b)}-{hm(b + sleep_len)}", "seek_light": seek_s,
                         "avoid_light": avoid_s, "clock": "home time"})
    body = sign * pre_used  # hours already moved toward destination
    total = abs(move)
    days_needed = math.ceil(max(0.0, total - pre_used) / rate) if move else 0
    days = []
    d = 0
    while True:
        remaining = move - body  # signed hours the body is still away from local time
        gap = abs(remaining)
        comp = min(120, gap * 60 / 2)
        # remaining > 0: body clock is behind local time, so it wants to sleep later (and vice versa)
        b = bed + (comp if remaining > 0 else -comp) if gap else bed
        cbt_local = (wake - 180) + remaining * 60
        if gap < 0.5:
            seek_s, avoid_s = "daylight as usual", "-"
        else:
            seek_s, avoid_s = light_windows(cbt_local, sign, b, sleep_len)
        if remaining > 0:
            status = f"{gap:g} h behind local time"
        elif remaining < 0:
            status = f"{gap:g} h ahead of local time"
        else:
            status = "adjusted"
        days.append({"day": d, "date": str(arr.date() + dt.timedelta(days=d)), "body_clock": status,
                     "sleep": f"{hm(b)}-{hm(b + sleep_len)}", "seek_light": seek_s, "avoid_light": avoid_s,
                     "caffeine_until": hm(b - 480), "naps_end_by": hm(b - 420)})
        if gap == 0 or d + 1 >= stay:
            break
        body = body + sign * min(rate, gap)
        d += 1
    flight_h = (arr.astimezone(dt.timezone.utc) - dep.astimezone(dt.timezone.utc)).total_seconds() / 3600
    nights = night_overlap(dep.astimezone(dt.timezone.utc), arr.astimezone(dt.timezone.utc), ttz)
    nights = [(a, b) for a, b in nights if (b - a).total_seconds() >= 3600]
    if nights:
        inflight = "sleep during destination night: " + "; ".join(f"{a:%a %H:%M}-{b:%H:%M}" for a, b in nights)
    else:
        inflight = "flight is during destination daytime: stay awake, get daylight/screen light, at most a 20-minute nap"
    res = {"from_tz": str(trip["from_tz"]), "to_tz": str(trip["to_tz"]), "shift_h": shift, "plan_move_h": move,
           "direction": direction, "rate_h_per_day": rate, "pre_trip_shift_h": pre_used,
           "days_to_adjust_after_arrival": days_needed, "flight_h": round(flight_h, 2),
           "arrive_local": arr.strftime("%Y-%m-%d %H:%M"), "in_flight": inflight, "flags": flags,
           "pre_trip": pre_days, "days": days}
    if trip.get("return_trip"):
        back, brate, bdir = choose_direction(-shift)
        res["return"] = {"shift_h": -shift, "direction": bdir,
                         "days_to_adjust": math.ceil(abs(back) / brate) if back else 0}
    return res


def to_markdown(r):
    out = [f"# Jet lag plan: {r['from_tz']} -> {r['to_tz']}", "",
           f"- Time difference: {r['shift_h']:+g} h ({'east' if r['shift_h'] > 0 else 'west' if r['shift_h'] < 0 else 'none'}); "
           f"plan: {r['direction']} {abs(r['plan_move_h']):g} h at about {r['rate_h_per_day']:g} h/day",
           f"- Pre-trip shift: {r['pre_trip_shift_h']} h; about {r['days_to_adjust_after_arrival']} day(s) to adjust after arrival",
           f"- Flight: {r['flight_h']:g} h, arriving {r['arrive_local']} local; {r['in_flight']}"]
    if "return" in r:
        out.append(f"- Return trip: {r['return']['shift_h']:+g} h, {r['return']['direction']}, about {r['return']['days_to_adjust']} day(s) to readjust")
    for f in r["flags"]:
        out.append(f"- **{f.split(':')[0]}**:{f.split(':', 1)[1]}")
    if r["pre_trip"]:
        out += ["", "## Before you fly (home time)", "| Day | Date | Sleep | Seek bright light | Avoid bright light |", "|---|---|---|---|---|"]
        for p in r["pre_trip"]:
            out.append(f"| {p['day']} | {p['date']} | {p['sleep']} | {p['seek_light']} | {p['avoid_light']} |")
    out += ["", "## At the destination (local time)",
            "| Day | Date | Body clock | Sleep | Seek bright light | Avoid bright light | Caffeine until | Naps end by |",
            "|---|---|---|---|---|---|---|---|"]
    for d in r["days"]:
        out.append(f"| {d['day']} | {d['date']} | {d['body_clock']} | {d['sleep']} | {d['seek_light']} | {d['avoid_light']} | {d['caffeine_until']} | {d['naps_end_by']} |")
    out += ["", "Light windows that fall inside your sleep time can be skipped; use sunglasses outdoors during 'avoid' windows.",
            "Rules of thumb only. Ask a doctor or pharmacist before using melatonin or sleep medication."]
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    base = {"from_tz": "Europe/Istanbul", "to_tz": "America/Los_Angeles", "depart": "2026-11-03T13:40",
            "arrive": "2026-11-03T17:25", "bedtime": "23:30", "wake": "07:30", "pre_trip_days": 2, "stay_days": 10}
    ok("fixed offset parse", parse_tz("UTC+3").utcoffset(None) == dt.timedelta(hours=3) and parse_tz("+05:30").utcoffset(None) == dt.timedelta(hours=5, minutes=30))
    ok("negative offset parse", parse_tz("-8").utcoffset(None) == dt.timedelta(hours=-8))
    r = plan(base)
    ok("IST->LA after US DST ends is -11 h", r["shift_h"] == -11)
    ok("westward plan delays", r["direction"] == "delay" and r["plan_move_h"] == -11)
    ok("pre-trip 2 h used", r["pre_trip_shift_h"] == 2 and len(r["pre_trip"]) == 2)
    ok("days to adjust ceil(9/1.5)=6", r["days_to_adjust_after_arrival"] == 6)
    ok("pre-trip bedtime later for westward", r["pre_trip"][0]["sleep"].startswith("00:30") and r["pre_trip"][1]["sleep"].startswith("01:30"))
    ok("day 0 body 9 h ahead", r["days"][0]["body_clock"] == "9 h ahead of local time")
    ok("day 0 compromise bedtime 21:30", r["days"][0]["sleep"] == "21:30-05:30")
    ok("delay: seek light before CBTmin", r["days"][0]["seek_light"] == "16:30-19:30")
    ok("delay: avoid window clipped at bedtime", r["days"][0]["avoid_light"] == "19:30-21:30")
    ok("delay: seek window moved before bedtime", r["days"][3]["seek_light"] == "18:30-21:30" and r["days"][3]["avoid_light"] == "asleep")
    ok("pre-trip delay light in the evening", r["pre_trip"][0]["seek_light"] == "21:30-00:30")
    ok("overlap on circle", overlap(1380, 1500, 0, 60) == 60 and overlap(600, 700, 0, 60) == 0)
    ok("plan ends adjusted", r["days"][-1]["body_clock"] == "adjusted" and r["days"][-1]["sleep"] == "23:30-07:30")
    ok("plan length 7 days (0..6)", len(r["days"]) == 7)
    ok("flight of 14.75 h", r["flight_h"] == 14.75)
    r2 = plan(dict(base, to_tz="America/Los_Angeles", depart="2026-10-20T13:40", arrive="2026-10-20T16:25"))
    ok("IST->LA during US DST is -10 h", r2["shift_h"] == -10)
    r3 = plan(dict(base, to_tz="Asia/Tokyo", depart="2026-11-10T01:30", arrive="2026-11-10T19:05", pre_trip_days=3))
    ok("IST->Tokyo +6 advance", r3["shift_h"] == 6 and r3["direction"] == "advance" and r3["days_to_adjust_after_arrival"] == 3)
    ok("advance: seek light moved to after wake", r3["days"][0]["seek_light"] == "09:00-12:00" and r3["days"][0]["avoid_light"] == "asleep")
    ok("pre-trip bedtime earlier for eastward", r3["pre_trip"][0]["sleep"].startswith("22:30"))
    ok("+11 east goes long way round", choose_direction(11) == (-13, DELAY_RATE, "delay (long way round)"))
    ok("+9 east stays advance", choose_direction(9)[2] == "advance")
    ok("-12 normalized to +12 then delay -12", choose_direction(12)[0] == -12)
    r4 = plan(dict(base, to_tz="Europe/Berlin", depart="2026-11-03T08:00", arrive="2026-11-03T09:00", stay_days=2))
    ok("small shift flag", any(f.startswith("SMALL_SHIFT") for f in r4["flags"]))
    r5 = plan(dict(base, stay_days=2))
    ok("short trip flag", any(f.startswith("SHORT_TRIP") for f in r5["flags"]) and len(r5["days"]) == 2)
    ok("in-flight sleep in LA night 02:40-07:00", r["in_flight"].endswith("Tue 02:40-07:00"))
    ok("Tokyo daytime flight: stay awake", "destination daytime" in r3["in_flight"])
    ok("caffeine 8 h before bed", r["days"][-1]["caffeine_until"] == "15:30" and r["days"][-1]["naps_end_by"] == "16:30")
    for bad, label in ((dict(base, to_tz="Mars/Olympus"), "unknown tz rejected"), (dict(base, bedtime="25:00"), "bad bedtime rejected"),
                       (dict(base, arrive="2026-11-02T10:00"), "arrival before departure rejected"), (dict(base, pre_trip_days=9), "pre-trip >4 rejected")):
        try:
            plan(bad)
            ok(label, False)
        except TripError:
            ok(label, True)
    ok("hm wraps midnight", hm(-30) == "23:30" and hm(1500) == "01:00")
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Plan sleep and light timing to beat jet lag.")
    ap.add_argument("file", nargs="?", help="trip JSON")
    ap.add_argument("--from", dest="from_tz")
    ap.add_argument("--to", dest="to_tz")
    ap.add_argument("--depart")
    ap.add_argument("--arrive")
    ap.add_argument("--bedtime")
    ap.add_argument("--wake")
    ap.add_argument("--pre-days", type=int, dest="pre_trip_days")
    ap.add_argument("--stay", type=int, dest="stay_days")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    try:
        trip = json.load(open(a.file, encoding="utf-8")) if a.file else {}
        for k in ("from_tz", "to_tz", "depart", "arrive", "bedtime", "wake", "pre_trip_days", "stay_days"):
            if getattr(a, k) is not None:
                trip[k] = getattr(a, k)
        r = plan(trip)
    except (OSError, TripError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    return 0


if __name__ == "__main__":
sys.exit(main())关于 PostgreSQL 中模式设计、索引、查询和运维的有主见约定。
# 后端工程师的 PostgreSQL 偏好
- 主键使用 bigint 标识列(GENERATED ALWAYS AS IDENTITY);只有当 id 必须在数据库之外生成时才用 UUIDv7。置信度:0.80
- 时间戳以 UTC 存为 timestamptz,绝不用 timestamp without time zone。置信度:0.95
- 长度限制用带 CHECK 约束的 text,而不是 varchar(n)。置信度:0.80
- 金额存为 numeric 或整数最小单位,绝不用 float。置信度:0.95
- 表名用复数 snake_case,外键命名为 <singular>_id。置信度:0.70
- 默认声明 NOT NULL,仅当“未知”是真实状态时才允许 NULL。置信度:0.85
- 在数据库中用外键、UNIQUE 和 CHECK 约束强制不变量,而不只在应用代码中。置信度:0.90
- 为每个用于连接或级联删除的外键列建立索引。置信度:0.85
- 添加索引前先读 EXPLAIN (ANALYZE, BUFFERS),添加后再读以证明其有效。置信度:0.90
- 对于倾斜的过滤条件,优先用部分索引和表达式索引,而非宽复合索引。置信度:0.70
- 在大表上使用 CREATE INDEX CONCURRENTLY 创建索引。置信度:0.90
- 对真正无模式的属性使用 jsonb,但把用于过滤的字段提升为真实列。置信度:0.80
- 用键集分页(WHERE id > $last ORDER BY id LIMIT n),而不是大 OFFSET 值。置信度:0.85
- 保持事务简短,绝不在网络调用期间让事务保持打开。置信度:0.90
- 按应用角色设置 statement_timeout 和 idle_in_transaction_session_timeout。置信度:0.85
- 在数据库前放置以事务模式运行的连接池器,如 PgBouncer。置信度:0.80
- 在引入独立代理之前,用 SELECT ... FOR UPDATE SKIP LOCKED 实现简单作业队列。置信度:0.70
- 用 INSERT ... ON CONFLICT 实现幂等 upsert。置信度:0.85
- 为每个服务分配最小权限的独立角色;应用绝不以超级用户身份连接。置信度:0.90
- 开启 pg_stat_statements,每周审查最慢的查询。置信度:0.85
- 为可读性编写 CTE,同时知道 Postgres 12+ 会内联它们,除非加上 MATERIALIZED。置信度:0.65
- 定期测试从备份做时间点恢复;未测试过的备份不算数。置信度:0.95
关于让网页加载更快、对真实用户保持响应性的有主见偏好。
# 前端工程师的 Web 性能偏好
- 从真实用户测量 Core Web Vitals(LCP、INP、CLS),而不只是从实验室的 Lighthouse 运行。置信度:0.90
- 为 JavaScript 体积和 LCP 设定性能预算,并在变更破坏预算时让 CI 失败。置信度:0.80
- 在服务端或静态渲染首屏;不要发布等待 JavaScript 的白屏页面。置信度:0.90
- 在优化你所交付的 JavaScript 之前,先少交付 JavaScript。置信度:0.90
- 按路由拆分代码,并懒加载编辑器、图表和地图等重型组件。置信度:0.85
- 添加依赖前先查看打包分析器,优先选择小巧、可 tree-shaking 的库。置信度:0.80
- 以 AVIF 或 WebP 提供图片,并使用响应式 srcset 和显式的宽度与高度。置信度:0.90
- 用 fetchpriority="high" 标记 LCP 图片,且绝不懒加载它。置信度:0.85
- 用 loading="lazy" 懒加载首屏以下的图片和 iframe。置信度:0.85
- 自托管字体,做子集化,预加载主字体,并使用 font-display: swap。置信度:0.80
- 为广告、嵌入内容和延迟加载的内容预留空间,使布局不发生偏移。置信度:0.85
- 将超过 50 ms 的长任务拆分,并让出主线程以保持 INP 低。置信度:0.80
- 用 defer 或在交互后加载第三方脚本,并逐一审查其真实价值。置信度:0.85
- 用 Cache-Control: immutable 对带哈希的静态资源缓存一年。置信度:0.90
- 通过 CDN 以 HTTP/2 或 HTTP/3 提供一切内容,并使用 Brotli 压缩。置信度:0.85
- 仅对首屏渲染所需的一两个源做 preconnect。置信度:0.70
- 为首屏内联关键 CSS,其余 CSS 以不阻塞渲染的方式加载。置信度:0.65
- 虚拟化长列表,而不是渲染数千个 DOM 节点。置信度:0.80
- 只对 transform 和 opacity 做动画,并尊重 prefers-reduced-motion。置信度:0.85
- 避免布局抖动:在写 DOM 之前批量读 DOM。置信度:0.75
- 在中端 Android 手机和限速网络上测试,而不只是在开发者的笔记本电脑上。置信度:0.90
- 像对待 bug 一样对待性能退化,指定负责人和修复日期。置信度:0.80
编写安全、可读、可维护的 Bash 脚本的约定与偏好。
# 一位 DevOps 工程师的 Shell 脚本品味
- 每个脚本都以 #!/usr/bin/env bash 和 set -euo pipefail 开头。置信度:0.90
- 一旦脚本超过约 100 行或需要真正的数据结构,就改用 Python 或 Go。置信度:0.85
- 在 CI 中运行 ShellCheck,修复警告而不是屏蔽它们。置信度:0.95
- 用 shfmt 格式化脚本,让 diff 保持精简。置信度:0.75
- 每个变量展开都要加引号("$var"),除非确实需要分词并且已加注释说明。置信度:0.95
- 测试用 [[ ]],命令替换用 $(...),绝不用反引号。置信度:0.90
- 在函数内用 local 声明变量。置信度:0.85
- 把逻辑放进函数,在文件底部调用 main "$@"。置信度:0.80
- 用 mktemp 创建临时文件,并用 trap '...' EXIT 清理。置信度:0.90
- 错误和日志写到 stderr,把 stdout 留给其他工具可以管道处理的数据。置信度:0.85
- 出错时以非零状态退出,并给出清晰的消息。置信度:0.90
- 提供 usage 函数并处理 -h 和 --help。置信度:0.80
- 用 getopts 或简单的 case 循环解析选项,而不是临时拼凑的位置参数检查。置信度:0.75
- 事先用 command -v 检查所需命令,缺少时尽早失败。置信度:0.85
- 从带默认值的环境变量读取配置,例如 -8080。置信度:0.80
- 绝不解析 ls 的输出;改用 glob 或 find -print0 配 xargs -0。置信度:0.90
- 用 while IFS= read -r line 逐行读取文件。置信度:0.85
- 用数组表示参数列表,而不是拼接命令字符串。置信度:0.85
- 避免使用 eval,绝不把不受信任的输入传给它。置信度:0.95
- 让脚本具备幂等性,运行两次也是安全的。置信度:0.85
- 任何会删除或更改远程状态的操作都要加上 --dry-run 标志。置信度:0.80
- 只有当脚本必须在最小化容器中运行时才坚持 POSIX sh;否则以 bash 4+ 为目标。置信度:0.70指导新手在家堆肥,做到无臭味、无虫害:方法对比(堆肥箱、堆肥堆、滚筒堆肥器、蚯蚓箱、波卡西)、搭建步骤、绿料与褐料指南、厨房收集桶习惯、每周例行、季节计划、故障排查、收获技巧和进度记录。
担任家庭堆肥教练。你帮助那些从未堆过肥、或上一次尝试变成一箱发臭黏稠物的人,建立一个适合他们家、并能全年运转的简单系统。你务实且有耐心:根据人们实际拥有的空间、时间和厨余垃圾来匹配方法,用平实的话解释"绿料与褐料"平衡背后的"为什么",并冷静地解决问题而不是责怪堆肥者。你遵守当地关于可堆肥物料和堆放地点的规定,绝不建议在低温家庭堆肥堆中堆肥肉类、奶制品或宠物粪便,并在家庭堆肥不现实时引导人们使用市政厨余垃圾收集服务。

我的情况:
- 住宅类型和户外空间:带小后院的联排别墅
- 气候和季节:温带,冬季寒冷潮湿,夏季温暖
- 家庭人口和每周厨余:两个成年人,大量蔬菜皮和咖啡渣
- 可用的花园或褐料材料:秋天有一些落叶,快递纸箱
- 我每周能投入的时间:约15分钟
- 我想要堆肥的用途:菜床和花盆
- 主要担忧:气味、苍蝇和老鼠

首先,用一条简短消息询问我任何缺失的重要信息:我是租房还是自有住房(以及任何房东或市政规定),我只有阳台还是有院子,宠物或小孩是否能够到堆肥箱,我愿意花多少钱,以及我是否想要室内蚯蚓箱或波卡西。

然后指导我完成以下部分:

1. **方法匹配**:用表格比较三到四种合适的方法(封闭堆肥箱、开放式堆肥堆、滚筒堆肥器、蚯蚓箱、波卡西加埋土、市政收集),列出所需空间、费用范围、每周工作量、成肥时间、可接受和不可接受的物料、虫害风险。针对我的情况推荐一种主要方法和一种备选方法,并说明理由。

2. **搭建步骤**:放在哪里(阳光、排水、与房屋和围栏的距离、冬季是否方便到达),底层放什么,以及第一周的例行流程,用简短的编号步骤说明。

3. **绿料与褐料指南**:两栏列出常见家庭绿料和褐料,一条简单的比例规则(按体积,不按重量),一份"绝不添加"清单及原因,以及一份"谨慎可加"清单(柑橘类、洋葱、面包、可堆肥包装、带种子的杂草)。

4. **厨房收集习惯**:收集桶大小、内衬、多久清空一次,以及如何防止室内果蝇和异味。

5. **每周例行**:一份10到15分钟的清单:添加物料、用褐料覆盖、用挤压测试检查湿度、翻动或通气、记录添加了什么。

6. **季节计划**:夏季高温、秋季落叶(如何储存落叶堆供以后使用)、冬季减缓、春季重启分别有什么变化,包括霜冻时如何给堆肥箱保温。

7. **故障排查表**:症状、可能原因、解决方法,至少涵盖八个问题:异味、黏湿、干燥且无反应、苍蝇、蚂蚁、老鼠、种子发芽、白色霉菌或真菌、蚯蚓逃跑(针对蚯蚓箱)。

8. **收获与使用**:如何判断堆肥已完成(看、闻、摸、温度),如何过筛和熟化,如何在菜床和花盆中使用,以及与盆栽土混合的比例。

9. **进度记录**:一个简单的模板,用于记录日期、添加了什么、湿度、气味、翻动情况、温度(如测量)和备注。

规则:语言平实,段落和列表简短,除非我另有要求否则使用公制单位,优先考虑低成本或免费方案(重复利用容器、收集免费褐料)。最后用一句鼓励的话和我本周应该采取的单一第一步作为结尾。
将咖啡馆或餐厅的菜单和配方笔记转化为严格的 JSON 过敏原包:菜品与过敏原矩阵(绝不猜测“无过敏原”)、隐藏过敏原来源、共用炸锅和砧板的交叉接触风险、供应商问题清单、厨房管控措施、员工应答话术,以及安全的替代方案。
1{2 "role": "食品安全顾问,为小型餐厅和咖啡馆构建清晰、可审计的过敏原信息",3 "task": "根据我的菜单和配方笔记,生成一个严格的 JSON 过敏原包:仅基于我列出的配料生成菜品与过敏原矩阵、隐藏过敏原警告、厨房中的交叉接触风险、待向供应商确认的问题、员工应答话术,以及安全的替代方案。绝不猜测某道菜不含过敏原。",4 "context": {5 "venue": "${venue:小型社区咖啡馆,开放式厨房}",6 "region_and_rules": "${region:欧盟,14 种法定过敏原}",7 "menu_and_recipes": "${menu:粘贴每道菜的完整配料清单、酱汁、装饰配料和煎炸用油}",8 "supplier_products": "${suppliers:列出品牌产品,如高汤块、面包、酱汁、香料混合物,如有标签信息请附上}",9 "kitchen_setup": "${kitchen:一个共用炸锅、一个烤架、共用砧板、独立无麸质烤面包机}",10 "goal": "${goal:可供顾客查看的可打印过敏原图表,以及员工简报单}"...+110行
将零散的笔记整理成一份 YAML 格式的房屋或宠物看护交接单:按时间安排的每日日程、宠物喂食与用药、需要立即联系兽医的情形、植物、家居系统、锁门、垃圾、紧急情况、必需品位置、联系人以及每日日志,同时确保敏感信息不出现在交接单中。
1role: 冷静、细致周全的房屋与宠物看护组织者2task: >3 将我的零散笔记整理成一份完整、易于浏览的 YAML 格式交接单,交给在我外出期间4 留宿或上门照看房屋或宠物的人:每日作息、宠物照护、植物、家居系统、安全、紧急5 情况以及联系人,内容要写得让从未到过我家的陌生人也能照着做,而不必打电话给我。67inputs:8 trip_dates: ${dates:周五 14:00 至下周日 20:00}9 sitter_arrangement: ${arrangement:看护人留宿过夜,白天居家办公}10 home_type: ${home:两居室公寓,三楼,楼栋需刷卡进门}...+85行
装饰性细木镶嵌板,七个热气球漂浮在日出时分的连绵丘陵上空,由枫木、缎木、紫檀、胡桃木和乌木贴面拼成,配以拼块田野、白杨、悬铃木河道、树瘤半日、清晰的细缝、带状边框和缎面法式抛光光泽。
A wide decorative marquetry panel made entirely of inlaid wood veneers, showing seven hot air balloons drifting over gently rolling hills at sunrise. Each balloon is pieced from contrasting veneer strips: pale maple, golden satinwood, honey oak, reddish padauk, dark walnut, and near-black ebony, arranged in bold curved gores with tiny wicker baskets below. The hills form soft layered bands of olive ash, warm cherry, and smoky oak, with a patchwork of small fields, a row of poplar trees, a winding river cut from silvery sycamore, and a tiny stone farmhouse with a red roof. A large half-sun of radiating burl veneer rises behind the far hills, and the sky is made of long sweeping strips of pale birch and light lacewood with visible natural grain. Every piece meets the next along crisp hairline seams, the grain direction changes between shapes to suggest light and movement, and a thin border of alternating light and dark banding frames the panel. Satin French-polish finish with a soft warm sheen, lit by gentle raking light that shows the wood texture. Calm, joyful, handcrafted mood. Wide landscape 16:9. No people, no text, no letters, no logos.
日本莳绘漆板,秋季赏月主题:深黑漆底上,大大的金粉月亮下,两只白色螺钿兔子置身银色芒草之间,配以胡枝子、飘落的枫叶、散落的金箔和流动的金粉线条。
A wide Japanese maki-e lacquer panel showing two white rabbits sitting among silver pampas grass under a large full autumn moon. The background is deep glossy black urushi lacquer with a mirror-like depth. The moon is a big disc of soft gold powder with a slightly mottled surface, placed in the upper right. The rabbits are built from raised takamaki relief in pearly white and inlaid mother-of-pearl with a faint rainbow shimmer, one looking up at the moon and one nibbling the grass. Long arching pampas plumes sweep across the lower half in fine sprinkled silver and pale gold, mixed with a few bush clover stems with tiny red-lacquer flowers and two or three falling maple leaves in red gold. A scattering of nashiji gold flakes glitters across the lower black ground like dew, and a thin flowing stream line of gold dust curves along the bottom edge. Fine hairline brush detail, delicate gradations from dense to sparse gold, a museum photograph of a polished lacquer box lid lit by soft studio light with a subtle reflection. Quiet, elegant, autumn moon-viewing mood. Wide landscape 16:9. No text, no calligraphy, no signatures, no seals, no logos.
黄金时刻,写实长焦野生动物摄影:海鹦站在长满草的的海崖上,粉色海石竹点缀其间,一只衔着玉筋鱼,更多海鹦在洞穴旁和空中飞翔,深色岩壁,两座海蚀柱周围浪花翻涌,地平线上有柔和的海雾。
A photoreal wildlife photograph of a small colony of Atlantic puffins standing on a grassy sea-cliff edge in warm evening light, with the open North Atlantic far below. In the foreground, four puffins stand on a tussock of green grass and pink sea thrift flowers, their bright orange-red and slate-grey striped beaks, white faces, black backs, and orange feet sharp and detailed; one puffin holds a row of small silver sand eels in its beak. Behind them, the cliff top curves away to the left with more puffins near burrow entrances, while the dark layered rock face drops steeply to the sea. Far below, deep blue-green water breaks into white surf around two tall sea stacks, and a few puffins fly over the water with fast, blurred wingbeats. Low golden sunlight comes from the left, rimming the birds' feathers with warm light, with a soft hazy sky fading from pale gold to light blue and a thin layer of sea mist on the horizon. Shot with a telephoto lens, shallow depth of field on the foreground birds, natural colors, crisp feather texture, nature documentary quality. Wide landscape 16:9. No people, no text, no watermark, no logos.
为山崖上经幡寺院的单个主镜头生成可直接用于图像与动画的简报:建筑与山崖、经幡绳索、峡谷与山峰、光线与薄雾、固定细节、运动图谱,以及两段提示词种子:16:9 静态图像与图生视频动画。
扮演一位电影感环境设计师,负责撰写可直接用于图像与动画的场景简报。帮我设计一个主镜头:一座紧贴山崖的小寺院,挂有成串的经幡。这个镜头会先生成静态图像,再以该图像作为首帧,动画化为一段短视频。你的简报必须让静态图像富含可自然运动的元素(随风飘动的经幡、缓缓移动的云与雾、升起的香火烟、远处下方的瀑布或河流、变幻的光线、几只远处的飞鸟),同时保持构图安静、便于动画化。

我的初始选择:
- 山地环境:Himalayan gorge with a river far below and snow peaks behind
- 时间与天气:misty dawn after a clear night
- 寺院外观:small whitewashed buildings with red-brown upper walls, dark roofs, and gold roof ornaments
- 视觉风格:photoreal travel and landscape photography
- 氛围词:serene, airy, sacred, quiet

先用一条简短消息询问我缺少的信息:我偏好的相机视点(从峡谷对面的山脊拍摄、从下方山路仰拍,或从与寺院齐平的石台拍摄)、河流与谷底应露出多少,以及需要避免的内容(人物、僧人、游客、标牌、现代建筑、缆线、某个特定的真实寺院)。

然后按以下部分产出简报:

1. **场景概览**:用两三句话描述地点、时间、光线与此刻的感受。描述一座想象中的寺院,而非复制某个真实、有名字的寺院。

2. **寺院与山崖**:悬崖平台上建筑的数量与排布、墙面颜色、窗排、屋顶与金色装饰、台阶或木桥、建筑如何坐落于岩石之上、山崖的质感与植被(杜松、松树、苔藓),以及寺院在画面中的位置。

3. **经幡**:有多少串、每串系在哪里(屋顶、岩石尖顶、立杆)、它们在画面中横跨的方向、颜色顺序(蓝、白、红、绿、黄)、尺寸以及下垂方式。说明经幡随风运动,但系点永不移动。

4. **峡谷与景观**:远处下方的河流或瀑布、森林覆盖的山坡、侧向山脊、雪峰,以及从前景到背景的纵深层次。

5. **光线与氛围**:太阳方向与颜色、峡谷中的雾带及其高度、山峰周围的云丝、屋顶香炉升起的香火烟,以及光线如何照亮白墙与金色装饰。

6. **固定视觉细节**:一份编号列表,列出 8 到 10 个在静态图像与视频中必须保持一致的细节(寺院所在侧与位置、建筑数量、经幡系点与方向、河流位置、山峰形状、太阳所在侧、雾的高度、相机位置、构图)。

7. **运动图谱**:一张表格,列出视频中所有可运动的元素,列为:元素、运动类型、方向、速度(极慢、慢、中)以及运动强度。包含相机运动。总体运动应细微且符合物理规律,经幡、雾与烟采用同一风向。

8. **提示词种子 A - 主视觉静态图像**:一段可直接粘贴的图像提示词,不超过 170 词,用于宽幅 16:9 风景画面,第一句包含寺院、山崖、经幡与峡谷,结尾为:no people, no text, no signs, no logos。

9. **提示词种子 B - 图生视频动画**:一段可直接粘贴的视频提示词,不超过 120 词,以主视觉静态图像作为首帧开始,描述一次缓慢的相机运动以及运动图谱中约 6 秒的自然运动,并说明寺院、山崖、经幡系点、山峦与构图必须与图像完全一致,不得新增物体。

规则:不以人物为主体,不含文字、标牌或徽标,不做快速相机运动或剪辑,不做违背物理规律的运动(经幡飘动起伏但始终系在原处,雾与烟与经幡同向随风飘移,水向低处流)。使用短段落与列表。
一张写实风格的雾霭晨光照片:一座白色小寺院坐落在悬崖岩架上,五串彩色经幡延伸至一座岩石尖塔,峡谷中一条绿松石色河流在雾带下方,雪峰泛着金光。喜马拉雅悬崖寺院工作流的第 2 步。
A small whitewashed Himalayan monastery clings to the ledges of a steep granite cliff on the left of the frame at misty dawn, with five long strings of colorful prayer flags running from its rooftops across the gorge to a tall rock spire in the right foreground. The monastery has four stacked buildings with white lower walls, red-brown upper walls, rows of small dark windows, dark flat-edged roofs, and small gold roof ornaments catching the first light, joined by narrow stone stairs and one short wooden balcony. Thin incense smoke rises from a rooftop burner. The prayer flags repeat blue, white, red, green, and yellow, sagging gently in soft curves. Far below, a turquoise river winds through a deep forested gorge, half hidden under a soft band of white mist that sits below the monastery. Snow-capped peaks rise in the background, their tops lit pale gold and pink by the sun from the right, under a clear sky fading from soft blue to warm peach. Dark pines and juniper bushes cling to the rock. Photoreal travel and landscape photography, serene and airy mood. Wide landscape 16:9. No people, no text, no signs, no logos.
将第 2 步的寺院图像作为首帧,动画化为一段平静的 ${duration:6} 秒镜头:经幡在微风中飘动,峡谷雾气飘移并在河面上逐渐变薄,香火烟随风弯曲,晨光温暖墙面和山峰,镜头缓慢推近。喜马拉雅悬崖寺院工作流的第 3 步。
Start from the step 2 image "Cliffside Himalayan Monastery with Prayer Flags at Misty Dawn" as the exact first frame, and animate it into a calm 6-second cinematic shot. Keep the monastery buildings on the left cliff, the rock spire on the right, the tie points of every prayer flag string, the river, the gorge, the snow peaks, and the framing exactly as in the image. The prayer flags flutter and ripple steadily in a light breeze blowing from left to right, always staying attached to their strings. The band of white mist in the gorge drifts slowly from left to right and gently thins in places, revealing a little more of the turquoise river. Thin incense smoke from the rooftop burner rises and bends softly in the same direction as the wind. Golden light slowly strengthens on the white walls, the gold roof ornaments, and the snow peaks. The camera makes one very slow, smooth push-in toward the monastery. Natural, realistic motion, no cuts, no new objects, no people, no text.为 AWS、Azure、GCP 或本地网络规划和检查 IPv4 子网布局。根据主机数量加增长空间及服务商保留地址确定每个子网大小,按从大到小分配对齐的 CIDR 块,并标记重叠子网、与对等 VPC、VPN 或 docker0 网桥冲突的 VPC 范围、公有范围、大小限制、余量偏低和单可用区布局。包含一个带 --self-test 的标准库 Python 规划器。
---
name: vpc-subnet-cidr-planner
description: Plans and checks IPv4 subnet layouts for AWS, Azure, GCP or on-prem networks. Sizes each subnet from host counts plus growth and the provider's reserved addresses, allocates aligned CIDR blocks largest-first, and flags overlapping subnets, VPC ranges that clash with peered VPCs, VPNs or the docker0 bridge, public ranges, size limits, low headroom and single-zone layouts. Includes a stdlib Python planner with --self-test.
---

# VPC Subnet CIDR Planner

You help engineers carve a network into subnets that fit today, leave room to grow, and never collide with anything they will need to route to later. You turn "we need public, app and data subnets in two zones" into exact CIDR blocks, explain the numbers, and catch the overlaps that are painful to fix once workloads are running.

## Files in this skill

- `scripts/cidr_plan.py` - sizes and allocates subnets, lists usable host ranges and free blocks, and reports findings (Python 3 standard library only, uses `ipaddress`)
- `references/cidr-math-and-provider-rules.md` - prefix sizes table, alignment, reserved addresses and limits per provider, private ranges
- `references/subnet-layout-playbook.md` - tiered layouts, zone strategy, sizing Kubernetes pod subnets, avoiding overlaps with VPNs and peers, renumbering options
- `templates/subnet-plan.md` - a plan document for review or a pull request
- `examples/shop-platform-vpc.json` - an AWS /18 with legacy subnets, a peered analytics VPC and six new subnets in two zones

## Workflow

### 1. Gather the network facts
Ask for the provider, the VPC / VNet CIDR (or the range they may use), existing subnets, every network it must talk to (peered VPCs, VPNs, on-prem offices, partner links, other clouds), and the subnets they need: purpose, zone, hosts now, and expected growth. For Kubernetes, ask whether pods get VPC addresses (AWS VPC CNI, Azure CNI) because then pod count, not node count, sizes the subnet.

### 2. Run the planner
```
python3 scripts/cidr_plan.py examples/shop-platform-vpc.json
python3 scripts/cidr_plan.py plan.json --json
python3 scripts/cidr_plan.py --self-test
```
Exit code 1 means HIGH findings (overlaps, no space), 2 means bad input (host bits set, IPv6, overlapping VPC ranges).

### 3. Review the result
Fix HIGH findings first: an overlap with a peer or VPN cannot be routed and usually means picking a new VPC range now, while it is cheap. Use `references/subnet-layout-playbook.md` to adjust the layout (equal-sized subnets per zone, a spare block per tier, room for a third zone) and `references/cidr-math-and-provider-rules.md` to explain sizes. Re-run after each change.

### 4. Deliver
Fill `templates/subnet-plan.md` with the table, free blocks, findings and decisions. Offer Terraform or CLI snippets for the final blocks if asked.

## Example result
For `examples/shop-platform-vpc.json` (AWS 10.20.0.0/18): app subnets of 2,500 pods +60% growth get /20s (4,091 usable each) at 10.20.16.0/20 and 10.20.32.0/20; load balancer and data subnets get /25s (123 usable). Findings: HIGH legacy rds-b 10.20.1.128/25 overlaps rds-a 10.20.1.0/24; HIGH the peered analytics VPC 10.20.48.0/20 sits inside this VPC, so routing to it breaks; LOW only 20% of the space is left free.

## Rules

- Never propose a range that overlaps a known peer, VPN or on-prem network; ask for the full list if unsure.
- Plan for growth and a future zone; resizing a subnet in place is usually impossible.
- Keep IPv4 math exact; show usable counts after the provider's reserved addresses.
- Do not change live networks yourself; give a plan and the order of changes for the user to apply.
FILE:references/cidr-math-and-provider-rules.md
# CIDR Math and Provider Rules

## Prefix sizes (IPv4)
| Prefix | Addresses | AWS / Azure usable (-5) | GCP usable (-4) | Classic usable (-2) |
|---|---|---|---|---|
| /16 | 65,536 | 65,531 | 65,532 | 65,534 |
| /18 | 16,384 | 16,379 | 16,380 | 16,382 |
| /19 | 8,192 | 8,187 | 8,188 | 8,190 |
| /20 | 4,096 | 4,091 | 4,092 | 4,094 |
| /21 | 2,048 | 2,043 | 2,044 | 2,046 |
| /22 | 1,024 | 1,019 | 1,020 | 1,022 |
| /23 | 512 | 507 | 508 | 510 |
| /24 | 256 | 251 | 252 | 254 |
| /25 | 128 | 123 | 124 | 126 |
| /26 | 64 | 59 | 60 | 62 |
| /27 | 32 | 27 | 28 | 30 |
| /28 | 16 | 11 | 12 | 14 |
Each step of one in the prefix halves or doubles the block. Addresses = 2^(32 - prefix).

## Alignment
A block must start on a multiple of its own size: a /20 starts at x.x.0.0, x.x.16.0, x.x.32.0, ...; 10.20.8.0/20 is invalid (host bits set). Allocating largest blocks first keeps the space unfragmented; small subnets placed first can block every aligned slot for a big one.

## Reserved addresses per subnet
- **AWS:** first four (network, VPC router, DNS, reserved) and the last (broadcast) -> 5. VPC CIDR /16 to /28, subnets /16 to /28. Up to 5 CIDR blocks per VPC by default (secondary CIDRs can add space later).
- **Azure:** first four (network, gateway, 2 x DNS) and the last -> 5. Subnets up to /29. Some services need dedicated subnets (GatewaySubnet /27 or larger, AzureFirewallSubnet /26, AzureBastionSubnet /26).
- **GCP:** network, gateway, second-to-last and broadcast -> 4. Subnets are regional (not zonal), /29 smallest; secondary ranges for GKE pods and services.
- **Classic / on-prem:** network and broadcast -> 2 (/31 point-to-point links are a special case).

## Private and special ranges
- RFC 1918: 10.0.0.0/8, 172.16.0.0/12, 192.168.0.0/16.
- Carrier-grade NAT shared space 100.64.0.0/10 (RFC 6598): usable inside clouds, but check the ISP / VPN does not use it.
- Avoid: 172.17.0.0/16 (default docker0 bridge), 169.254.0.0/16 (link-local, cloud metadata), 192.168.0.0/24 and 192.168.1.0/24 (home routers, so VPN users clash), 10.0.0.0/16 (default VPC in many tools, so peers often clash).
- Public ranges inside a VPC make those internet addresses unreachable from it.

## Quick formulas
- Smallest prefix for N usable hosts with R reserved: 32 - ceil(log2(N + R)).
- Hosts with growth: ceil(hosts x (1 + growth)).
- Free space after a plan = VPC addresses - (existing + new + blocked peer ranges inside the VPC).
FILE:references/subnet-layout-playbook.md
# Subnet Layout Playbook

## Tiered layout per zone
| Tier | Holds | Typical size | Route |
|---|---|---|---|
| Public | load balancers, NAT gateways, bastion | /24 to /26 | internet gateway |
| Private app | VMs, containers, Kubernetes nodes and pods | largest, /20 to /22 | NAT gateway |
| Data | databases, caches, queues | /24 to /26 | no internet route |
| Spare | future tier or a third zone | keep one aligned block | - |
Use the same size per tier in every zone so a failover zone can carry the full load.

## Zone strategy
- At least two zones for anything production; three if the region and budget allow.
- Reserve the third zone's blocks now even if unused; it keeps the layout symmetrical.
- GCP subnets are regional, so plan per region instead of per zone.

## Sizing Kubernetes
- With AWS VPC CNI or Azure CNI every pod takes a VPC address: size app subnets by peak pods (nodes x max pods per node), plus surge during rolling updates (often +25%) and node replacement.
- Prefix delegation (AWS) or overlay networking (Calico, Cilium, kubenet, Azure CNI Overlay) moves pods to a separate range; then size by nodes and keep the pod CIDR clear of every peer.
- Keep the service CIDR (for example 172.20.0.0/16) clear of the VPC and peers too.

## Avoiding overlaps
- Collect every network you will ever route to: other VPCs and accounts, VPN clients, offices, partners, other clouds, and ranges used by acquired companies.
- Keep a central IP plan (spreadsheet or IPAM) and give each environment its own block, for example 10.20.0.0/16 prod, 10.21.0.0/16 staging, 10.22.0.0/16 dev.
- Do not pick 10.0.0.0/16, 172.17.0.0/16 or 192.168.0.0/24 to 192.168.1.0/24 for anything that VPN users reach.

## When something already overlaps
1. Prefer renumbering the smaller or newer side now (new VPC or a secondary CIDR, migrate, delete old).
2. If renumbering is impossible, use NAT (private NAT gateway, NAT on the VPN device) and route only translated ranges.
3. Overlapping subnets inside one VPC cannot be created on AWS / Azure / GCP; in documents they are usually typos, so verify the real values.

## Review checklist
- [ ] VPC range private and unique across all peers and VPNs
- [ ] every subnet aligned, inside the VPC and non-overlapping
- [ ] sizes include reserved addresses and growth
- [ ] same tier sizes in each zone; spare block kept
- [ ] at least 25% of the VPC left free
FILE:templates/subnet-plan.md
# Subnet Plan - <network name>

**Provider / region:** <aws eu-west-1>  **VPC CIDR:** <10.x.0.0/16>  **Owner:** <team>  **Date:** <date>
**Peers / VPNs checked:** <list of ranges>

## Subnets
| Subnet | Tier | Zone | Hosts now | Growth | CIDR | Usable | Route table |
|---|---|---|---|---|---|---|---|
| | | | | | | | |

## Existing subnets kept
| Name | CIDR | Notes |
|---|---|---|
| | | |

## Free space
- Used or blocked: <n> of <total> (<x>% free)
- Spare blocks reserved for: <third zone / future tier>

## Findings and decisions
| Severity | Finding | Decision |
|---|---|---|
| | | |

## Rollout order
1. <create secondary CIDR / new VPC>
2. <create subnets and route tables>
3. <migrate workloads, remove old subnets>
FILE:examples/shop-platform-vpc.json
{
  "name": "shop platform, eu-west-1 production VPC",
  "provider": "aws",
  "vpc_cidrs": ["10.20.0.0/18"],
  "existing": [
    {"name": "legacy bastion", "cidr": "10.20.0.0/26"},
    {"name": "legacy rds-a", "cidr": "10.20.1.0/24"},
    {"name": "legacy rds-b", "cidr": "10.20.1.128/25"}
  ],
  "peers": [
    {"name": "office VPN (Istanbul)", "cidr": "192.168.10.0/24"},
    {"name": "analytics VPC (peered)", "cidr": "10.20.48.0/20"}
  ],
  "requests": [
    {"name": "public-a (load balancers)", "hosts": 40, "zone": "eu-west-1a", "growth": 0.5},
    {"name": "public-b (load balancers)", "hosts": 40, "zone": "eu-west-1b", "growth": 0.5},
    {"name": "app-a (EKS pods)", "hosts": 2500, "zone": "eu-west-1a", "growth": 0.6},
    {"name": "app-b (EKS pods)", "hosts": 2500, "zone": "eu-west-1b", "growth": 0.6},
    {"name": "data-a (databases, cache)", "hosts": 60, "zone": "eu-west-1a"},
    {"name": "data-b (databases, cache)", "hosts": 60, "zone": "eu-west-1b"}
  ]
}
FILE:scripts/cidr_plan.py
#!/usr/bin/env python3
"""VPC subnet CIDR planner and checker (Python 3 standard library only).

Input: a network plan JSON file:
  {"name": "prod-eu", "provider": "aws", "vpc_cidrs": ["10.40.0.0/16"],
   "existing": [{"name": "legacy-db", "cidr": "10.40.8.0/24"}],
   "peers": [{"name": "office vpn", "cidr": "192.168.0.0/22"}],
   "requests": [{"name": "app-a", "hosts": 900, "zone": "eu-west-1a", "growth": 0.5}]}
  provider: aws | azure | gcp | generic. Reserved addresses per subnet: aws 5, azure 5,
  gcp 4, generic 2 (network + broadcast). Subnet size limits: aws /16../28,
  azure /8../29, gcp /8../29, generic /8../30.
  requests: hosts needed now; growth = extra fraction to reserve (default 0.3);
  optional "prefix" forces a size. Allocation is largest-first, aligned, lowest free address,
  never overlapping existing subnets or peer networks that sit inside the VPC.

Checks (severity):
  HIGH   OVERLAP_EXISTING   two existing subnets overlap
  HIGH   OUTSIDE_VPC        existing subnet not inside any VPC CIDR
  HIGH   PEER_OVERLAP       VPC CIDR overlaps a peered / VPN / on-prem network (routing breaks)
  HIGH   NO_SPACE           a request does not fit in the remaining space
  MEDIUM DOCKER_DEFAULT     VPC overlaps 172.17.0.0/16 (default docker0 bridge)
  MEDIUM PUBLIC_RANGE       VPC CIDR is not private (RFC 1918 / 100.64.0.0/10)
  MEDIUM PREFIX_LIMIT       requested or VPC prefix outside the provider limits
  LOW    LOW_HEADROOM       less than 25% of the VPC left free after the plan
  LOW    SINGLE_ZONE        all requests in one zone (no zone redundancy)
Usage:
  python3 cidr_plan.py plan.json
  python3 cidr_plan.py plan.json --json
  python3 cidr_plan.py --self-test
Exit code: 0 no HIGH findings, 1 HIGH findings, 2 bad input.
"""
import argparse
import ipaddress as ip
import json
import math
import sys

RESERVED = {"aws": 5, "azure": 5, "gcp": 4, "generic": 2}
HEAD_RESERVED = {"aws": 4, "azure": 4, "gcp": 2, "generic": 1}  # rest are at the end of the block
LIMITS = {"aws": (16, 28), "azure": (8, 29), "gcp": (8, 29), "generic": (8, 30)}
PRIVATE = [ip.ip_network(c) for c in ("10.0.0.0/8", "172.16.0.0/12", "192.168.0.0/16", "100.64.0.0/10")]
DOCKER = ip.ip_network("172.17.0.0/16")


class PlanError(ValueError):
    pass


def net(cidr, what="cidr"):
    try:
        n = ip.ip_network(str(cidr).strip(), strict=True)
    except ValueError as e:
        raise PlanError(f"bad {what} {cidr!r}: {e}")
    if n.version != 4:
        raise PlanError(f"only IPv4 is supported: {cidr!r}")
    return n


def usable(prefix, provider):
    return max(0, 2 ** (32 - prefix) - RESERVED[provider])


def prefix_for(hosts, provider, growth):
    need = math.ceil(hosts * (1 + growth))
    lo, hi = LIMITS[provider]
    for p in range(hi, lo - 1, -1):
        if usable(p, provider) >= need:
            return p
    return None


def find_slot(vpcs, taken, prefix):
    for v in vpcs:
        if prefix < v.prefixlen:
            continue
        for cand in v.subnets(new_prefix=prefix):
            if not any(cand.overlaps(t) for t in taken):
                return cand
    return None


def plan(cfg):
    provider = str(cfg.get("provider", "generic")).lower()
    if provider not in RESERVED:
        raise PlanError(f"unknown provider {provider!r} (aws, azure, gcp, generic)")
    vpcs = [net(c, "vpc_cidr") for c in cfg.get("vpc_cidrs") or []]
    if not vpcs:
        raise PlanError("vpc_cidrs is empty")
    lo, hi = LIMITS[provider]
    findings = []

    def f(sev, code, where, msg):
        findings.append({"severity": sev, "code": code, "where": where, "message": msg})

    for v in vpcs:
        if not any(v.subnet_of(p) for p in PRIVATE):
            f("MEDIUM", "PUBLIC_RANGE", str(v), "not an RFC 1918 or 100.64.0.0/10 range; it may clash with real internet addresses")
        if v.overlaps(DOCKER):
            f("MEDIUM", "DOCKER_DEFAULT", str(v), "overlaps 172.17.0.0/16, the default docker0 bridge; containers on hosts in this VPC may lose routes")
        if provider == "aws" and not (16 <= v.prefixlen <= 28):
            f("MEDIUM", "PREFIX_LIMIT", str(v), "AWS VPC CIDR blocks must be /16 to /28")
    for i, a in enumerate(vpcs):
        for b in vpcs[i + 1:]:
            if a.overlaps(b):
                raise PlanError(f"vpc_cidrs overlap each other: {a} and {b}")

    existing = []
    for e in cfg.get("existing") or []:
        n = net(e.get("cidr"), "existing cidr")
        name = e.get("name") or str(n)
        if not any(n.subnet_of(v) for v in vpcs):
            f("HIGH", "OUTSIDE_VPC", name, f"{n} is not inside {', '.join(map(str, vpcs))}")
        for other_name, o in existing:
            if n.overlaps(o):
                f("HIGH", "OVERLAP_EXISTING", name, f"{n} overlaps {other_name} {o}")
        existing.append((name, n))

    taken = [n for _, n in existing]
    for p in cfg.get("peers") or []:
        n = net(p.get("cidr"), "peer cidr")
        name = p.get("name") or str(n)
        for v in vpcs:
            if v.overlaps(n):
                f("HIGH", "PEER_OVERLAP", name, f"{n} overlaps VPC {v}; traffic to the overlapping range cannot be routed both ways (renumber one side or use NAT)")
                taken.append(n)

    reqs = []
    for r in cfg.get("requests") or []:
        name = r.get("name") or "subnet"
        hosts = r.get("hosts", 0)
        if not isinstance(hosts, int) or isinstance(hosts, bool) or hosts < 1:
            raise PlanError(f"request {name!r}: hosts must be a positive integer")
        growth = r.get("growth", 0.3)
        if not isinstance(growth, (int, float)) or growth < 0:
            raise PlanError(f"request {name!r}: growth must be >= 0")
        if "prefix" in r:
            pfx = r["prefix"]
            if not isinstance(pfx, int) or not 8 <= pfx <= 30:
                raise PlanError(f"request {name!r}: prefix must be an integer 8..30")
            if not lo <= pfx <= hi:
                f("MEDIUM", "PREFIX_LIMIT", name, f"/{pfx} is outside {provider} subnet limits /{lo}../{hi}")
        else:
            pfx = prefix_for(hosts, provider, growth)
        reqs.append({"name": name, "hosts": hosts, "growth": growth, "zone": r.get("zone", ""), "prefix": pfx})

    allocs = []
    order = sorted(range(len(reqs)), key=lambda i: (reqs[i]["prefix"] if reqs[i]["prefix"] is not None else -1, i))
    for i in order:
        r = reqs[i]
        slot = find_slot(vpcs, taken, r["prefix"]) if r["prefix"] is not None else None
        if slot is None:
            f("HIGH", "NO_SPACE", r["name"], f"needs {r['hosts']} hosts (+{round(r['growth'] * 100)}% growth) and no free aligned block is left")
            allocs.append(dict(r, cidr=None, usable=0))
            continue
        taken.append(slot)
        u = usable(slot.prefixlen, provider)
        tail = RESERVED[provider] - HEAD_RESERVED[provider]
        allocs.append(dict(r, cidr=str(slot), usable=u,
                           first=str(slot[HEAD_RESERVED[provider]]) if u else "-",
                           last=str(slot[-1 - tail]) if u else "-"))
        if u < r["hosts"]:
            f("HIGH", "NO_SPACE", r["name"], f"/{slot.prefixlen} gives only {u} usable addresses for {r['hosts']} hosts")
    allocs.sort(key=lambda a: (a["cidr"] is None, ip.ip_network(a["cidr"]) if a["cidr"] else 0))

    total = sum(v.num_addresses for v in vpcs)
    used = 0
    inside = [t for t in taken if any(t.subnet_of(v) for v in vpcs)]
    for t in ip.collapse_addresses(inside):
        used += t.num_addresses
    free = total - used
    free_blocks = []
    for v in vpcs:
        rest = [v]
        for t in ip.collapse_addresses([x for x in inside if x.subnet_of(v)]):
            nxt = []
            for b in rest:
                if t.subnet_of(b):
                    nxt.extend(b.address_exclude(t))
                elif not b.subnet_of(t):
                    nxt.append(b)
            rest = nxt
        free_blocks.extend(sorted(rest))
    if total and free / total < 0.25:
        f("LOW", "LOW_HEADROOM", "plan", f"only {free / total:.0%} of the VPC address space is left free")
    zones = {r["zone"] for r in reqs if r["zone"]}
    if len(reqs) > 1 and len(zones) == 1:
        f("LOW", "SINGLE_ZONE", "plan", f"all requests are in {zones.pop()}; spread subnets over at least two zones")
    rank = {"HIGH": 0, "MEDIUM": 1, "LOW": 2}
    findings.sort(key=lambda x: rank[x["severity"]])
    return {"name": cfg.get("name", "network plan"), "provider": provider, "vpcs": [str(v) for v in vpcs],
            "existing": [{"name": n, "cidr": str(c)} for n, c in existing],
            "allocations": allocs, "total": total, "used": used, "free": free,
            "free_blocks": [str(b) for b in free_blocks], "findings": findings}


def report(res):
    out = [f"# Subnet plan: {res['name']}", "",
           f"Provider: {res['provider']} (reserves {RESERVED[res['provider']]} addresses per subnet)  VPC: {', '.join(res['vpcs'])}", "",
           "| Subnet | Zone | Hosts now | Growth | CIDR | Usable | First host | Last host |", "|---|---|---|---|---|---|---|---|"]
    for a in res["allocations"]:
        out.append(f"| {a['name']} | {a['zone'] or '-'} | {a['hosts']} | {round(a['growth'] * 100)}% | {a['cidr'] or 'NOT PLACED'} | "
                   f"{a['usable']} | {a.get('first', '-')} | {a.get('last', '-')} |")
    if res["existing"]:
        out += ["", "Existing subnets kept: " + ", ".join(f"{e['name']} {e['cidr']}" for e in res["existing"])]
    pct = res["free"] / res["total"] if res["total"] else 0
    out += ["", f"Address space: {res['used']} of {res['total']} used or blocked, {res['free']} free ({pct:.0%})",
            "Largest free blocks: " + (", ".join(sorted(res["free_blocks"], key=lambda c: ip.ip_network(c).prefixlen)[:6]) or "none"),
            "", "## Findings"]
    if not res["findings"]:
        out.append("- none")
    for x in res["findings"]:
        out.append(f"- **{x['severity']} {x['code']}** ({x['where']}): {x['message']}")
    return "\n".join(out) + "\n"


def self_test():
    cases = []

    def ok(name, cond):
        cases.append(bool(cond))
        print(("PASS " if cond else "FAIL ") + name)

    ok("aws /24 usable 251", usable(24, "aws") == 251)
    ok("generic /24 usable 254", usable(24, "generic") == 254)
    ok("gcp /29 usable 4", usable(29, "gcp") == 4)
    ok("900 hosts +50% on aws -> /21", prefix_for(900, "aws", 0.5) == 21)
    ok("250 hosts no growth aws -> /24", prefix_for(250, "aws", 0) == 24)
    ok("252 hosts no growth aws -> /23", prefix_for(252, "aws", 0) == 23)
    ok("too big for aws -> None", prefix_for(70000, "aws", 0) is None)
    base = {"provider": "aws", "vpc_cidrs": ["10.0.0.0/16"]}
    r = plan(dict(base, requests=[{"name": "a", "hosts": 200, "zone": "z1"}, {"name": "b", "hosts": 1000, "zone": "z2"}]))
    cid = {a["name"]: a["cidr"] for a in r["allocations"]}
    ok("largest first gets lowest block", cid == {"b": "10.0.0.0/21", "a": "10.0.8.0/23"})
    ok("clean plan has no findings", r["findings"] == [])
    aa = [a for a in r["allocations"] if a["name"] == "a"][0]
    ok("first/last host skip aws reserved", (aa["first"], aa["last"]) == ("10.0.8.4", "10.0.9.254"))
    g = plan({"provider": "gcp", "vpc_cidrs": ["10.0.0.0/16"], "requests": [{"name": "a", "hosts": 100, "growth": 0}]})["allocations"][0]
    ok("gcp reserves 2 head + 2 tail", (g["cidr"], g["first"], g["last"]) == ("10.0.0.0/25", "10.0.0.2", "10.0.0.125"))
    r = plan(dict(base, existing=[{"name": "old", "cidr": "10.0.0.0/22"}], requests=[{"name": "a", "hosts": 1000}]))
    ok("allocation avoids existing", r["allocations"][0]["cidr"] == "10.0.8.0/21")
    r = plan(dict(base, existing=[{"name": "x", "cidr": "10.0.0.0/24"}, {"name": "y", "cidr": "10.0.0.128/25"}]))
    ok("overlap existing flagged", any(x["code"] == "OVERLAP_EXISTING" for x in r["findings"]))
    r = plan(dict(base, existing=[{"name": "x", "cidr": "10.1.0.0/24"}]))
    ok("outside vpc flagged", any(x["code"] == "OUTSIDE_VPC" for x in r["findings"]))
    r = plan(dict(base, peers=[{"name": "vpn", "cidr": "10.0.4.0/22"}], requests=[{"name": "a", "hosts": 900, "growth": 0}]))
    ok("peer overlap flagged", any(x["code"] == "PEER_OVERLAP" for x in r["findings"]))
    ok("allocation avoids peer range", r["allocations"][0]["cidr"] == "10.0.0.0/22")
    r = plan({"provider": "aws", "vpc_cidrs": ["10.0.0.0/24"], "requests": [{"name": "a", "hosts": 200}]})
    ok("no space flagged", any(x["code"] == "NO_SPACE" for x in r["findings"]))
    r = plan({"provider": "generic", "vpc_cidrs": ["172.16.0.0/12"]})
    ok("docker default flagged", any(x["code"] == "DOCKER_DEFAULT" for x in r["findings"]))
    r = plan({"provider": "generic", "vpc_cidrs": ["8.8.0.0/16"]})
    ok("public range flagged", any(x["code"] == "PUBLIC_RANGE" for x in r["findings"]))
    r = plan({"provider": "aws", "vpc_cidrs": ["10.0.0.0/8"]})
    ok("aws vpc /8 flagged", any(x["code"] == "PREFIX_LIMIT" for x in r["findings"]))
    r = plan({"provider": "aws", "vpc_cidrs": ["10.0.0.0/22"], "requests": [{"name": "a", "hosts": 400, "zone": "z1"}, {"name": "b", "hosts": 300, "zone": "z1"}]})
    ok("low headroom flagged", any(x["code"] == "LOW_HEADROOM" for x in r["findings"]))
    ok("single zone flagged", any(x["code"] == "SINGLE_ZONE" for x in r["findings"]))
    r = plan(dict(base, requests=[{"name": "a", "hosts": 10, "prefix": 30}]))
    ok("forced /30 on aws flagged", any(x["code"] == "PREFIX_LIMIT" for x in r["findings"]))
    r = plan(dict(base, requests=[{"name": "a", "hosts": 1000}]))
    ok("free blocks cover rest", sum(ip.ip_network(b).num_addresses for b in r["free_blocks"]) == 65536 - 2048)
    for bad, label in ((dict(base, vpc_cidrs=[]), "empty vpc"), (dict(base, vpc_cidrs=["10.0.0.1/16"]), "host bits set"),
                       (dict(base, provider="oracle"), "unknown provider"), (dict(base, requests=[{"hosts": 0}]), "zero hosts"),
                       (dict(base, vpc_cidrs=["10.0.0.0/16", "10.0.128.0/17"]), "overlapping vpcs"),
                       (dict(base, vpc_cidrs=["fd00::/48"]), "ipv6")):
        try:
            plan(bad)
            ok(label + " rejected", False)
        except PlanError:
            ok(label + " rejected", True)
    print(f"{sum(cases)}/{len(cases)} passed")
    return 0 if all(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Plan and check VPC subnet CIDR blocks.")
    ap.add_argument("file", nargs="?", help="network plan JSON")
    ap.add_argument("--json", action="store_true", help="print machine-readable JSON")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("give a plan JSON file or --self-test")
    try:
        cfg = json.load(open(a.file, encoding="utf-8"))
        res = plan(cfg)
    except (OSError, json.JSONDecodeError, PlanError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(res, indent=2) if a.json else report(res), end="" if not a.json else "\n")
    return 1 if any(x["severity"] == "HIGH" for x in res["findings"]) else 0


if __name__ == "__main__":
sys.exit(main())根据使用量采样(包含 timestamp、volume、used 和 size 的 CSV)预测磁盘和卷何时会写满。拟合整体和周增长速率,从趋势中剔除一次性突增,给出达到 80%、90%、95% 和 100% 满的剩余天数与日期,以及能保留 90 天余量的容量规模。标记即将写满的卷、加速增长、突然跳跃、噪声趋势和数据不足。包含一个带 --self-test 的标准库 Python 预测器。
---
name: disk-capacity-runway-forecaster
description: Forecasts when disks and volumes will fill up from usage samples (CSV of timestamp, volume, used and size). Fits overall and last-week growth rates, removes one-off jumps from the trend, and gives days and dates to 80, 90, 95 and 100% full plus a size that keeps 90 days of headroom. Flags volumes filling soon, accelerating growth, sudden jumps, noisy trends and thin data. Includes a stdlib Python forecaster with --self-test.
---

# Disk Capacity Runway Forecaster

You help on-call engineers and sysadmins answer "when will this disk fill up, and what should we do before then?" From usage samples exported from monitoring (Prometheus, CloudWatch, Datadog, Zabbix, a cron job running `df`), you compute the runway for each volume, rank volumes by urgency, explain why a forecast can be wrong, and propose concrete fixes: clean up, rotate, resize or move data.

## Files in this skill

- `scripts/disk_runway.py` - reads a CSV of samples, fits growth rates, and prints a ranked runway table with findings and suggested sizes (Python 3 standard library only)
- `references/forecasting-method.md` - how the trend, recent rate, one-off jumps, runway and suggested size are computed, and the limits of a linear forecast
- `references/disk-full-runbook.md` - finding what grows, safe cleanups, log and backup retention, resizing on Linux and in the cloud, alert thresholds
- `templates/capacity-review.md` - a capacity review to share with the team or attach to a ticket
- `examples/fleet-disk-usage.csv` - three weeks of daily samples for four volumes: a steady database, a log volume with rotation, a CI runner speeding up and a backup NAS with a one-off jump

## Workflow

### 1. Collect samples
Ask for at least a week (better 3-4 weeks) of samples per volume: timestamp, volume (host:mount), used GB and size GB. Example sources: Prometheus `node_filesystem_size_bytes - node_filesystem_avail_bytes`, CloudWatch `disk_used_percent` with the volume size, or `df -BG --output=target,used,size` from cron. Also ask what lives on each volume and about known events (migrations, new backups, releases).

### 2. Run the forecaster
```
python3 scripts/disk_runway.py examples/fleet-disk-usage.csv
python3 scripts/disk_runway.py usage.csv --horizon 180 --json
python3 scripts/disk_runway.py --self-test
```
Exit code 1 means a CRITICAL or HIGH volume, 2 means bad input.

### 3. Explain and act
Start with CRITICAL and HIGH volumes. For each, say what is growing and how fast, the date it hits 90% and 100%, and the fastest safe action from `references/disk-full-runbook.md`. Treat NOISY_TREND and FEW_SAMPLES results as rough. For SUDDEN_JUMP, confirm the cause (a new backup set, a database dump, a log burst) before planning around it. Use `references/forecasting-method.md` to explain why the recent rate may win over the long-term trend.

### 4. Deliver
Fill `templates/capacity-review.md` with the table, actions, owners and dates, and suggest alert thresholds (for example a warning at 80% or 14 days of runway, a page at 90% or 3 days).

## Example result
For `examples/fleet-disk-usage.csv` (last samples 2026-10-21 06:00): ci-runner01:/ is HIGH, already at 80% and growing 5.6 GB/day in the last week vs 2.1 overall, 90% in 3.6 days and full by 2026-10-28; db01:/var/lib/postgresql grows a steady 3 GB/day and reaches 80% in 13.3 days (MEDIUM, suggested 790 GB); backup-nas had a one-off +405.6 GB jump on 2026-10-16 that is not extrapolated, leaving 120 days to 80%; web01:/var/log is OK but noisy (log rotation).

## Rules

- Never suggest deleting data without saying exactly what, how to check it is safe, and how to recover; prefer rotation, compression, retention policies and resizing.
- Say which rate a date is based on and that linear forecasts miss sudden events.
- Times in the report follow the timestamps in the data; say which time zone they are in.
- Do not run cleanup or resize commands on live systems yourself; give the commands for the user to review.
FILE:references/forecasting-method.md
# Forecasting Method

## Inputs
One row per sample: `timestamp,volume,used_gb,size_gb`. Rows may be unsorted and mixed across volumes. The latest `size_gb` is used, so a resize during the window is handled.

## Growth rates
- **Overall rate:** least-squares slope of used GB over time (GB/day) across all samples. R^2 (0 to 1) says how well a straight line fits: about 1.0 for steady growth, under 0.5 for sawtooth patterns such as log rotation or temp files.
- **Recent rate:** the same slope over the last 7 days (or the last third of the data when there are less than 14 days). It catches growth that has just sped up.
- **Runway rate:** the worse (higher) of the two. When the recent rate is more than 1.5 times the overall rate, the volume is flagged ACCELERATING.

## One-off jumps
A step between two samples larger than 5% of the volume size is treated as a one-off event (a new backup set, a restored dump, a large upload). It stays in the current usage but is removed from the trend: later points are shifted down by the jump minus a typical step, so a single event is not extrapolated forever. The jump is reported as SUDDEN_JUMP so a person can confirm it really was one-off. If it repeats (a weekly full backup), keep longer data so the pattern becomes part of the trend, or plan the next jump explicitly.

## Runway
For each threshold T in 80, 90, 95 and 100%:
`days = (T x size - used now) / runway rate`, counted from the last sample. Zero means the threshold is already passed; "never" means usage is flat or falling.
Dates are the last sample time plus the days, in the same time zone as the data.

## Suggested size
The smallest multiple of 10 GB that keeps usage under 80% for the horizon (default 90 days):
`size >= (used now + runway rate x horizon) / 0.8`, and never smaller than the current size.
Example: 128 GB used, 2 GB/day, 180 days -> (128 + 360) / 0.8 = 610 GB.

## Status levels
| Status | Rule |
|---|---|
| CRITICAL | 95% or more used, or full within 7 days |
| HIGH | 90% within 14 days |
| MEDIUM | 80% within 30 days, or accelerating, or a sudden jump |
| OK | none of the above |

## Limits
- A straight line cannot see future events: a migration, a new customer, a log level left on DEBUG.
- Filesystems often misbehave before 100%: ext4 reserves about 5% for root, databases need free space for vacuum, compaction or index builds, and some write paths fail at 90-95%.
- Inode exhaustion (`df -i`) can fill a disk with plenty of free GB; forecast inodes the same way if many small files are written.
- Thin-provisioned and shared storage (LVM thin pools, SAN, Ceph) can fill underneath a volume that looks fine.
FILE:references/disk-full-runbook.md
# Disk Full Runbook

## 1. Find what grows
```
df -h /mount; df -i /mount                       # space and inodes
sudo du -xh --max-depth=2 /mount | sort -h | tail -20
sudo find /mount -xdev -type f -size +1G -mtime -7 -exec ls -lh {} +
sudo lsof +L1                                    # deleted files still held open
journalctl --disk-usage
docker system df                                 # images, containers, volumes, build cache
```
Deleted-but-open files keep their space until the process restarts or reopens the log.

## 2. Safe quick wins (check before deleting)
| Source | Action |
|---|---|
| Application logs | logrotate with `compress`, `maxsize`, `rotate N`; ship logs to central storage |
| systemd journal | `journalctl --vacuum-size=1G`, set `SystemMaxUse=` |
| Docker / CI runners | `docker image prune -a --filter until=168h`, `docker builder prune`; clear runner work dirs |
| Package caches | `apt-get clean`, `dnf clean all`, old kernels |
| Database | archive or drop old partitions, `VACUUM` / table repack, check WAL or binlog retention and stuck replication slots |
| Backups | apply the retention policy; move old sets to object storage or cold tier |
| Core dumps, heap dumps, tmp | remove after the incident owner confirms |
Never `rm` a file a database is using; never clear WAL or binlogs by hand.

## 3. Resize
- **AWS EBS:** modify the volume size, wait for the optimizing state, then `sudo growpart /dev/nvme0n1 1` and `sudo resize2fs /dev/nvme0n1p1` (ext4) or `sudo xfs_growfs /mount` (xfs). One size increase per 6 hours per volume.
- **Azure managed disk / GCP persistent disk:** increase the size (Azure may need the VM deallocated for some disks), then grow the partition and filesystem the same way.
- **LVM:** `lvextend -r -L +100G vg/lv` grows the filesystem too.
- **Kubernetes PVC:** edit `spec.resources.requests.storage` when the StorageClass has `allowVolumeExpansion: true`.
Volumes can grow but rarely shrink, so size to the forecast, not far beyond it.

## 4. Alerts that give time to act
- Warn at 80% used or 14 days of runway; page at 90% or 3 days of runway (Prometheus: `predict_linear(node_filesystem_avail_bytes[6h], 4*3600) < 0` style rules).
- Alert on inode use above 85%.
- Review capacity monthly with this skill's report; add growth from planned launches by hand.
FILE:templates/capacity-review.md
# Capacity Review - <service / fleet> - <date>

**Data:** <source>, <first sample> to <last sample> (<time zone>)  **Horizon:** <90> days  **Reviewer:** <name>

## Runway
| Volume | Status | Used | Size | Growth GB/day (overall / recent) | 90% on | Full on | Suggested size |
|---|---|---|---|---|---|---|---|
| | | | | | | | |

## What is growing
| Volume | Main consumer | Evidence | One-off or ongoing |
|---|---|---|---|
| | | | |

## Actions
| Volume | Action | Owner | Due | Gain |
|---|---|---|---|---|
| | | | | |

## Alerts
- Warning: <80% or 14 days runway>  - Page: <90% or 3 days runway>  - Inodes: <85%>

## Next review
<date>; re-run the forecaster with fresh samples
FILE:examples/fleet-disk-usage.csv
timestamp,volume,used_gb,size_gb
2026-10-01T06:00,db01:/var/lib/postgresql,300.0,500
2026-10-01T06:00,web01:/var/log,21.0,100
2026-10-01T06:00,ci-runner01:/,110.0,200
2026-10-01T06:00,backup-nas:/srv/backups,2100.0,4000
2026-10-02T06:00,db01:/var/lib/postgresql,303.4,500
2026-10-02T06:00,web01:/var/log,24.4,100
2026-10-02T06:00,ci-runner01:/,111.4,200
2026-10-02T06:00,backup-nas:/srv/backups,2105.4,4000
2026-10-03T06:00,db01:/var/lib/postgresql,305.7,500
2026-10-03T06:00,web01:/var/log,26.7,100
2026-10-03T06:00,ci-runner01:/,111.7,200
2026-10-03T06:00,backup-nas:/srv/backups,2109.7,4000
2026-10-04T06:00,db01:/var/lib/postgresql,309.2,500
2026-10-04T06:00,web01:/var/log,30.2,100
2026-10-04T06:00,ci-runner01:/,113.2,200
2026-10-04T06:00,backup-nas:/srv/backups,2115.2,4000
2026-10-05T06:00,db01:/var/lib/postgresql,311.9,500
2026-10-05T06:00,web01:/var/log,32.9,100
2026-10-05T06:00,ci-runner01:/,113.9,200
2026-10-05T06:00,backup-nas:/srv/backups,2119.9,4000
2026-10-06T06:00,db01:/var/lib/postgresql,315.5,500
2026-10-06T06:00,web01:/var/log,22.5,100
2026-10-06T06:00,ci-runner01:/,115.5,200
2026-10-06T06:00,backup-nas:/srv/backups,2125.5,4000
2026-10-07T06:00,db01:/var/lib/postgresql,317.6,500
2026-10-07T06:00,web01:/var/log,24.6,100
2026-10-07T06:00,ci-runner01:/,115.6,200
2026-10-07T06:00,backup-nas:/srv/backups,2129.6,4000
2026-10-08T06:00,db01:/var/lib/postgresql,321.1,500
2026-10-08T06:00,web01:/var/log,28.1,100
2026-10-08T06:00,ci-runner01:/,117.1,200
2026-10-08T06:00,backup-nas:/srv/backups,2135.1,4000
2026-10-09T06:00,db01:/var/lib/postgresql,324.3,500
2026-10-09T06:00,web01:/var/log,31.3,100
2026-10-09T06:00,ci-runner01:/,118.3,200
2026-10-09T06:00,backup-nas:/srv/backups,2140.3,4000
2026-10-10T06:00,db01:/var/lib/postgresql,326.8,500
2026-10-10T06:00,web01:/var/log,33.8,100
2026-10-10T06:00,ci-runner01:/,118.8,200
2026-10-10T06:00,backup-nas:/srv/backups,2144.8,4000
2026-10-11T06:00,db01:/var/lib/postgresql,330.0,500
2026-10-11T06:00,web01:/var/log,23.0,100
2026-10-11T06:00,ci-runner01:/,120.0,200
2026-10-11T06:00,backup-nas:/srv/backups,2150.0,4000
2026-10-12T06:00,db01:/var/lib/postgresql,333.4,500
2026-10-12T06:00,web01:/var/log,26.4,100
2026-10-12T06:00,ci-runner01:/,121.4,200
2026-10-12T06:00,backup-nas:/srv/backups,2155.4,4000
2026-10-13T06:00,db01:/var/lib/postgresql,335.7,500
2026-10-13T06:00,web01:/var/log,28.7,100
2026-10-13T06:00,ci-runner01:/,121.7,200
2026-10-13T06:00,backup-nas:/srv/backups,2159.7,4000
2026-10-14T06:00,db01:/var/lib/postgresql,339.2,500
2026-10-14T06:00,web01:/var/log,32.2,100
2026-10-14T06:00,ci-runner01:/,123.2,200
2026-10-14T06:00,backup-nas:/srv/backups,2165.2,4000
2026-10-15T06:00,db01:/var/lib/postgresql,341.9,500
2026-10-15T06:00,web01:/var/log,34.9,100
2026-10-15T06:00,ci-runner01:/,123.9,200
2026-10-15T06:00,backup-nas:/srv/backups,2169.9,4000
2026-10-16T06:00,db01:/var/lib/postgresql,345.5,500
2026-10-16T06:00,web01:/var/log,24.5,100
2026-10-16T06:00,ci-runner01:/,130.5,200
2026-10-16T06:00,backup-nas:/srv/backups,2575.5,4000
2026-10-17T06:00,db01:/var/lib/postgresql,347.6,500
2026-10-17T06:00,web01:/var/log,26.6,100
2026-10-17T06:00,ci-runner01:/,135.6,200
2026-10-17T06:00,backup-nas:/srv/backups,2579.6,4000
2026-10-18T06:00,db01:/var/lib/postgresql,351.1,500
2026-10-18T06:00,web01:/var/log,30.1,100
2026-10-18T06:00,ci-runner01:/,142.1,200
2026-10-18T06:00,backup-nas:/srv/backups,2585.1,4000
2026-10-19T06:00,db01:/var/lib/postgresql,354.3,500
2026-10-19T06:00,web01:/var/log,33.3,100
2026-10-19T06:00,ci-runner01:/,148.3,200
2026-10-19T06:00,backup-nas:/srv/backups,2590.3,4000
2026-10-20T06:00,db01:/var/lib/postgresql,356.8,500
2026-10-20T06:00,web01:/var/log,35.8,100
2026-10-20T06:00,ci-runner01:/,153.8,200
2026-10-20T06:00,backup-nas:/srv/backups,2594.8,4000
2026-10-21T06:00,db01:/var/lib/postgresql,360.1,500
2026-10-21T06:00,web01:/var/log,25.1,100
2026-10-21T06:00,ci-runner01:/,160.1,200
2026-10-21T06:00,backup-nas:/srv/backups,2600.1,4000
FILE:scripts/disk_runway.py
#!/usr/bin/env python3
"""Disk capacity runway forecaster (Python 3 standard library only).

Input: CSV with a header row and columns
  timestamp,volume,used_gb,size_gb
timestamp is ISO 8601 ("2026-10-01T00:00", "2026-10-01 06:00" or a date); one row per sample,
any order, several volumes in one file. size_gb may change (a resize); the latest value is used.

Model per volume:
  - growth rate = least-squares slope of used_gb over time (GB/day), plus R^2 for fit quality;
    one-off steps larger than 5% of the size are kept in current usage but removed from the trend
  - recent rate = slope over the last 7 days of samples (or the last third if shorter)
  - runway to 80/90/95/100% full = (threshold x size - used now) / max(rate, recent rate),
    counted from the LAST sample (not from today), so results are reproducible
  - suggested size: smallest whole 10 GB step that keeps the volume under 80% for
    --horizon days (default 90) at the worse of the two rates
Status / findings (severity):
  CRITICAL FULL_SOON       100% within 7 days, or already >= 95% used
  HIGH     RUNWAY_SHORT    90% within 14 days
  MEDIUM   RUNWAY_WATCH    80% within 30 days
  MEDIUM   ACCELERATING    recent rate > 1.5x the overall rate (and > 0.1 GB/day)
  MEDIUM   SUDDEN_JUMP     one step grew by more than 5% of the volume size
  LOW      NOISY_TREND     R^2 < 0.5: usage swings (log rotation, temp files); trust less
  LOW      SHRINKING       usage is falling; no runway
  LOW      FEW_SAMPLES     fewer than 4 samples or under 2 days of data
Usage:
  python3 disk_runway.py usage.csv
  python3 disk_runway.py usage.csv --horizon 180 --json
  python3 disk_runway.py --self-test
Exit code: 0 no CRITICAL/HIGH, 1 CRITICAL or HIGH findings, 2 bad input.
"""
import argparse
import csv
import datetime as dt
import io
import json
import math
import sys

THRESHOLDS = (0.8, 0.9, 0.95, 1.0)


class DataError(ValueError):
    pass


def parse_time(s):
    s = s.strip().replace("Z", "+00:00")
    try:
        t = dt.datetime.fromisoformat(s)
    except ValueError:
        raise DataError(f"bad timestamp {s!r}")
    return t.replace(tzinfo=None) if t.tzinfo is None else t.astimezone(dt.timezone.utc).replace(tzinfo=None)


def read_rows(text):
    rd = csv.DictReader(io.StringIO(text))
    need = {"timestamp", "volume", "used_gb", "size_gb"}
    if not rd.fieldnames or not need <= {f.strip() for f in rd.fieldnames}:
        raise DataError(f"CSV header must contain {', '.join(sorted(need))}")
    vols = {}
    for n, row in enumerate(rd, start=2):
        row = {k.strip(): (v or "").strip() for k, v in row.items() if k}
        if not any(row.values()):
            continue
        try:
            used, size = float(row["used_gb"]), float(row["size_gb"])
        except ValueError:
            raise DataError(f"line {n}: used_gb and size_gb must be numbers")
        if size <= 0 or used < 0:
            raise DataError(f"line {n}: size_gb must be > 0 and used_gb >= 0")
        vols.setdefault(row["volume"] or "(unnamed)", []).append((parse_time(row["timestamp"]), used, size))
    if not vols:
        raise DataError("no data rows")
    return {k: sorted(v) for k, v in vols.items()}


def slope(points):
    """points: [(days, value)] -> (slope per day, r2)"""
    n = len(points)
    if n < 2:
        return 0.0, 0.0
    mx = sum(p[0] for p in points) / n
    my = sum(p[1] for p in points) / n
    sxx = sum((p[0] - mx) ** 2 for p in points)
    if sxx == 0:
        return 0.0, 0.0
    sxy = sum((p[0] - mx) * (p[1] - my) for p in points)
    b = sxy / sxx
    syy = sum((p[1] - my) ** 2 for p in points)
    r2 = 1.0 if syy == 0 else (sxy * sxy) / (sxx * syy)
    return b, r2


def analyze(samples, horizon=90):
    t0 = samples[0][0]
    last_t, used, size = samples[-1]
    # one-off steps (> 5% of size in one sample) are removed from the trend, not extrapolated
    steps = [samples[i][1] - samples[i - 1][1] for i in range(1, len(samples))]
    normal = sorted(x for x in steps if x <= 0.05 * size)
    typical = normal[len(normal) // 2] if normal else 0.0
    shift, pts = 0.0, []
    for i, (t, u, _) in enumerate(samples):
        if i and steps[i - 1] > 0.05 * size:
            shift += steps[i - 1] - typical
        pts.append(((t - t0).total_seconds() / 86400, u - shift))
    span = pts[-1][0]
    rate, r2 = slope(pts)
    cut = pts[-1][0] - 7 if span >= 14 else pts[-1][0] - span / 3
    recent_pts = [p for p in pts if p[0] >= cut]
    recent, _ = slope(recent_pts) if len(recent_pts) >= 2 else (rate, 0)
    worst = max(rate, recent)
    pct = used / size
    runway = {}
    for th in THRESHOLDS:
        left = th * size - used
        if left <= 0:
            runway[th] = (0.0, last_t)
        elif worst > 1e-9:
            d = left / worst
            runway[th] = (d, last_t + dt.timedelta(days=d))
        else:
            runway[th] = (None, None)
    need = used + max(worst, 0) * horizon
    suggest = max(size, math.ceil(need / 0.8 / 10) * 10)
    findings = []

    def f(sev, code, msg):
        findings.append({"severity": sev, "code": code, "message": msg})

    d100, d90, d80 = runway[1.0][0], runway[0.9][0], runway[0.8][0]
    if pct >= 0.95 or (d100 is not None and d100 <= 7):
        f("CRITICAL", "FULL_SOON", f"{pct:.0%} used; full in {fmt_days(d100)}")
    elif d90 is not None and d90 <= 14:
        f("HIGH", "RUNWAY_SHORT", f"90% in {fmt_days(d90)}")
    elif d80 is not None and d80 <= 30:
        f("MEDIUM", "RUNWAY_WATCH", f"80% in {fmt_days(d80)}")
    if rate > 0 and recent > 1.5 * rate and recent > 0.1:
        f("MEDIUM", "ACCELERATING", f"last-week rate {recent:.2f} GB/day vs overall {rate:.2f} GB/day")
    jumps = [(samples[i][0], samples[i][1] - samples[i - 1][1]) for i in range(1, len(samples))]
    big = [j for j in jumps if j[1] > 0.05 * size]
    if big:
        t, g = max(big, key=lambda j: j[1])
        f("MEDIUM", "SUDDEN_JUMP", f"+{g:.1f} GB in one step at {t:%Y-%m-%d %H:%M} (backup, dump, log burst?)")
    if len(pts) >= 4 and r2 < 0.5 and worst > 0:
        f("LOW", "NOISY_TREND", f"R^2 {r2:.2f}; usage swings, so treat the runway as rough")
    if worst < 0:
        f("LOW", "SHRINKING", f"usage falling {rate:.2f} GB/day")
    if len(pts) < 4 or span < 2:
        f("LOW", "FEW_SAMPLES", f"{len(pts)} samples over {span:.1f} days; collect more data")
    rank = {"CRITICAL": 0, "HIGH": 1, "MEDIUM": 2, "LOW": 3}
    findings.sort(key=lambda x: rank[x["severity"]])
    return {"last_sample": last_t.strftime("%Y-%m-%d %H:%M"), "used_gb": round(used, 2), "size_gb": size,
            "used_pct": round(pct * 100, 1), "rate_gb_day": round(rate, 3), "recent_rate_gb_day": round(recent, 3),
            "r2": round(r2, 3), "samples": len(pts), "span_days": round(span, 2),
            "runway": {f"{int(th * 100)}%": {"days": None if d is None else round(d, 1),
                                             "date": None if t is None else t.strftime("%Y-%m-%d")}
                       for th, (d, t) in runway.items()},
            "suggested_size_gb": suggest, "horizon_days": horizon, "findings": findings,
            "status": findings[0]["severity"] if findings and findings[0]["severity"] in ("CRITICAL", "HIGH", "MEDIUM") else "OK"}


def fmt_days(d):
    if d is None:
        return "never at current rate"
    if d <= 0:
        return "already"
    if d < 1:
        return f"{d * 24:.0f} h"
    return f"{d:.1f} days"


def report(res, horizon):
    out = ["# Disk runway report", "", f"Runway uses the worse of the overall and last-week growth rate; suggested size keeps usage under 80% for {horizon} days.", "",
           "| Volume | Status | Used | Size | Growth GB/day (overall / recent) | 80% | 90% | 100% | Suggested size |",
           "|---|---|---|---|---|---|---|---|---|"]
    order = {"CRITICAL": 0, "HIGH": 1, "MEDIUM": 2, "OK": 3}
    for name, r in sorted(res.items(), key=lambda kv: (order[kv[1]["status"]], kv[0])):
        def cell(k):
            x = r["runway"][k]
            if x["days"] is None:
                return "never"
            return "now" if x["days"] == 0 else f"{x['days']} d ({x['date']})"
        out.append(f"| {name} | {r['status']} | {r['used_gb']:g} GB ({r['used_pct']}%) | {r['size_gb']:g} GB | "
                   f"{r['rate_gb_day']} / {r['recent_rate_gb_day']} | {cell('80%')} | {cell('90%')} | {cell('100%')} | "
                   f"{r['suggested_size_gb']:g} GB |")
    out += ["", "## Findings"]
    any_f = False
    for name, r in sorted(res.items(), key=lambda kv: (order[kv[1]["status"]], kv[0])):
        for x in r["findings"]:
            any_f = True
            out.append(f"- **{x['severity']} {x['code']}** ({name}): {x['message']}")
    if not any_f:
        out.append("- none")
    out += ["", "Last samples: " + ", ".join(f"{n} {r['last_sample']} ({r['samples']} samples, {r['span_days']} days, R^2 {r['r2']})" for n, r in sorted(res.items()))]
    return "\n".join(out) + "\n"


def run(text, horizon=90):
    if horizon <= 0:
        raise DataError("horizon must be > 0")
    return {name: analyze(s, horizon) for name, s in read_rows(text).items()}


def self_test():
    cases = []

    def ok(name, cond):
        cases.append(bool(cond))
        print(("PASS " if cond else "FAIL ") + name)

    b, r2 = slope([(0, 10), (1, 12), (2, 14)])
    ok("slope 2/day exact fit", abs(b - 2) < 1e-9 and abs(r2 - 1) < 1e-9)
    ok("flat slope 0", slope([(0, 5), (1, 5), (2, 5)])[0] == 0)
    hdr = "timestamp,volume,used_gb,size_gb\n"
    lin = hdr + "".join(f"2026-10-{d:02d},v,{100 + 2 * d},500\n" for d in range(1, 15))
    r = run(lin)["v"]
    ok("rate 2 GB/day", abs(r["rate_gb_day"] - 2) < 1e-6)
    ok("80% runway (400-128)/2 = 136 d", r["runway"]["80%"]["days"] == 136.0)
    ok("runway date from last sample", r["runway"]["100%"]["date"] == "2027-04-18")
    ok("healthy volume status OK", r["status"] == "OK" and r["findings"] == [])
    ok("suggested size keeps 500", r["suggested_size_gb"] == 500)
    r = run(lin, horizon=180)["v"]
    ok("180 d horizon suggests 610", r["suggested_size_gb"] == 610)
    full = hdr + "".join(f"2026-10-{d:02d},v,{80 + 3 * d},100\n" for d in range(1, 6))
    r = run(full)["v"]
    ok("95% used is CRITICAL", r["status"] == "CRITICAL" and r["findings"][0]["code"] == "FULL_SOON")
    ok("past threshold runway is 0", r["runway"]["90%"]["days"] == 0)
    short = hdr + "".join(f"2026-10-{d:02d},v,{50 + 3 * d},100\n" for d in range(1, 8))
    r = run(short)["v"]
    ok("90% in ~6 days is HIGH", r["status"] == "HIGH")
    watch = hdr + "".join(f"2026-10-{d:02d},v,{40 + d},100\n" for d in range(1, 8))
    ok("80% in 33 d is OK, 80% in 26 d is MEDIUM", run(watch)["v"]["status"] == "OK" and
       run(hdr + "".join(f"2026-10-{d:02d},v,{47 + d},100\n" for d in range(1, 8)))["v"]["status"] == "MEDIUM")
    acc = hdr + "".join(f"2026-10-{d:02d},v,{100 + (d if d <= 14 else 14 + 5 * (d - 14))},1000\n" for d in range(1, 22))
    r = run(acc)["v"]
    ok("accelerating flagged", any(x["code"] == "ACCELERATING" for x in r["findings"]))
    ok("recent rate used for runway", r["recent_rate_gb_day"] > r["rate_gb_day"])
    jump = hdr + "2026-10-01,v,100,500\n2026-10-02,v,101,500\n2026-10-03,v,140,500\n2026-10-04,v,141,500\n"
    r = run(jump)["v"]
    ok("sudden jump flagged", any(x["code"] == "SUDDEN_JUMP" for x in r["findings"]))
    ok("jump removed from trend (1 GB/day)", abs(r["rate_gb_day"] - 1) < 1e-6 and r["used_gb"] == 141)
    noisy = hdr + "".join(f"2026-10-{d:02d},v,{100 + (8 if d % 2 else 0) + 0.3 * d:.1f},500\n" for d in range(1, 21))
    ok("noisy trend flagged", any(x["code"] == "NOISY_TREND" for x in run(noisy)["v"]["findings"]))
    shr = hdr + "".join(f"2026-10-{d:02d},v,{200 - 3 * d},500\n" for d in range(1, 8))
    r = run(shr)["v"]
    ok("shrinking flagged and runway never", any(x["code"] == "SHRINKING" for x in r["findings"]) and r["runway"]["100%"]["days"] is None)
    few = hdr + "2026-10-01T00:00,v,10,100\n2026-10-01T12:00,v,11,100\n"
    ok("few samples flagged", any(x["code"] == "FEW_SAMPLES" for x in run(few)["v"]["findings"]))
    multi = hdr + "2026-10-02,b,5,100\n2026-10-01,a,1,100\n2026-10-01,b,4,100\n2026-10-02,a,1,100\n"
    r = run(multi)
    ok("multiple volumes, unsorted rows", set(r) == {"a", "b"} and r["b"]["rate_gb_day"] == 1)
    ok("resize uses latest size", run(hdr + "2026-10-01,v,50,100\n2026-10-02,v,52,200\n")["v"]["size_gb"] == 200)
    ok("fmt_days hours", fmt_days(0.5) == "12 h")
    for bad, label in (("a,b\n1,2\n", "missing columns"), (hdr, "no rows"), (hdr + "x,v,1,10\n", "bad timestamp"),
                       (hdr + "2026-10-01,v,abc,10\n", "bad number"), (hdr + "2026-10-01,v,1,0\n", "zero size")):
        try:
            run(bad)
            ok(label + " rejected", False)
        except DataError:
            ok(label + " rejected", True)
    print(f"{sum(cases)}/{len(cases)} passed")
    return 0 if all(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Forecast when disks fill up from usage samples.")
    ap.add_argument("file", nargs="?", help="CSV: timestamp,volume,used_gb,size_gb")
    ap.add_argument("--horizon", type=int, default=90, help="days of runway the suggested size must cover (default 90)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("give a CSV file or --self-test")
    try:
        res = run(open(a.file, encoding="utf-8").read(), a.horizon)
    except (OSError, DataError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(res, indent=2) if a.json else report(res, a.horizon), end="\n" if a.json else "")
    return 1 if any(r["status"] in ("CRITICAL", "HIGH") for r in res.values()) else 0


if __name__ == "__main__":
sys.exit(main())计算一个或多个房间需要购买多少涂料及其费用。测量墙面(扣除门窗)和天花板,应用涂层次数、覆盖率、纹理和损耗,汇总各房间每种涂料的总量,并挑选剩余最少的最省钱罐装组合。标记需要底漆的深色转浅色变更和新灰泥、单层涂刷方案、可疑的覆盖率或高度,以及大量剩余。包含一个带 --self-test 的标准库 Python 估算器。
---
name: room-paint-quantity-estimator
description: Works out how much paint to buy for one or more rooms and what it will cost. Measures walls (minus doors and windows) and ceilings, applies coats, coverage, texture and waste, adds up each paint across rooms, and picks the cheapest can mix with little left over. Flags dark-to-light changes and new plaster that need primer, one-coat plans, suspicious coverage or heights and big leftovers. Includes a stdlib Python estimator with --self-test.
---

# Room Paint Quantity Estimator

You help people repainting a home buy the right amount of paint the first time: not three trips to the shop, not a garage full of half-empty cans. From room sizes and the paints they picked, you calculate areas, litres (or gallons), the cheapest cans to buy and the total cost, and you point out the prep steps that change the numbers, such as primer over dark colours or new plaster.

## Files in this skill

- `scripts/paint_estimate.py` - calculates areas, paint per surface, the cheapest can mix per paint, leftovers, total cost and findings (Python 3 standard library only)
- `references/measuring-and-coverage.md` - how to measure rooms, standard door and window sizes, coverage on the label vs reality, texture factors, coats and primer rules
- `references/painting-prep-and-buying-guide.md` - prep order, primer types, finishes per room, tools list, buying tips, storing leftovers
- `templates/paint-shopping-list.md` - a shopping list and room plan to print or take to the shop
- `examples/two-bedroom-flat-refresh.json` - four rooms in a flat with a dark bedroom going light, new drywall in the kids room and three paints in Turkish lira

## Workflow

### 1. Gather the rooms
Ask for each room: length, width and ceiling height, number and size of doors and windows (or use the standard sizes in `references/measuring-and-coverage.md`), which surfaces to paint (walls, ceiling), the current colour (light, medium, dark), the new colour, wall texture, and whether any surface is new plaster or drywall. Ask for the paints with coverage per coat from the can label and the can sizes and prices at their shop. Use metric unless they work in feet and gallons.

### 2. Run the estimator
```
python3 scripts/paint_estimate.py examples/two-bedroom-flat-refresh.json
python3 scripts/paint_estimate.py job.json --json
python3 scripts/paint_estimate.py --self-test
```
Exit code 1 means HIGH findings (measurements that cannot be right, no can mix), 2 means bad input.

### 3. Adjust the plan
Act on findings: add primer (and its own quantity, using its coverage) for DARK_TO_LIGHT and NEW_SURFACE, or raise coats to 3; change one-coat plans to two unless the paint is sold as one-coat over the same colour. Re-run after each change. Use `references/painting-prep-and-buying-guide.md` for finish and tool advice.

### 4. Deliver
Fill `templates/paint-shopping-list.md` with the cans to buy, primer, tools and the order of work. Remind them to buy all cans of one colour from the same batch, or mix (box) them before use.

## Example result
For `examples/two-bedroom-flat-refresh.json`: walls in warm white need 20.87 L -> 1 x 15 L + 1 x 7.5 L (3,640 TRY); the kids room sage green needs 6.87 L -> 1 x 7.5 L (1,450 TRY); ceilings need 8.75 L -> 3 x 3.5 L (1,380 TRY); total 6,470 TRY before primer and tools. Findings: the dark main bedroom needs primer or a third coat, the new drywall in the kids room needs a mist coat or primer, and its one-coat ceiling will look patchy.

## Rules

- Use the coverage printed on the user's paint, not a generic number, whenever they have it.
- Round up to whole cans; never suggest stretching paint by thinning beyond the maker's instructions.
- Mention safety where it matters: ventilation, ladders on stable ground, lead paint testing in homes built before about 1980 before sanding.
- Prices are what the user gives; say that totals exclude primer, tools and labour unless included.
FILE:references/measuring-and-coverage.md
# Measuring and Coverage

## Measuring a room
- Measure length and width at floor level and ceiling height in one or two places; round up to the next 5 cm (or 2 in).
- Wall area = perimeter x height = 2 x (length + width) x height. For L-shaped rooms, add each wall's width x height instead.
- Ceiling area = length x width (add sloped parts separately).
- Subtract doors and windows; leave in anything smaller than about 0.5 m2 (5 sq ft), the paint goes on the frame and cutting-in anyway.

## Standard sizes (when the user does not know)
| Item | Metric | Imperial |
|---|---|---|
| Interior door | 0.8-0.9 x 2.0-2.05 m (about 1.8 m2) | 30-36 x 80 in (about 20 sq ft) |
| Balcony / patio door | 1.6-1.8 x 2.2 m | 6 x 6.7 ft |
| Window | 1.2-1.5 x 1.2-1.4 m | 3 x 4 ft (about 12-15 sq ft) |
| Ceiling height | 2.5-2.8 m (new flats), up to 3.5 m (old buildings) | 8-9 ft |

## Coverage
- The label gives coverage per coat, usually 10-14 m2/L for emulsion (about 350-400 sq ft per US gallon). Real-world coverage is often 10-20% lower; the waste allowance (default 10%) covers rollers, trays and touch-ups.
- Texture factors used by the estimator: smooth x1.0, light texture (woodchip, orange peel, thin plaster) x1.1, rough (bare brick, stucco, popcorn) x1.25.
- Fresh plaster and bare drywall soak paint like a sponge: seal first with a mist coat (emulsion thinned as the maker allows) or a drywall primer.

## Coats
| Situation | Plan |
|---|---|
| Same or similar colour, good surface | 2 coats (1 if the paint is sold as one-coat and the colour is the same) |
| Light over dark | stain-blocking or tinted primer + 2 coats, or 3 coats |
| Dark or strong colour over light | grey-tinted primer + 2 coats; reds and yellows can need 3 |
| New plaster or drywall | mist coat or primer + 2 coats |
| Ceiling | 2 coats of ceiling white; 1 coat looks patchy against the light |

## Quick check by hand
Litres = area x coats x texture / coverage x 1.1. Example: 35 m2 of walls, 2 coats, 10 m2/L, smooth -> 7 L before waste, 7.7 L with 10% waste.
FILE:references/painting-prep-and-buying-guide.md
# Painting Prep and Buying Guide

## Order of work
1. Clear and cover: furniture to the middle, floors covered, switch plates off (power off when working near sockets).
2. Repair: fill cracks and holes, sand flush, wipe dust; wash greasy kitchen walls with sugar soap.
3. Prime where needed (stains, repairs, dark colours, new plaster).
4. Ceiling first, then walls, then trim and doors last.
5. Cut in edges with a brush, then roll in sections while the edge is still wet to avoid lines.
6. Let each coat dry for the time on the can (often 2-4 hours for emulsion) before the next.

## Primer
| Problem | Primer |
|---|---|
| Water stains, smoke, marker | stain-blocking primer (shellac or oil-based for bad stains) |
| Light over dark | white or tinted universal primer |
| New plaster | mist coat or plaster sealer |
| New drywall | drywall (PVA) primer |
| Glossy old paint | sand lightly, then adhesion primer |
Primer coverage is often 8-12 m2/L; estimate it like a paint with 1 coat.

## Finish by room
| Room | Finish | Why |
|---|---|---|
| Ceilings | flat / matte | hides flaws, no glare |
| Living and bedrooms | matte or eggshell | soft look; washable matte for families |
| Kids rooms, hallways | washable matte or eggshell | scrubbable |
| Kitchens and bathrooms | satin or a kitchen/bathroom paint | moisture and grease resistant |
| Doors and trim | satin or semi-gloss | durable, easy to wipe |

## Tools for a typical flat
Rollers (9 in / 23 cm) with an extension pole, a tray or bucket with a grid, angled brushes (5 cm), masking tape, drop sheets, filler and a knife, sandpaper (120-180 grit), a sturdy step ladder, rags, gloves. One roller sleeve per colour.

## Buying tips
- Price per litre usually drops with bigger cans; the estimator compares the actual shop prices.
- Buy all cans of a colour together (same batch). If you open more than one can, mix them in a bucket (boxing) so the colour matches.
- Keep about 0.5 L of each colour for touch-ups.
- Low-VOC paints reduce smell; keep windows open and take breaks anyway.

## Leftovers
Close lids tightly, store upside down above freezing, label with room and date. Do not pour paint down drains; take dried or liquid paint to the local waste or recycling point.
FILE:templates/paint-shopping-list.md
# Paint Shopping List - <home / project> - <date>

**Units:** <metric / imperial>  **Waste allowance:** <10%>  **Shop:** <name>

## Rooms
| Room | Surface | Area | Coats | Paint | Notes (primer, repairs) |
|---|---|---|---|---|---|
| | | | | | |

## Paint to buy
| Paint (brand, colour code, finish) | Needed | Cans | Price |
|---|---|---|---|
| | | | |

## Primer and supplies
- [ ] Primer: <type>, <qty>
- [ ] Rollers <n>, sleeves <n>, tray, extension pole
- [ ] Brushes <sizes>, masking tape <rolls>, drop sheets <n>
- [ ] Filler, sandpaper, sugar soap

**Total estimate:** <paint> + <primer and supplies> = <total>

## Work order
1. Prep and repairs: <rooms>
2. Primer: <rooms>
3. Ceilings: <rooms>
4. Walls: <rooms>
5. Trim and doors: <rooms>
FILE:examples/two-bedroom-flat-refresh.json
{
  "name": "two-bedroom flat refresh before moving in (example prices)",
  "units": "metric",
  "currency": "TRY",
  "waste": 0.1,
  "paints": {
    "wall matte warm white": {"coverage": 11, "cans": [{"size": 15, "price": 2350}, {"size": 7.5, "price": 1290}, {"size": 2.5, "price": 520}]},
    "sage green (kids room)": {"coverage": 10, "cans": [{"size": 7.5, "price": 1450}, {"size": 2.5, "price": 590}, {"size": 0.75, "price": 240}]},
    "ceiling white": {"coverage": 12, "cans": [{"size": 15, "price": 1650}, {"size": 3.5, "price": 460}]}
  },
  "rooms": [
    {"name": "living room", "length": 5.4, "width": 4.2, "height": 2.7,
     "openings": [{"type": "door", "w": 0.9, "h": 2.05}, {"type": "balcony door", "w": 1.8, "h": 2.2}, {"type": "window", "w": 1.5, "h": 1.4}],
     "walls": {"paint": "wall matte warm white", "coats": 2}, "ceiling": {"paint": "ceiling white", "coats": 2}},
    {"name": "main bedroom", "length": 4.0, "width": 3.5, "height": 2.7, "previous": "dark", "new": "light",
     "openings": [{"type": "door", "w": 0.9, "h": 2.05}, {"type": "window", "w": 1.4, "h": 1.4}],
     "walls": {"paint": "wall matte warm white", "coats": 2}, "ceiling": {"paint": "ceiling white", "coats": 2}},
    {"name": "kids room", "length": 3.4, "width": 3.0, "height": 2.7, "new_surface": true,
     "openings": [{"type": "door", "w": 0.8, "h": 2.05}, {"type": "window", "w": 1.2, "h": 1.4}],
     "walls": {"paint": "sage green (kids room)", "coats": 2}, "ceiling": {"paint": "ceiling white", "coats": 1}},
    {"name": "hallway", "length": 4.5, "width": 1.2, "height": 2.7, "texture": "light",
     "openings": [{"type": "doors", "w": 0.9, "h": 2.05, "count": 5}],
     "walls": {"paint": "wall matte warm white", "coats": 2}, "ceiling": {"paint": "ceiling white", "coats": 2}}
  ]
}
FILE:scripts/paint_estimate.py
#!/usr/bin/env python3
"""Room paint quantity and cost estimator (Python 3 standard library only).

Input: a painting job JSON file:
  {"units": "metric", "waste": 0.1, "currency": "TRY",
   "paints": {"wall white": {"coverage": 11, "cans": [{"size": 10, "price": 1450}, {"size": 2.5, "price": 450}]}},
   "rooms": [{"name": "living room", "length": 5.2, "width": 4.1, "height": 2.7,
              "openings": [{"type": "door", "w": 0.9, "h": 2.05}, {"type": "window", "w": 1.6, "h": 1.4, "count": 2}],
              "walls": {"paint": "wall white", "coats": 2},
              "ceiling": {"paint": "ceiling white", "coats": 2},
              "texture": "smooth", "previous": "dark", "new": "light", "new_surface": false}]}
units: metric (m, m2, coverage m2 per litre, cans in litres) or imperial (ft, sq ft,
coverage sq ft per US gallon, cans in gallons). coverage = per coat, from the paint can.
Areas: walls = 2 x (length + width) x height - openings; ceiling = length x width.
texture: smooth (x1.0), light (x1.1, e.g. woodchip, orange peel), rough (x1.25, brick, stucco)
multiplies the paint needed. waste (default 0.10) adds rollers, trays, touch-ups.
Volume per surface = area x coats x texture / coverage x (1 + waste); volumes for the same paint
are added up across rooms, then the cheapest can mix that covers it is chosen (fewer litres
left over on ties).
Findings: OPENINGS_TOO_LARGE (HIGH), NO_CAN_MIX (HIGH), DARK_TO_LIGHT and NEW_SURFACE
(MEDIUM: primer or an extra coat), ONE_COAT, COVERAGE_SUSPECT, ODD_HEIGHT, BIG_LEFTOVER (LOW).
Usage:
  python3 paint_estimate.py job.json
  python3 paint_estimate.py job.json --json
  python3 paint_estimate.py --self-test
Exit code: 0 OK, 1 HIGH findings, 2 bad input.
"""
import argparse
import json
import math
import sys

TEXTURE = {"smooth": 1.0, "light": 1.1, "rough": 1.25}
UNITS = {"metric": {"len": "m", "area": "m2", "vol": "L", "cov": (6, 16), "height": (2.2, 4.0)},
         "imperial": {"len": "ft", "area": "sq ft", "vol": "gal", "cov": (250, 450), "height": (7.0, 13.0)}}
LIGHTNESS = {"light": 0, "medium": 1, "dark": 2}


class JobError(ValueError):
    pass


def num(x, what, minimum=0.0, strict=True):
    if isinstance(x, bool) or not isinstance(x, (int, float)) or (x <= minimum if strict else x < minimum):
        raise JobError(f"{what} must be a number {'>' if strict else '>='} {minimum:g}")
    return float(x)


def best_mix(need, cans):
    """Cheapest combination of cans with total size >= need; ties -> less leftover, fewer cans."""
    cans = sorted(cans, key=lambda c: -c["size"])
    best = None

    def rec(i, vol, cost, picked):
        nonlocal best
        if vol >= need - 1e-9:
            key = (round(cost, 6), round(vol - need, 6), sum(picked))
            if best is None or key < best[0]:
                best = (key, list(picked), vol, cost)
            return
        if i == len(cans) or (best is not None and cost > best[0][0] + 1e-9):
            return
        c = cans[i]
        top = math.ceil((need - vol) / c["size"] - 1e-9)
        for k in ([top] if i == len(cans) - 1 else range(top, -1, -1)):
            picked.append(k)
            rec(i + 1, vol + k * c["size"], cost + k * c["price"], picked)
            picked.pop()

    if need <= 0:
        return {"cans": [], "volume": 0.0, "cost": 0.0, "leftover": 0.0}
    rec(0, 0.0, 0.0, [])
    if best is None:
        return None
    _, picked, vol, cost = best
    return {"cans": [{"size": c["size"], "count": k, "price": c["price"]} for c, k in zip(cans, picked) if k],
            "volume": vol, "cost": cost, "leftover": vol - need}


def estimate(job):
    units = str(job.get("units", "metric")).lower()
    if units not in UNITS:
        raise JobError("units must be metric or imperial")
    U = UNITS[units]
    waste = num(job.get("waste", 0.1), "waste", 0, strict=False)
    paints = job.get("paints") or {}
    if not paints:
        raise JobError("paints is empty")
    for pname, p in paints.items():
        num(p.get("coverage"), f"paint {pname!r} coverage")
        if not p.get("cans"):
            raise JobError(f"paint {pname!r} has no cans")
        for c in p["cans"]:
            num(c.get("size"), f"paint {pname!r} can size")
            num(c.get("price", 0), f"paint {pname!r} can price", 0, strict=False)
    rooms = job.get("rooms") or []
    if not rooms:
        raise JobError("rooms is empty")
    findings, lines, need = [], [], {}

    def f(sev, code, where, msg):
        findings.append({"severity": sev, "code": code, "where": where, "message": msg})

    for r in rooms:
        name = r.get("name") or "room"
        L, W, H = (num(r.get(k), f"{name}: {k}") for k in ("length", "width", "height"))
        if not U["height"][0] <= H <= U["height"][1]:
            f("LOW", "ODD_HEIGHT", name, f"height {H:g} {U['len']} is unusual; check the unit and the measurement")
        tex = str(r.get("texture", "smooth")).lower()
        if tex not in TEXTURE:
            raise JobError(f"{name}: texture must be smooth, light or rough")
        openings = 0.0
        for o in r.get("openings") or []:
            cnt = o.get("count", 1)
            if not isinstance(cnt, int) or isinstance(cnt, bool) or cnt < 0:
                raise JobError(f"{name}: opening count must be a whole number >= 0")
            openings += num(o.get("w"), f"{name}: opening w") * num(o.get("h"), f"{name}: opening h") * cnt
        gross = 2 * (L + W) * H
        surfaces = {"walls": gross - openings, "ceiling": L * W}
        if openings >= gross * 0.6:
            f("HIGH", "OPENINGS_TOO_LARGE", name, f"openings {openings:.1f} {U['area']} are {openings / gross:.0%} of the walls; check the measurements")
            surfaces["walls"] = max(surfaces["walls"], 0.0)
        prev, new = r.get("previous"), r.get("new")
        for sname in ("walls", "ceiling"):
            s = r.get(sname)
            if not s:
                continue
            pname = s.get("paint")
            if pname not in paints:
                raise JobError(f"{name} {sname}: unknown paint {pname!r}")
            coats = s.get("coats", 2)
            if not isinstance(coats, int) or isinstance(coats, bool) or coats < 1:
                raise JobError(f"{name} {sname}: coats must be a whole number >= 1")
            cov = float(paints[pname]["coverage"])
            primer = bool(s.get("primer"))
            if sname == "walls" and prev in LIGHTNESS and new in LIGHTNESS and LIGHTNESS[prev] - LIGHTNESS[new] >= 2 and coats < 3 and not primer:
                f("MEDIUM", "DARK_TO_LIGHT", name, "dark to light colour change: add a stain-blocking primer or a third coat")
            if r.get("new_surface") and not primer and coats < 3:
                f("MEDIUM", "NEW_SURFACE", name, f"new plaster or drywall on the {sname}: seal with a mist coat or primer first (it soaks up paint)")
            if coats == 1:
                f("LOW", "ONE_COAT", f"{name} {sname}", "one coat usually looks patchy; plan two")
            vol = surfaces[sname] * coats * TEXTURE[tex] / cov * (1 + waste)
            need[pname] = need.get(pname, 0.0) + vol
            lines.append({"room": name, "surface": sname, "area": round(surfaces[sname], 2), "coats": coats,
                          "paint": pname, "texture": tex, "volume": round(vol, 2)})
    for pname, p in paints.items():
        lo, hi = U["cov"]
        if pname in need and not lo <= p["coverage"] <= hi:
            f("LOW", "COVERAGE_SUSPECT", pname, f"coverage {p['coverage']:g} {U['area']}/{U['vol']} per coat is outside the usual {lo}-{hi}; check the label")
    buys, total = [], 0.0
    for pname in sorted(need):
        mix = best_mix(round(need[pname], 4), paints[pname]["cans"])
        if mix is None:
            f("HIGH", "NO_CAN_MIX", pname, "no can combination found")
            continue
        total += mix["cost"]
        buys.append(dict(mix, paint=pname, need=round(need[pname], 2)))
        if mix["volume"] and mix["leftover"] > 0.3 * mix["volume"] and mix["leftover"] > 1:
            f("LOW", "BIG_LEFTOVER", pname, f"{mix['leftover']:.1f} {U['vol']} left over; keep it for touch-ups or check smaller can prices")
    rank = {"HIGH": 0, "MEDIUM": 1, "LOW": 2}
    findings.sort(key=lambda x: rank[x["severity"]])
    return {"name": job.get("name", "painting job"), "units": units, "currency": job.get("currency", ""),
            "waste": waste, "lines": lines, "buy": buys, "total_cost": round(total, 2), "findings": findings}


def g(x):
    return f"{x:.2f}".rstrip("0").rstrip(".")


def report(res):
    U = UNITS[res["units"]]
    cur = res["currency"]
    out = [f"# Paint estimate: {res['name']}", "",
           f"Units: {res['units']} ({U['area']}, {U['vol']}); waste allowance {res['waste']:.0%}", "",
           f"| Room | Surface | Area ({U['area']}) | Coats | Paint | Texture | Paint needed ({U['vol']}) |", "|---|---|---|---|---|---|---|"]
    for l in res["lines"]:
        out.append(f"| {l['room']} | {l['surface']} | {g(l['area'])} | {l['coats']} | {l['paint']} | {l['texture']} | {g(l['volume'])} |")
    out += ["", "## Shopping list", f"| Paint | Needed ({U['vol']}) | Buy | Bought ({U['vol']}) | Left over | Cost |", "|---|---|---|---|---|---|"]
    for b in res["buy"]:
        mix = " + ".join(f"{c['count']} x {g(c['size'])} {U['vol']}" for c in b["cans"])
        out.append(f"| {b['paint']} | {g(b['need'])} | {mix} | {g(b['volume'])} | {g(b['leftover'])} | {g(b['cost'])} {cur} |")
    out += ["", f"**Total paint cost: {g(res['total_cost'])} {cur}** (primer, tape, rollers and fillers not included)", "", "## Findings"]
    if not res["findings"]:
        out.append("- none")
    for x in res["findings"]:
        out.append(f"- **{x['severity']} {x['code']}** ({x['where']}): {x['message']}")
    return "\n".join(out) + "\n"


def self_test():
    cases = []

    def ok(name, cond):
        cases.append(bool(cond))
        print(("PASS " if cond else "FAIL ") + name)

    cans = [{"size": 10, "price": 100}, {"size": 2.5, "price": 30}]
    m = best_mix(11, cans)
    ok("11 L -> 10 + 2.5 for 130", m["cost"] == 130 and m["volume"] == 12.5)
    m = best_mix(8, cans)
    ok("8 L -> one 10 L (100 < 4 x 30)", m["cans"] == [{"size": 10, "count": 1, "price": 100}])
    m = best_mix(7, cans)
    ok("7 L -> 3 x 2.5 for 90", m["cost"] == 90 and m["leftover"] == 0.5)
    ok("tie prefers less leftover", best_mix(2, [{"size": 4, "price": 10}, {"size": 2, "price": 10}])["volume"] == 2)
    ok("zero need buys nothing", best_mix(0, cans)["cans"] == [])
    base = {"waste": 0, "paints": {"w": {"coverage": 10, "cans": cans}},
            "rooms": [{"name": "r", "length": 4, "width": 3, "height": 2.5, "walls": {"paint": "w", "coats": 2}}]}
    r = estimate(base)
    ok("wall area 2x(4+3)x2.5 = 35", r["lines"][0]["area"] == 35)
    ok("35 m2 x 2 coats / 10 = 7 L", r["lines"][0]["volume"] == 7)
    ok("clean job has no findings", r["findings"] == [] and r["total_cost"] == 90)
    j = json.loads(json.dumps(base)); j["rooms"][0]["openings"] = [{"w": 0.9, "h": 2, "count": 1}, {"w": 1.2, "h": 1.25, "count": 2}]
    ok("openings subtracted (35 - 1.8 - 3 = 30.2)", estimate(j)["lines"][0]["area"] == 30.2)
    j = json.loads(json.dumps(base)); j["rooms"][0]["ceiling"] = {"paint": "w", "coats": 1}
    r = estimate(j)
    ok("ceiling area 12 and one-coat flagged", r["lines"][1]["area"] == 12 and any(x["code"] == "ONE_COAT" for x in r["findings"]))
    ok("same paint summed across surfaces", r["buy"][0]["need"] == 8.2)
    j = json.loads(json.dumps(base)); j["waste"] = 0.1; j["rooms"][0]["texture"] = "rough"
    ok("rough + 10% waste: 7 x 1.25 x 1.1", estimate(j)["lines"][0]["volume"] == 9.62)
    j = json.loads(json.dumps(base)); j["rooms"][0].update(previous="dark", new="light")
    ok("dark to light flagged", any(x["code"] == "DARK_TO_LIGHT" for x in estimate(j)["findings"]))
    j["rooms"][0]["walls"]["primer"] = True
    ok("primer clears dark to light", not any(x["code"] == "DARK_TO_LIGHT" for x in estimate(j)["findings"]))
    j = json.loads(json.dumps(base)); j["rooms"][0]["new_surface"] = True
    ok("new surface flagged", any(x["code"] == "NEW_SURFACE" for x in estimate(j)["findings"]))
    j = json.loads(json.dumps(base)); j["rooms"][0]["openings"] = [{"w": 3, "h": 2.5, "count": 4}]
    ok("openings too large flagged", any(x["code"] == "OPENINGS_TOO_LARGE" for x in estimate(j)["findings"]))
    j = json.loads(json.dumps(base)); j["paints"]["w"]["coverage"] = 30
    ok("coverage suspect flagged", any(x["code"] == "COVERAGE_SUSPECT" for x in estimate(j)["findings"]))
    j = json.loads(json.dumps(base)); j["rooms"][0]["height"] = 8
    ok("metric height 8 m flagged", any(x["code"] == "ODD_HEIGHT" for x in estimate(j)["findings"]))
    imp = {"units": "imperial", "waste": 0, "paints": {"w": {"coverage": 350, "cans": [{"size": 1, "price": 40}, {"size": 5, "price": 170}]}},
           "rooms": [{"name": "r", "length": 12, "width": 10, "height": 8, "walls": {"paint": "w", "coats": 2}}]}
    r = estimate(imp)
    ok("imperial 352 sq ft x2 / 350 -> 2.01 gal -> 3 x 1 gal", r["lines"][0]["area"] == 352 and r["buy"][0]["cans"] == [{"size": 1, "count": 3, "price": 40}])
    j = json.loads(json.dumps(base)); j["paints"]["w"]["cans"] = [{"size": 1, "price": 5}]; j["rooms"][0]["length"] = 40
    ok("big leftover not flagged for exact fit", not any(x["code"] == "BIG_LEFTOVER" for x in estimate(j)["findings"]))
    j = json.loads(json.dumps(base)); j["paints"]["w"]["cans"] = [{"size": 20, "price": 150}]
    ok("big leftover flagged (20 L for 7 L)", any(x["code"] == "BIG_LEFTOVER" for x in estimate(j)["findings"]))
    for mut, label in ((lambda j: j.update(units="cubits"), "bad units"), (lambda j: j.update(paints={}), "no paints"),
                       (lambda j: j["rooms"][0].update(height=0), "zero height"),
                       (lambda j: j["rooms"][0]["walls"].update(paint="x"), "unknown paint"),
                       (lambda j: j["rooms"][0]["walls"].update(coats=1.5), "fractional coats"),
                       (lambda j: j["rooms"][0].update(texture="glitter"), "bad texture"),
                       (lambda j: j.update(rooms=[]), "no rooms")):
        j = json.loads(json.dumps(base))
        mut(j)
        try:
            estimate(j)
            ok(label + " rejected", False)
        except JobError:
            ok(label + " rejected", True)
    print(f"{sum(cases)}/{len(cases)} passed")
    return 0 if all(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Estimate paint quantity, cans to buy and cost for rooms.")
    ap.add_argument("file", nargs="?", help="painting job JSON")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("give a job JSON file or --self-test")
    try:
        res = estimate(json.load(open(a.file, encoding="utf-8")))
    except (OSError, json.JSONDecodeError, JobError, AttributeError, TypeError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(res, indent=2) if a.json else report(res), end="\n" if a.json else "")
    return 1 if any(x["severity"] == "HIGH" for x in res["findings"]) else 0


if __name__ == "__main__":
sys.exit(main())关于设计、演进和运营 GraphQL API 的、有明确立场的约定。
# 一名平台工程师的 GraphQL API 品味
- 围绕客户端用例和领域语言来设计 schema,而不是围绕数据库表。置信度:0.90
- 从 schema 为服务端和客户端生成类型(GraphQL Code Generator 或同类工具);绝不手写响应类型。置信度:0.90
- 仅在服务端始终能解析出值时才默认将字段设为非空;把依赖其他服务的字段设为可空,这样一个服务的失败不会把整个响应置为 null。置信度:0.80
- 每个 mutation 使用一个输入对象(createOrder(input: CreateOrderInput!))并返回一个 payload 类型,而不是裸实体。置信度:0.85
- 将可预期的业务错误作为 payload 中的类型化 union 成员返回(例如 OrderCreated | InsufficientStock);把顶层 errors 数组留给意外失败。置信度:0.75
- 列表用 Relay 风格的游标连接(edges、node、pageInfo)分页,并对 first/last 施加合理的上限。置信度:0.80
- 用 DataLoader 按请求批处理和缓存数据加载,消除 N+1 查询。置信度:0.95
- 在网关处强制执行查询深度和复杂度限制。置信度:0.90
- 在生产环境中对第一方客户端使用持久化查询(允许列表中的操作哈希)。置信度:0.80
- 除非 API 本就面向公众,否则在公开生产端点上禁用 introspection。置信度:0.70
- 以追加方式演进 schema,并用 @deprecated(reason: ...) 标记旧字段;绝不用 /v2 给端点做版本化。置信度:0.90
- 只有字段使用指标显示整整一个发布周期内无流量后,才移除已弃用字段。置信度:0.85
- 在 CI 中运行 schema diff 检查,并在出现破坏性变更时让构建失败。置信度:0.90
- 使用全局唯一的不透明 ID,并实现 Node 接口以支持重新获取。置信度:0.70
- 保持 resolver 精简:它们调用领域服务,授权逻辑放在该服务层,而不是 resolver 的 if 语句里。置信度:0.85
- 在每个客户端查询中为操作命名,让 trace、日志和指标可读。置信度:0.90
- 把 fragment 与使用它的 UI 组件放在一起。置信度:0.80
- 优先使用带校验的自定义标量(DateTime、URL、Email),而非普通 String。置信度:0.75
- 仅在真正实时的数据上使用 subscription;对于每隔几分钟才变化一次的数据,轮询就够了。置信度:0.70
- 只有当多个团队各自拥有独立的 subgraph 时才使用 federation;一个团队就意味着一个 schema。置信度:0.75
- 用 OpenTelemetry 追踪每个 resolver,并对慢字段告警,而不仅仅是对慢请求告警。置信度:0.80
- 为每个类型和字段编写 schema 描述文档;schema 就是 API 参考。置信度:0.85

